It includes the full SQL curriculum, advanced SQL, data modeling, system design, PySpark, dbt and behavioral preparation, along with the 12-week study system.
There’s also a 30-day guarantee if you work through the playbook and don’t feel measurably sharper at SQL and Data Engineer interviews.
One final thought
The interviewer isn’t going to give you the exact question you practiced last night.
They’re going to change the wording.
Add a constraint.
Introduce duplicates.
Add late-arriving data.
Change the scale.
Ask what happens when the pipeline fails.
Then ask you to explain why your solution works.
So don’t prepare only for questions.
Prepare for patterns.
Because the real interview skill isn’t:
“I’ve seen this exact question before.”
It’s:
“I haven’t seen this exact question before, but I recognize what it’s testing.”
Nobody fails a SQL interview because they don’t know the syntax. They fail because they stare at a question about “users with a 5-day login streak” and don’t recognize it as the exact same problem as “continuous subscription periods” and “consecutive winning games” — three phrasings of one pattern with one trick. The engineers who breeze through SQL rounds aren’t faster typists or syntax savants. They’ve seen the patterns enough times that a novel-sounding question instantly collapses into “oh, that’s gaps-and-islands” — and then the SQL is the easy part.
There are about ten of these patterns, and they cover the overwhelming majority of what product companies actually ask. This is a tour of all ten — the keyword that gives each one away, the core trick, real SQL, and the follow-up the interviewer asks when you get the first version right. The goal isn’t to memorize ten queries; it’s to build the recognition reflex so that in the room, you spend your time on the interesting variation instead of rediscovering the base pattern from scratch. If you want the deeper argument for why this recognition skill matters more than raw syntax, I’ve made it in why senior engineers write SQL differently.
One thing worth pinning to the wall before we start — the logical execution order of a query, because half of “why doesn’t my WHERE see my alias” questions dissolve once you know it: FROM → JOIN → WHERE → GROUP BY → aggregates → HAVING → SELECT → ORDER BY.
The whole game in one table: interviewers rarely name the pattern, but the words they use give it away. Train yourself to hear the keyword and reach for the trick.
1. Gaps and islands (consecutive sequences)
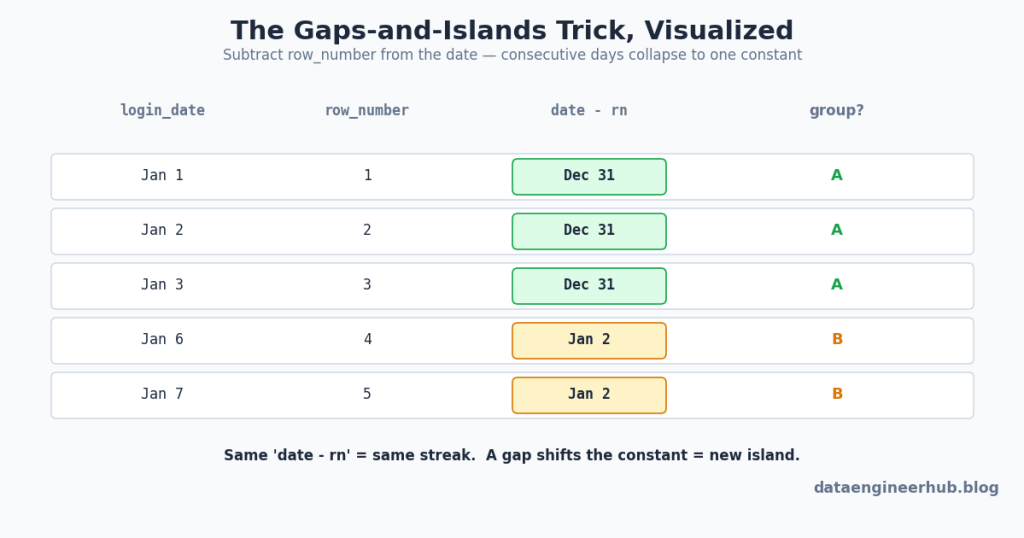
Keywords: consecutive, streak, continuous, sessions, “5 days in a row.” This is the one that trips people up most, and the trick is almost magical once it clicks: subtract a row number from the ordered date. Consecutive dates produce the same constant; a gap shifts it, creating a new group.
Why it works: for consecutive days the row number grows in lockstep with the date, so date − rn is constant. The moment a day is skipped, the constant jumps — and that jump is your new streak boundary.
WITH distinct_logins AS (
  SELECT DISTINCT user_id, login_date FROM logins
),
numbered AS (
  SELECT user_id, login_date,
         ROW_NUMBER() OVER (PARTITION BY user_id ORDER BY login_date) AS rn
  FROM distinct_logins
),
login_groups AS (
  SELECT user_id, login_date,
         DATE_SUB(login_date, INTERVAL rn DAY) AS grp
  FROM numbered
)
SELECT user_id,
       MIN(login_date) AS streak_start,
       MAX(login_date) AS streak_end,
       COUNT(*)        AS streak_length
FROM login_groups
GROUP BY user_id, grp
HAVING COUNT(*) >= 5
ORDER BY user_id;
The follow-up: “what if you need to detect the gaps themselves, not the streaks?” Switch to LAG() — compare each row to the previous login, flag where the difference isn’t 1 day, and cumulative-sum those flags into group IDs. Same idea, different vehicle. Note the DISTINCT up front: duplicate logins on the same day would silently break the row-number arithmetic.
2. Top-N per group
Keywords: top 3 per department, highest/lowest per group, latest record, first/last. The single most common window-function question. Partition by the group, order by the metric, filter on the rank.
WITH ranked AS (
  SELECT *,
         ROW_NUMBER() OVER (PARTITION BY department ORDER BY salary DESC) AS rn
  FROM employees
)
SELECT * FROM ranked WHERE rn <= 3;
The follow-up you must nail: “what if two people tie on salary?” That’s the interviewer probing whether you know the three ranking functions — and this is one of the most common trip-ups, so know it cold: ROW_NUMBER() gives 1,2,3 with an arbitrary tiebreaker; RANK() gives 1,1,3 (ties share a rank, next rank skips); DENSE_RANK() gives 1,1,2 (ties share, no gap). If the question is “top 3 salaries” and ties should all count, you want DENSE_RANK(), not ROW_NUMBER(). For the “latest record per user” variant, it’s the identical shape with ORDER BY created_at DESC and WHERE rn = 1.
3. Running totals / cumulative metrics
Keywords: running total, cumulative, so far, progressive. The frame does the work: SUM(x) OVER (ORDER BY dt ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW).
WITH daily_revenue AS (
  SELECT DATE(created_at) AS order_date, SUM(amount) AS revenue
  FROM orders
  GROUP BY DATE(created_at)
)
SELECT order_date,
       SUM(revenue) OVER (
         ORDER BY order_date
         ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
       ) AS running_total
FROM daily_revenue;
The follow-up: “now show each user’s running total and the global running total in the same query.” That tests whether you understand that two window functions can carry different PARTITION BY clauses side by side — a per-user frame partitioned by user_id, and a global frame with no partition — which usually means aggregating to user-day and day grains first, then combining.
4. Event → state transformation
Keywords: headcount over time, active subscriptions per day, “build the metric then track it.” Here the metric doesn’t exist in the data — you construct it from events. The classic is daily headcount: turn each hire into +1 and each termination into −1, then take a running sum over a date spine.
WITH RECURSIVE date_spine AS (
    SELECT MIN(hire_date) AS dt FROM employee
    UNION ALL
    SELECT DATE_ADD(dt, INTERVAL 1 DAY) FROM date_spine
    WHERE dt < CURRENT_DATE()
),
changes AS (
    SELECT hire_date AS dt, +1 AS delta FROM employee
    UNION ALL
    SELECT termination_date AS dt, -1 AS delta
    FROM employee WHERE termination_date IS NOT NULL
),
daily_change AS (
    SELECT dt, SUM(delta) AS tdelta FROM changes GROUP BY dt
)
SELECT d.dt,
       SUM(COALESCE(c.tdelta, 0)) OVER (
         ORDER BY d.dt ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
       ) AS headcount
FROM date_spine d
LEFT JOIN daily_change c ON d.dt = c.dt
ORDER BY d.dt;
The “+1/−1 delta then running sum” trick generalizes to any state-from-events problem: concurrent sessions, active subscriptions, inventory on hand.
5. Rolling / moving windows
Keywords: 7-day moving average, 30-day active users, trailing metric. Same window machinery as running totals, but a bounded frame. The gotcha that separates candidates: ROWS BETWEEN 6 PRECEDING AND CURRENT ROW is 7 rows, not 6.
SELECT sale_date, daily_sales,
       AVG(daily_sales) OVER (
         ORDER BY sale_date
         ROWS BETWEEN 6 PRECEDING AND CURRENT ROW
       ) AS moving_avg_7d
FROM daily_sales;
Window frames are worth truly internalizing, because half these patterns are just different frame boundaries over the same OVER() skeleton:
Every rolling metric is just a choice of frame boundaries relative to the current row. And the ROWS-vs-RANGE distinction at the bottom is a favorite senior-level probe — worth knowing why one is deterministic.
The ROWS-vs-RANGE trap: the default frame for SUM() OVER (ORDER BY dt) is actually RANGE, which groups all rows sharing the same ORDER BY value into one step — so two orders on the same date both get the day-end total, not their individual accumulation. ROWS treats each physical row independently. For running totals and time series, prefer ROWS to avoid unintended grouping on ties; being able to explain that difference unprompted signals real depth.
6. Cohort / retention analysis
Keywords: retention, cohort, week 0 / week 1, signup behavior. Ubiquitous at product companies. The shape is always: assign each user a cohort (their first-activity period), then measure activity by offset from that cohort.
WITH user_cohort AS (
  SELECT user_id, DATE_TRUNC('week', MIN(activity_date)) AS cohort_week
  FROM user_activity GROUP BY user_id
),
user_activities AS (
  SELECT a.user_id, c.cohort_week,
         DATE_TRUNC('week', a.activity_date) AS activity_week
  FROM user_activity a
  JOIN user_cohort c ON a.user_id = c.user_id
),
cohort_size AS (
  SELECT cohort_week, COUNT(DISTINCT user_id) AS total_users
  FROM user_cohort GROUP BY cohort_week
)
SELECT ua.cohort_week,
       DATEDIFF('week', ua.cohort_week, ua.activity_week) AS weeks_since_signup,
       COUNT(DISTINCT ua.user_id) AS active_users,
       COUNT(DISTINCT ua.user_id) * 1.0 / cs.total_users AS retention_rate
FROM user_activities ua
JOIN cohort_size cs ON ua.cohort_week = cs.cohort_week
GROUP BY ua.cohort_week, weeks_since_signup, cs.total_users
ORDER BY ua.cohort_week, weeks_since_signup;
The three-CTE structure — cohort assignment, activity-with-offset, cohort size for the denominator — is the reusable skeleton. Retention rate is just active-at-offset divided by the week-0 size.
7. Self-join logic
Keywords: compared to previous, more than their manager, bought A but not B. Any time you compare rows within the same table. The “A but not B” version is a clean anti-join:
SELECT DISTINCT a.user_id
FROM purchases a
LEFT JOIN purchases b
  ON a.user_id = b.user_id AND b.product = 'B'
WHERE a.product = 'A' AND b.user_id IS NULL;
The trap here is NULLs. The instinct is often WHERE user_id NOT IN (SELECT user_id FROM purchases WHERE product='B') — but if that subquery returns even one NULL, NOT IN yields zero rows, silently. The LEFT JOIN ... IS NULL anti-join above is immune. Many “compare to previous row” self-joins are also better expressed with LAG(), which is cheaper than a correlated subquery and reads more clearly.
8. Time-series expansion (date spine)
Keywords: daily trend, fill missing dates, continuous timeline, “even days with zero.” The fix for gaps in a report is to generate the complete calendar and LEFT JOIN your data onto it, so missing periods become explicit zeros instead of vanishing rows.
WITH RECURSIVE months AS (
    SELECT DATE_FORMAT(MIN(hire_date), '%Y-%m-01') AS month_start FROM employees
    UNION ALL
    SELECT DATE_ADD(month_start, INTERVAL 1 MONTH) FROM months
    WHERE month_start < DATE_FORMAT(CURRENT_DATE(), '%Y-%m-01')
)
SELECT m.month_start, COALESCE(SUM(x.metric), 0) AS metric
FROM months m
LEFT JOIN some_table x ON DATE_FORMAT(x.dt, '%Y-%m-01') = m.month_start
GROUP BY m.month_start
ORDER BY m.month_start;
The production aside worth saying out loud: recursive date spines that recompute headcount by rescanning all employees every month are fine in an interview but expensive at scale. Mentioning that you’d back this with a precomputed monthly_headcount snapshot table in production — built by an incremental pipeline rather than recomputed each run — is exactly the kind of comment that separates a senior candidate, and it ties directly to not reprocessing what didn’t change.
9. Percentiles / distribution
Keywords: top 10%, percentile, ranking distribution. This is where NTILE(), PERCENT_RANK(), and DENSE_RANK() live. “Top 10% of employees by rating” has a naive form and a fair form, and the interviewer usually wants the fair one:
-- Fair version: handles ties at the cutoff correctly
WITH latest_rating AS (
  SELECT emp_id, rating,
         ROW_NUMBER() OVER (PARTITION BY emp_id ORDER BY review_date DESC) AS rnk
  FROM performance_reviews
),
ranked AS (
  SELECT *,
         DENSE_RANK() OVER (ORDER BY rating DESC) AS bucket,
         COUNT(*)     OVER () AS total_count
  FROM latest_rating WHERE rnk = 1
)
SELECT * FROM ranked WHERE bucket <= CEIL(0.10 * total_count);
NTILE(10) forces exactly ten equal-sized buckets (take bucket 1); the DENSE_RANK approach is fairer when many people share the boundary rating. The killer follow-up is point-in-time correctness: “employees change departments over time — attribute each rating to the department they were in then.” That forces a slowly-changing-dimension join on a date range (start_date <= review_date < end_date) instead of a naive join to the employee’s current department — and getting that right is a strong signal.
10. Detect overlapping date ranges
Keywords: booking conflicts, overlapping subscriptions, double-booked, schedule clash. The elegant move is to reason about when ranges don’t overlap, then invert. Two ranges miss each other only if one ends before the other starts:
-- Non-overlap:  a.end < b.start  OR  b.end < a.start
-- Invert (De Morgan) -> the standard overlap condition:
SELECT s1.customer_id,
       s1.subscription_id AS sub_1,
       s2.subscription_id AS sub_2
FROM subscriptions s1
JOIN subscriptions s2
  ON s1.customer_id = s2.customer_id
 AND s1.subscription_id < s2.subscription_id   -- avoid self- and duplicate pairs
 AND s1.end_date >= s2.start_date
 AND s2.end_date >= s1.start_date;
Two details interviewers check: the s1.id < s2.id condition (so you don’t compare a row to itself or count each pair twice), and that you derived the overlap condition rather than memorized it — walking through the two non-overlap cases and applying De Morgan’s law is the move that earns the nod.
Putting it together: the combined question
Real interviews often stack two or three patterns. “Monthly revenue for completed 2025 orders, with the change vs the previous month, showing all 12 months even when revenue is zero” is three patterns at once: conditional filtering, a date spine (all 12 months), and LAG() for the month-over-month delta — over a base that first aggregates order_items to order grain before summing to month grain. If you can see it as “aggregate → spine → LAG” instead of one intimidating blob, you’ve already won. The recognition reflex is the whole skill; the syntax is just spelling.
The gotchas nobody warns you about
NOT IN with a NULL returns nothing. One NULL in the subquery and NOT IN silently yields zero rows. Use NOT EXISTS or a LEFT JOIN ... IS NULL anti-join for exclusions, every time.
ROWS ≠ RANGE, and the default is RANGE.SUM() OVER (ORDER BY dt) groups tied values into one step. For a true row-by-row running total, spell out ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW.
“6 PRECEDING” is a 7-row window. Off-by-one on frame bounds silently produces the wrong average. Count the current row.
ROW_NUMBER vs RANK vs DENSE_RANK is a tie question in disguise. When the interviewer says “what if they tie,” they’re testing which one you’d swap to. Have the 1,2,3 / 1,1,3 / 1,1,2 distinction ready.
Wrapping a date column in a function kills index/pruning use. Prefer hire_date >= DATE_SUB(CURRENT_DATE(), INTERVAL 6 MONTH) over TIMESTAMPDIFF(MONTH, hire_date, ...) <= 6 — same logic, but the range predicate can use metadata the function form throws away.
The one principle
You don’t pass a SQL interview by knowing more syntax — you pass it by recognizing that the strange-sounding question in front of you is one of about ten patterns you’ve already solved a dozen times. Learn the keyword that gives each pattern away, learn the one core trick behind it, and practice the recognition until it’s instant. Then the interview stops being a memory test and becomes what it should be: a conversation about the interesting variation, conducted in a language you already speak fluently.
Almost every data team says it’s “doing medallion architecture.” Look under the hood and most of them aren’t — they have a Bronze layer that’s a dumping ground, a Silver layer that’s Bronze with nicer column names, and a Gold layer business users technically have access to but can’t actually use. That gap between the tidy Bronze → Silver → Gold diagram in Confluence and the thing that pages someone at 3 a.m. isn’t a sign the teams are sloppy. It’s a sign the pattern itself has load-bearing cracks that only show up at scale.
To be clear up front: medallion is not bad. It solved a genuine problem, and for a lot of teams it’s still the right default. But it’s now old enough, and deployed widely enough, that the failure modes are well documented — and a wave of 2025–2026 writing (including Adam Bellemare’s widely-shared “The End of the Bronze Age”) has moved from “here’s how to do medallion” to “here’s where medallion breaks and what comes next.” This is a practitioner’s tour of both halves: what the pattern actually solved, the specific places it cracks, and the shift-left / data-product thinking that’s emerging as the alternative — without pretending the alternative is free.
TL;DR
→ Medallion (Bronze/Silver/Gold) solved a real problem: it gave data-lake chaos a legible, staged structure with progressive quality guarantees and clear replay points.
→ Its core weakness is that it’s a multi-hop pull architecture — the consumer owns data access, and cleaning happens repeatedly downstream instead of once at the source.
→ Every hop re-reads, re-processes, and re-writes the same data, so you pay storage and compute for the same record two or three times over.
→ The Bronze layer is fragile: it’s tightly coupled to source schemas, so an upstream column rename can silently break everything downstream.
→ In practice, Silver often collapses into “Bronze with better names,” and Gold tables ship that no one can actually consume — the layers stop earning their keep.
→ The emerging alternative is shift-left: clean and contract the data once, near the source, as a reusable data product serving both analytical and operational consumers.
→ This isn’t a migration you rush. Medallion is still fine for many teams; shift-left trades pipeline cost for organizational and contract discipline you have to actually be able to sustain.
What medallion actually solved
Before piling on, give the pattern its due, because the reasons it won are the reasons it’s still everywhere. Data lakes started as swamps: raw files dumped into object storage with no structure, no quality guarantees, and no obvious place for any given transformation to live. Medallion imposed a legible order on that chaos. Bronze is the raw landing zone, a faithful mirror of the source. Silver is cleaned, deduplicated, conformed data organized around business entities. Gold is denormalized, read-optimized, application-aligned output. Three layers, quality rising left to right, each with a clear job.
That structure bought three real things. It gave teams a shared vocabulary — “is this a Silver table?” is a meaningful question. It created natural replay points — when something breaks, you can reprocess from Bronze rather than re-ingesting from the source. And it mapped cleanly onto the tooling, which is exactly why I’ve recommended a version of it for organizing transformation work in structuring dbt projects into staging, intermediate, and mart layers. None of that value evaporates because the pattern has limits. The point isn’t that medallion is wrong; it’s that its assumptions stop holding as scale and consumer count grow.
Where it cracks, crack #1: you pay for the same data three times
The most concrete flaw is cost, and it’s structural, not incidental. Medallion is a multi-hop architecture: to get from raw to usable, the same data is copied and reprocessed at each layer. Populating Bronze means reading and writing the data once. Producing Silver means reading Bronze, transforming, and writing again. Gold reads Silver and writes a third time. Each hop incurs its own storage, network, and compute bill — for what is, fundamentally, the same record getting progressively reshaped.
The multi-hop tax, animated: one logical record gets re-read, re-processed, and re-written at every medallion layer — you’re billed for storage and compute once per hop, not once per record.
On a small pipeline this is invisible. On a wide table with billions of rows and a short SLA, the triple-write becomes a line item someone in finance eventually circles in red. It compounds, too: an unsure consumer who can’t tell which layer to trust often just builds their own pipeline from the source, adding a fourth and fifth copy. The pattern that was supposed to reduce duplication quietly manufactures it. This is the same immutability-and-rewrite economics I dug into for how Snowflake stores data internally — every materialization is a real, billed rewrite, and medallion mandates three of them by design.
Crack #2: the Bronze layer is brittle by construction
Bronze is defined as a near-mirror of the source, which means it’s tightly coupled to the source’s schema — and tight coupling to something you don’t control is fragility by another name. When an upstream team renames a column, changes a type, or restructures a table, the Bronze ingestion and every transformation layered on top of it can break. The consumer, who owns the pull, absorbs all of that pain without any ownership or influence over the source model. It’s a reactive posture: you’re perpetually reacting to changes made by people who have no reason to warn you.
This is precisely the failure I walked through in how one renamed column kills a pipeline, and medallion structurally guarantees you’ll keep hitting it, because it puts the cleaning burden downstream of the schema you don’t own. The layers also have a way of quietly degrading: under deadline pressure, Silver becomes “Bronze with renamed columns and a dedupe,” and Gold becomes a table that technically exists but that no analyst can actually build a report from. When that happens, you’re paying the three-copy cost without getting the quality-progression benefit the copies were supposed to buy.
Crack #3: nothing gets reused for operational workloads
Medallion lives in the analytical world. The cleaning, standardizing, and modeling work all happens inside the analytics stack, processed by periodic batch jobs. That work is invisible and unusable to operational systems, which need low-latency access and can’t wait on a nightly batch. So operational teams build their own separate path to the same source data — duplicating the standardization logic, and widening the very operational-analytical divide the platform was supposed to bridge. You end up doing the same “what does a valid customer address look like” work twice, in two stacks, with two subtly different answers.
The emerging alternative: shift left
The through-line of every crack above is the same: cleaning happens repeatedly, downstream, owned by consumers who don’t control the source. Shift-left inverts that. Instead of each consumer pulling raw data and re-cleaning it, you do the cleaning and standardization once, as close to the source as possible, and publish the result as a reusable data product with an explicit contract.
The shift-left move: take the cleaning work you were doing in Bronze/Silver and do it once at the source as a contracted data product, reused by both analytical and operational consumers instead of re-copied down a chain.
Two ideas make this work. A data product is data published with the same care as any other product — owned, documented, discoverable, with a named owner who sits on the team that produces the source. A data contract is the formal agreement about that product’s schema, its evolution rules, and its SLAs, acting as a stable-but-evolvable API and a barrier between the producer’s internal model and everyone downstream. Cleaning once at the source kills the triple-copy cost, the contract kills the brittle-coupling problem (schema changes now go through an agreed evolution process instead of silently breaking you), and publishing the product in both streaming and table modes lets a single investment serve operational and analytical consumers at once. Open table formats like Apache Iceberg are a big part of why this is newly practical — you can materialize a table from a stream without making yet another copy, the same open-format shift I covered in the native-tables-to-Iceberg migration piece.
So should you rip out medallion? Almost certainly not yet
Here’s the honest counterweight, because the shift-left literature can read like a sales pitch. Shift-left doesn’t delete the work — it relocates it, and relocation has a cost the diagrams hide. Cleaning at the source means the source team now owns data-product responsibilities they may not want, staff for, or be organizationally incentivized to do. Data contracts require negotiation, governance, and social buy-in across teams that historically didn’t talk. For a legacy source you can’t modify, or an org where the producing team won’t cooperate, a full shift-left is simply not available, and you’ll end up doing the cleaning outside the source anyway — which looks a lot like Bronze with extra steps.
The realistic path is incremental: shift one high-value, high-pain dataset left, prove the contract model works socially and technically, and expand from there — while the rest of your medallion pipelines keep running. Medallion remains a perfectly good default for a single team with a manageable number of sources and consumers. The cracks matter most when you have many consumers, many sources, and a cost or trust problem that’s already biting. Match the architecture to that reality, not to whichever pattern is winning the current news cycle.
The gotchas nobody warns you about
Silver quietly becomes Bronze-with-better-names. If your Silver layer only renames columns and dedupes, you’re paying a full extra copy for cosmetic changes. Silver has to add real modeling and conformance or it isn’t earning its cost.
Consumer-owned pipelines multiply behind your back. When people can’t tell which layer to trust, they build their own path from the source. Every one of those is another copy and another maintenance burden you’ll inherit later.
Shift-left is an org change wearing an architecture costume. The hard part isn’t the streams or Iceberg tables — it’s convincing the source team to own a data product and honor a contract. If that social change isn’t real, the technical change won’t stick.
“We do medallion” is often aspirational. Audit what your layers actually contain before defending or replacing them. Many teams are debating a pattern they haven’t truly implemented.
Don’t confuse a data contract with a schema file. A contract includes evolution rules, ownership, and SLAs — who gets paged, and how the schema is allowed to change. A bare Avro or Parquet schema with none of that is documentation, not a contract.
The one principle
Medallion’s cracks all trace back to one root cause — it cleans data repeatedly, downstream, owned by whoever consumes it — and every serious alternative is really an argument about moving that work upstream to whoever produces it. Bronze/Silver/Gold isn’t a mistake to be ashamed of; it’s a pattern whose assumptions you should now hold consciously instead of by default. Know which crack is actually costing you — copies, brittleness, or duplicated operational work — and shift left exactly as far as your organization can sustain. The goal was never medallion, and it was never shift-left. It was relevant, trustworthy data at a cost you can defend.
I once inherited a revenue report that had been green for fourteen months. Every morning it ran, populated a dashboard, and nobody questioned it. Then a new CFO asked why the data warehouse said Q2 regional revenue was $4.1M while the finance system said $1.3M. Same source data. The query had no error, no failed test, no warning. It had one join. Somewhere upstream, an orders table was joined to order_items, and a downstream SUM was quietly counting each order’s total once for every line item on it. A three-line-item order got counted three times. For fourteen months.
The engineer who wrote it was competent. The SQL was readable. It followed every rule in the “write clean SQL” playbook — named columns, tidy formatting, sensible aliases. And it was still catastrophically wrong, because clean and correct are different things. That gap is what actually separates senior SQL from junior SQL, and it’s a deeper gap than the usual advice about CTEs and naming suggests. The readability stuff is real and I’ll get to it, but if that’s all you fix, you’ll write beautifully formatted queries that overstate revenue by 3x. Senior SQL is different along three axes at once — correctness, cost, and change-safety — and only the third is about how the code looks. This isn’t abstract, by the way: I’ve argued that SQL is the highest-leverage skill on a data team right now, and this is exactly why — the language is easy, the judgment is not.
TL;DR
→ A query that runs clean can still be wrong; the most expensive SQL bugs produce plausible numbers, not errors.
→ Track the grain of every CTE — joining before you aggregate is the single most common cause of silently inflated totals.
→ NOT IN (subquery) returns zero rows if the subquery contains a single NULL; seniors use NOT EXISTS for anti-joins.
→ Deduping with QUALIFY ROW_NUMBER() and a tie-broken ORDER BY is reproducible; SELECT DISTINCT and untied ROW_NUMBER are not.
→ Wrapping a filter column in a function (DATE(ts) = ...) and using SELECT * both defeat the engine’s ability to skip data, and that shows up on the bill.
→ CTEs aren’t just prettier — each one is a debugging checkpoint you can query in isolation when a number looks wrong.
→ Junior engineers optimize to make the query run; senior engineers optimize so the next change, and the next reader, don’t create a new bug.
Senior SQL isn’t clever SQL
There’s a myth that senior engineers write dense, impressive queries full of tricks. The opposite is true. The most senior SQL I’ve reviewed is almost boring to read — because the author spent their cleverness on being right and cheap, not on being concise. The comparison above captures the pattern: at every decision point there’s a lazy default that works on your laptop against 100 rows, and a deliberate choice that survives contact with production data. The rest of this article is the “why” behind the right-hand column, with real SQL for each.
Correctness #1: the grain trap that triples your revenue
This is the bug from the intro, and it’s worth seeing in code because it looks completely innocent. The business question: total spend per customer. There’s an orders table and an order_items table. Here’s the query that ran for fourteen months:
-- WRONG: order_total is counted once per line item
SELECT
    o.customer_id,
    SUM(o.order_total) AS total_spend
FROM orders o
JOIN order_items oi ON oi.order_id = o.order_id
WHERE o.status <> 'refunded'
GROUP BY o.customer_id;
The join changes the grain. Before the join, orders has one row per order. After joining order_items, an order with three line items becomes three rows — each carrying the full order_total. The SUM then adds that total three times. Nothing errors; the number is just inflated by however many items the average order has.
The join multiplied the rows; the SUM multiplied the money. The fix is to aggregate at the right grain before joining.
The senior version aggregates order_items down to one row per order first, so every later step operates on a known grain:
WITH order_revenue AS (              -- grain: one row per order
    SELECT
        oi.order_id,
        SUM(oi.quantity * oi.unit_price) AS order_total
    FROM order_items oi
    GROUP BY oi.order_id
)
SELECT
    o.customer_id,                   -- grain: one row per customer
    SUM(orv.order_total) AS total_spend
FROM orders o
JOIN order_revenue orv ON orv.order_id = o.order_id
WHERE o.status <> 'refunded'
GROUP BY o.customer_id;
The habit that prevents this bug isn’t a syntax rule — it’s asking “what is the grain of this result?” after every join and every CTE. Seniors annotate it, as in the comments above. This is the same class of silent failure I wrote about in why passing dbt tests still ship bad data: uniqueness and not-null tests would both pass on the wrong query above, because the rows really are unique and non-null. They’re just counted too many times.
Correctness #2: NOT IN will betray you
You need a win-back list: customers with no orders in the last 90 days. The obvious query:
-- WRONG if orders.customer_id contains any NULL
SELECT customer_id, email
FROM customers
WHERE customer_id NOT IN (
    SELECT customer_id
    FROM orders
    WHERE order_date >= CURRENT_DATE - 90
);
If a single row in that subquery has a NULL customer_id — a guest checkout, a bad load, a soft-deleted account — this query returns zero rows. Not an error. An empty result that looks like “nobody qualifies.” The reason is SQL’s three-valued logic: NOT IN is defined as “not equal to any,” and comparing anything to NULL yields UNKNOWN, which poisons the whole condition so no row is ever selected. This is spec-mandated behavior, documented in PostgreSQL’s logical operators reference, and it behaves the same across every compliant engine.
The senior default is an anti-join with NOT EXISTS, which is immune to the NULL problem because it tests row existence, not value equality:
SELECT c.customer_id, c.email
FROM customers c
WHERE NOT EXISTS (
    SELECT 1
    FROM orders o
    WHERE o.customer_id = c.customer_id
      AND o.order_date >= CURRENT_DATE - 90
);
Rule of thumb worth internalizing: reach for NOT EXISTS over NOT IN every time a subquery is involved, unless you have proven the column is non-nullable. It’s not a style preference; it’s a correctness guarantee.
Correctness #3: dedup that returns the same rows twice
Deduplication is where juniors reach for SELECT DISTINCT and seniors reach for a window function — and the difference is about determinism, not taste. Say raw_orders has duplicate order_ids from an at-least-once ingestion, and you want the latest version of each. DISTINCT can’t express “latest”; it just collapses fully identical rows. And ROW_NUMBER without a tie-break silently picks an arbitrary row when the sort column ties — so the same pipeline can emit different rows on different runs, which is a nightmare to debug.
The senior pattern uses QUALIFY to filter on a window function inline, with a deterministic ordering:
The second column in the ORDER BY is the tell. A junior stops at updated_at DESC; a senior adds a unique tie-breaker so that when two rows share an updated_at, the query still picks the same one every single run. Reproducibility is a correctness property, and non-deterministic SQL is a close cousin of the “same input, different output” problem — except here you can actually eliminate it.
Cost: write SQL the engine is allowed to skip
Correctness keeps you employed; cost keeps you promoted. On columnar cloud warehouses, two junior habits quietly multiply what a query scans. Consider:
-- Scans every column, every micro-partition
SELECT *
FROM events
WHERE DATE(event_ts) = '2026-07-01';
Two problems. SELECT * forces the engine to read every column, including fat JSON and audit fields nobody asked for. And wrapping event_ts in DATE() means the optimizer can’t use the raw timestamp to prune partitions — it has to compute a function over every row first. The senior rewrite selects only what it needs and expresses the filter as a half-open range on the bare column, which lets the engine skip whole partitions it knows can’t match:
SELECT event_id, user_id, event_type
FROM events
WHERE event_ts >= '2026-07-01'
  AND event_ts <  '2026-07-02';
Put rough numbers on it. Say events is 2 TB across 40 columns, roughly evenly sized, holding one year of data. The junior query scans close to the full 2 TB. Selecting only the three columns you need cuts that to about 150 GB (three of forty columns). Adding the prunable date range drops it to one day out of ~365 — on the order of 400 MB actually read. That’s a ~5,000x reduction in bytes scanned, on a warehouse you’re billed for by the second, from two changes that took ten seconds to make. This is the same discipline behind not rebuilding models that didn’t change, which is the whole premise of dbt state-based selection — and it’s why teams serious about spend even push analytics to cheaper engines like DuckDB for dev workloads.
Change-safety: CTEs as checkpoints, not decoration
This is the axis the “clean SQL” advice usually covers, and it’s genuinely important — just not sufficient on its own. Structuring a query as a sequence of named CTEs (recent_orders → order_revenue → customer_summary) does more than read nicely. Each CTE is a checkpoint you can inspect in isolation: when a customer is missing from the output, you don’t mentally execute a nested monster, you run SELECT * FROM order_revenue WHERE order_id = 8821 and walk the stages until the row disappears. That’s the difference between a five-minute debug and a fifty-minute one.
The other half of change-safety is treating your SELECT list as a contract. SELECT * in a model means that the day someone adds a gdpr_deletion_requested column upstream, it silently flows into every downstream dashboard — the exact class of break I covered in how one renamed column kills a pipeline. An explicit column list is a promise about what this query returns, and promises are what let the next engineer change things without fear. If you want this enforced at the project level rather than per query, the layering conventions in structuring dbt projects in Snowflake are the natural home for it.
The gotchas nobody warns you about
DISTINCT is often a fan-out cover-up. If you added SELECT DISTINCT to “fix” duplicate rows, you probably have a grain bug upstream and are papering over it. DISTINCT hides the symptom and keeps the doubled aggregates.
BETWEEN on timestamps is a silent off-by-one.event_ts BETWEEN '2026-07-01' AND '2026-07-02' includes midnight of the second day, double-counting boundary rows. Half-open ranges (>= and <) are the senior default for exactly this reason.
COUNT(column) and COUNT(*) are not the same.COUNT(col) skips NULLs; COUNT(*) counts rows. Using the wrong one turns a data-quality problem into a wrong metric that looks fine.
RANK and ROW_NUMBER dedup differently.RANK() assigns ties the same number, so QUALIFY RANK() = 1 can keep multiple rows per key. For “exactly one row per key,” it must be ROW_NUMBER().
ORDER BY inside a CTE or view is not guaranteed to hold. The engine is free to reorder unless the outermost query sorts. If order matters downstream, sort where the data is consumed, not where it’s defined.
The one principle
Junior engineers write SQL that returns the right answer today; senior engineers write SQL that can’t quietly start returning the wrong one. The clean formatting, the CTEs, the explicit columns — those are the visible surface. Underneath is a habit of assuming your data is messier than the demo, your query will be re-run on data you haven’t seen, and the next person to touch it won’t know what you knew. Write for that world, and “senior SQL” stops being a style and becomes a form of insurance.
A hiring manager I know keeps a folder of rejected portfolio links. Not to be cruel — to remember the pattern. Out of roughly forty SQL “projects” she reviewed for one analytics-engineer opening, thirty-one were the same customer-churn notebook off the same Kaggle CSV, with the same three queries, ending on the same bar chart. She stopped opening them after about the fifteenth. The one candidate she did call had used the identical dataset as everyone else — but she’d written a paragraph explaining that 4,200 rows had a tenure of zero and a churn flag of one, which is impossible, and how she decided to handle them. That paragraph got her the interview. The SQL didn’t.
That is the thing nobody tells you when you start building a data portfolio: the query is table stakes. Everyone can write a GROUP BY. What almost nobody does is show that they can think about data the way it actually behaves in production — dirty, contradictory, and full of rows that break your assumptions. If you’re weighing whether SQL is even worth the investment in an AI-saturated market, it still is; I’ve argued at length about why SQL quietly became the most valuable skill in the modern stack. This article is the follow-on: five projects genuinely worth building, the public repositories and datasets to build them from, and — the part that matters — what to add to each so it doesn’t land in the rejected folder.
TL;DR
→ Hiring managers reject SQL portfolios for sameness, not syntax errors; the differentiator is documented judgment about messy data, not a cleaner JOIN.
→ Five projects cover the skills employers actually screen for: churn analysis, a Bronze/Silver/Gold data warehouse, sales analysis, customer segmentation, and healthcare KPIs.
→ A Bronze/Silver/Gold data-warehouse build is the single highest-signal SQL portfolio project because it proves modeling and ETL thinking, not just querying.
→ Window functions (NTILE, RANK, ROW_NUMBER) separate a beginner portfolio from a mid-level one faster than any other SQL feature.
→ Use real, messy public data — NYC TLC trip records, open GitHub project datasets — instead of the pre-cleaned Kaggle CSV everyone else submitted.
→ Every project needs a written “what I found and what I’d do about it” section; a small, well-explained project beats a large one with no story.
→ You can run all five locally for free with DuckDB or SQLite — no cloud warehouse and no credit-card required.
Why most SQL portfolios get skipped in 30 seconds
Reviewers don’t read portfolios top to bottom. They scan for a reason to say no, because they have forty of them and one afternoon. A wall of SELECT statements with no narrative gives them that reason instantly. So does a project that’s obviously a tutorial you followed step-for-step, because a tutorial proves you can type, not that you can decide.
The uncomfortable truth is that clean, green output is not evidence of good work. I’ve written before about how tests can pass while you’re still shipping bad data, and the same trap applies to portfolios: a query that runs without error can still be answering the wrong question on data you never inspected. A reviewer who has been burned by exactly that in production is looking for the opposite signal — someone who checked.
This is also why I’m lukewarm on stacking certifications as a substitute for building things; I’ve made the full case for why a certificate rarely moves a hiring decision. A project where you can point at a specific decision you made — “I bucketed tenure this way because the raw values were bimodal” — does the thing a certificate can’t. It shows judgment.
So as you read the five projects below, treat the query as the easy 20%. The 80% that gets you hired is the layer on top: the data-quality checks, the edge cases you caught, and the plain-English conclusion.
The five projects worth building
These five map to the roles most people are actually applying for — analyst, analytics engineer, BI developer — and between them they exercise every SQL skill a screener looks for. For each one I’ve noted a real public repository or dataset to start from, and the one addition that lifts it above the crowd.
1. E-commerce customer churn analysis
Churn is the most common portfolio project for a reason: it’s a real business problem with a clear money consequence, and it maps cleanly to SQL. You take a table of customers with attributes like tenure, complaint counts, satisfaction scores, order frequency, coupon usage, and days since last order, and you find the patterns that predict who leaves. A good public starting point is the open-source Ecommerce Customer Churn Analysis repository, which ships the raw CSV and a full query file you can read, critique, and improve rather than copy.
The skills on display are aggregation, conditional logic, and segmentation. Here’s the kind of query that belongs in this project — churn rate bucketed by tenure, which immediately tells a retention story:
SELECT
    tenure_bucket,
    COUNT(*)                                  AS customers,
    SUM(churned)                              AS churned_customers,
    ROUND(100.0 * SUM(churned) / COUNT(*), 1) AS churn_rate_pct
FROM (
    SELECT
        customer_id,
        CASE WHEN churn = 1 THEN 1 ELSE 0 END AS churned,
        CASE
            WHEN tenure < 6  THEN '0-5 months'
            WHEN tenure < 12 THEN '6-11 months'
            WHEN tenure < 24 THEN '12-23 months'
            ELSE '24+ months'
        END AS tenure_bucket
    FROM ecommerce_churn
) t
GROUP BY tenure_bucket
ORDER BY churn_rate_pct DESC;
Run it and you get something like this:

+---------------+-----------+-------------------+----------------+
| tenure_bucket | customers | churned_customers | churn_rate_pct |
+---------------+-----------+-------------------+----------------+
| 0-5 months    |      1846 |               912 |           49.4 |
| 6-11 months   |      1204 |               331 |           27.5 |
| 12-23 months  |      1098 |               142 |           12.9 |
| 24+ months    |       503 |                28 |            5.6 |
+---------------+-----------+-------------------+----------------+
What to add that nobody else does: before you compute a single rate, profile the data and write down what’s wrong with it. Customers with a tenure of zero but a churn flag set. Satisfaction scores outside the documented range. Duplicate customer IDs. Then state your handling decision and why. That paragraph is the reason a reviewer keeps reading.
2. A Bronze/Silver/Gold data warehouse
If you build only one project from this list, build this one. It’s the highest-signal thing on the page because it proves you understand how real data systems are assembled — ingestion, cleansing, and modeling into fact and dimension tables — not just how to query a table someone else prepared. The SQL Data Warehouse Project by Data With Baraa is the gold-standard reference here: it’s MIT-licensed, has hundreds of forks, and walks the full Medallion (Bronze → Silver → Gold) architecture using ERP and CRM CSV sources loaded into a SQL database, then modeled into a star schema.
You’ll practice ETL sequencing, data cleaning, and dimensional modeling. If you want to understand the modeling layer more deeply — where the real design decisions live — my guide on structuring a warehouse project into staging, intermediate, and mart layers maps almost one-to-one onto Bronze/Silver/Gold, and it’ll help you explain why your layers are split the way they are.
What to add that nobody else does: a data catalog and naming conventions. Two short Markdown files — one documenting every column in your Gold tables, one stating your table/column naming rules — signal “I’ve worked on a team” louder than any query. It’s also the thing that separates a warehouse project from a pile of scripts.
3. Sales data analysis
Sales analysis connects SQL directly to business performance, which makes it the easiest project to narrate to a non-technical interviewer. You answer questions a real stakeholder asks: which products drive revenue, how revenue trends month over month, which customer cohorts spend the most, whether there’s seasonality. The skills are joins, date functions, sorting, filtering, and time-based grouping.
This is a great one to build on genuinely large, genuinely messy public data instead of a tidy sample. The NYC Taxi & Limousine Commission trip records are a government-published dataset running to millions of rows per month, with real quirks — negative fares, zero-distance trips, timestamps out of order. Treating trips as “sales” and analyzing revenue by hour, zone, and payment type gives you a portfolio piece at a scale most candidates never touch. And you don’t need a cluster to do it: I’ve made the case for why you should stop spinning up Spark for datasets this size — DuckDB will chew through a month of trip data on your laptop.
What to add that nobody else does: a “so what” for every chart. Don’t just show that December revenue is up. Say what a business would do about it. The analysis is the input; the recommendation is the deliverable.
4. Bank customer segmentation
Segmentation is where you graduate from beginner SQL to mid-level SQL, because it’s the natural home for window functions. You take a banking-style dataset of customers, transactions, and regions, and you rank customers by value, flag dormant versus active accounts, and score regional performance. Employers in fintech and financial analytics screen hard for CTEs, NTILE, RANK, and PARTITION BY — and this project shows all of them at once.
WITH customer_value AS (
    SELECT
        customer_id,
        region,
        SUM(transaction_amount) AS total_spend,
        COUNT(*)                AS txn_count,
        MAX(transaction_date)   AS last_txn
    FROM bank_transactions
    GROUP BY customer_id, region
)
SELECT
    customer_id,
    region,
    total_spend,
    NTILE(4) OVER (ORDER BY total_spend DESC)  AS value_quartile,
    RANK()   OVER (PARTITION BY region
                   ORDER BY total_spend DESC)  AS rank_in_region
FROM customer_value
ORDER BY total_spend DESC
LIMIT 5;
+-------------+---------+-------------+----------------+----------------+
| customer_id | region  | total_spend | value_quartile | rank_in_region |
+-------------+---------+-------------+----------------+----------------+
|       10427 | South   |    284119.50 |              1 |              1 |
|       10088 | West    |    271004.20 |              1 |              1 |
|       10391 | South   |    259847.75 |              1 |              2 |
|       10142 | North   |    244310.00 |              1 |              1 |
|       10265 | West    |    238900.10 |              1 |              2 |
+-------------+---------+-------------+----------------+----------------+
What to add that nobody else does: define your segments before you write the SQL, in business terms, and defend the thresholds. “High-value” meaning top quartile by spend is a choice; so is defining “dormant” as no transaction in 90 days. Writing down why you drew the lines where you did is the difference between analysis and arbitrary bucketing.
5. Healthcare data analysis
Healthcare rounds out the set because it proves you can work with domain-specific, meaningful data: patient records, conditions, hospitals, insurance providers, admission types, and billing. You explore which conditions are most common, how billing varies by condition, which hospitals see the most volume, and how admission types differ across patient groups. The SQL skills — grouping, filtering, joins, aggregates — overlap with sales analysis, but the domain framing shows range.
What to add that nobody else does: a KPI rollup with definitions. Healthcare reviewers care about correctness of metrics. Publishing a small set of KPIs (average length of stay, cost per admission type, readmission proxy) with an explicit definition for each shows you understand that a metric is only as good as its definition — the same discipline that keeps a real reporting layer trustworthy.
Where to get data that isn’t the same tired CSV
The fastest way to blend into the rejected folder is to use the exact pre-cleaned dataset every tutorial uses. Three better sources: open GitHub project repositories that ship their own raw CSVs (like the two linked above), government open-data portals such as the NYC TLC records for genuine scale and mess, and Kaggle for breadth when you want a specific domain. The rule of thumb: the messier and more real the source, the more your data-quality work has something to actually do — which is the whole point.
You do not need cloud infrastructure for any of this. All five projects run locally on DuckDB or SQLite for free, and if you later want to show you can operate against a warehouse without burning money, my walkthrough on querying warehouse data through DuckDB to cut costs covers the hybrid pattern. For the ingestion side of the warehouse project, a small Python loading script turns “I loaded CSVs” into “I built a repeatable pipeline.”
How to actually spend your time
Most people invert the effort. They spend 80% of their time writing more queries and 20% on everything else, then wonder why the portfolio reads like homework. Flip it. A realistic budget for one strong project looks closer to this: roughly 15% profiling and cleaning the data, 25% writing the core SQL, 20% catching and documenting edge cases, and 40% on the write-up — the README, the data-quality notes, and the plain-English conclusions. The queries are the cheapest part to produce and the least differentiating. The narrative is expensive, rare, and exactly what gets remembered.
This is also why one finished, deeply documented project beats five half-built ones. Depth is legible to a reviewer in a way that breadth isn’t. Five shallow churn notebooks read as one shallow churn notebook copied five times.
The gotchas nobody warns you about
A green query is not a correct query. The most dangerous portfolio bug is a query that runs, returns plausible numbers, and is silently wrong because you joined on a column with duplicates and fanned out your row counts. Always sanity-check totals before and after a join.
Averages lie on skewed data, and money is always skewed. “Average transaction value” across a banking dataset is nearly meaningless when a handful of whales dominate. Reach for medians and percentiles, and mention explicitly why you did — it signals statistical maturity.
Date handling is where portfolios quietly break. Time zones, mixed formats, and out-of-order timestamps in real datasets like the TLC records will wreck a naive monthly rollup. The candidate who noticed 200 trips with a drop-off before the pick-up looks far stronger than the one whose numbers were merely clean.
Schema assumptions rot the moment upstream data changes. If a column you depend on gets renamed or retyped, your whole analysis silently produces garbage — the exact failure mode I unpack in the piece on how a single renamed column kills a pipeline. Documenting the schema you built against is cheap insurance and a strong signal.
A dashboard is not a conclusion. Ending on a chart with no written interpretation is the most common way strong SQL gets wasted. The reviewer wants your read of the numbers, not a second job interpreting them.
The one principle
Your SQL proves you can query; your write-up proves you can think — and only one of those gets you hired. Pick one project from this list, use genuinely messy public data, and spend more time explaining your decisions than writing your queries. A small project with a documented point of view will beat a sprawling one with clean output and nothing to say, every single time.
Processing millions of food records taught me that data quality is rarely one clever cleaning function. It is a chain of small contracts: what a number means, which identifier owns a record, what a missing value means, and what an incremental update is allowed to change.
I learned this while building DietlyAPI, a nutrition API backed by more than 4.2 million indexed food records. Much of the catalog originates from Open Food Facts, a valuable worldwide crowdsourced database. That scale and openness are useful, but they also expose every awkward case a data pipeline eventually encounters: mixed units, incomplete labels, placeholder barcodes, duplicate products, implausible nutrition values, and partial updates.
This article explains the patterns that made the pipeline safer. The examples are simplified, but the failure modes are real.
Validation happens at more than one boundary in this pipeline — ingestion protects structure, serving enforces trust, converted here from the original mermaid flowchart.
TL;DR
→ Treating data import as one boolean is_valid check throws away useful information; structural validity, plausibility, and publish-readiness are separate questions that deserve separate gates.
→ Store nutrient values in one consistent unit contract (per 100g) and keep serving size as separate metadata, so no consumer has to guess what a number means.
→ Null, zero, and “omitted from this update” are three different states — collapsing them into one makes incomplete records look complete and produces false-confidence calculations downstream.
→ Relational checks (does sugar exceed total carbs? does the stated calorie count match the macro math?) catch bad records that individually pass simple range checks.
→ Partial updates are more dangerous than full imports: a naive upsert that blindly assigns every incoming field can silently null out good data the source simply didn’t include that day.
→ At 4.2 million records, rare edge cases stop being rare — the highest-value tests target invariants like “an omitted delta nutrient preserves the stored value,” not just a successful job exit code.
The Pipeline Is a Series of Trust Boundaries
My first mistake was thinking about the import as one operation:
Read a source file, clean each row, and insert it.
In production, there are several separate decisions:
Can the source record be parsed?
Can its fields be mapped to a stable internal schema?
Is the record identifiable across future imports?
Are its values plausible enough to store?
Is it complete and trustworthy enough to rank highly or publish?
Can a later partial update safely modify it?
Treating those questions as one boolean is_valid check loses useful information. A record with a name and barcode but no calories may still be worth retaining. A record with impossible calories should not appear in a “popular foods” response. A partial daily update should not delete fields simply because the source omitted them.
The important detail is that validation happens at more than one boundary. Ingestion protects the database from malformed structure. Serving and publishing apply stricter quality rules appropriate to their users.
Lesson 1: Define the Unit Contract Before Writing Transformations
Nutrition sources frequently mix:
values per 100 grams;
values per serving;
grams, milligrams, and micrograms;
kilocalories and kilojoules;
numbers and human-readable strings such as 1 cup (240 g).
If these representations leak into the application layer, every consumer must guess what each number means. That guarantees inconsistent calculations.
Dietly’s internal contract stores nutrient values per 100 grams. Serving information is separate metadata:
calories_kcal  = energy per 100 g
protein_g      = protein per 100 g
sodium_mg      = sodium per 100 g
serving_size_g = optional weight of one stated serving
serving_desc   = original display text, such as "1 cup (240 g)"
That separation matters. A serving_size_g of 30 does not mean the stored calories are already scaled to 30 grams. Consumers can calculate a serving explicitly:
Unit conversion should occur once, close to ingestion:
def to_milligrams(value, unit):
    if value is None:
        return None

    normalized = (unit or "g").lower()
    if normalized == "mg":
        return value
    if normalized in {"µg", "mcg", "ug"}:
        return value / 1000
    if normalized in {"g", ""}:
        return value * 1000

    # Unknown is not the same as zero.
    return None
The final line is deliberately conservative. Silently guessing an unfamiliar unit creates a valid-looking wrong value, which is harder to detect than a null.
The same rule applies to failed parsing:
def parse_number(raw):
    if raw is None or not str(raw).strip():
        return None
    try:
        return float(raw)
    except ValueError:
        return None
In nutrition data, zero is a claim. Null means “not known.” Converting missing values to zero makes incomplete products appear complete and can produce dangerously confident downstream calculations.
Lesson 2: Validate Relationships, Not Only Individual Columns
A schema can confirm that calories are numeric, but it cannot tell you whether 6,000 kcal per 100 grams is credible. Simple range checks catch many broken rows:
Field
Plausible range
calories_kcal
0 – 900
protein_g
0 – 100
fat_g
0 – 100
carbs_g
0 – 100
fiber_g
0 – 100
sugar_g
0 – 100
serving_size_g
0 – 2000
RANGES = {
    "calories_kcal": (0, 900),
    "protein_g": (0, 100),
    "fat_g": (0, 100),
    "carbs_g": (0, 100),
    "fiber_g": (0, 100),
    "sugar_g": (0, 100),
    "serving_size_g": (0, 2000),
}

def outside_range(record):
    failures = []
    for field, (low, high) in RANGES.items():
        value = record.get(field)
        if value is not None and not low <= value <= high:
            failures.append(f"{field}:outside_range")
    return failures
However, many bad records contain values that are individually believable but mutually inconsistent. Relational checks are more powerful:
def plausibility_failures(food):
    failures = []

    if (
        food.get("sugar_g") is not None
        and food.get("carbs_g") is not None
        and food["sugar_g"] > food["carbs_g"] + 0.5
    ):
        failures.append("sugar_exceeds_carbohydrate")

    if (
        food.get("saturated_fat_g") is not None
        and food.get("fat_g") is not None
        and food["saturated_fat_g"] > food["fat_g"] + 0.5
    ):
        failures.append("saturated_fat_exceeds_total_fat")

    macros = ("protein_g", "carbs_g", "fat_g")
    if food.get("calories_kcal") and all(food.get(x) is not None for x in macros):
        estimated = (
            food["protein_g"] * 4
            + food["carbs_g"] * 4
            + food["fat_g"] * 9
        )
        stated = food["calories_kcal"]
        if abs(estimated - stated) > max(120, stated * 0.5):
            failures.append("energy_macro_mismatch")

    return failures
These tolerances are intentionally broad. Food labels round values, fiber and alcohol complicate energy calculations, and source conventions vary. The purpose is not to “correct” every label mathematically. It is to catch extreme contradictions before they are promoted, summarized, or used to generate authoritative-looking content.
That led to another useful distinction:
Hard structural checks decide whether a record can enter storage.
Quality gates decide whether it can appear in high-trust surfaces.
Ranking signals decide which acceptable record should appear first.
A sparse record may remain searchable without being selected for a featured-food endpoint. Keeping these policies separate avoids throwing away potentially useful data.
Lesson 3: Identity Is Not the Same as a Barcode
It is tempting to use a barcode as the universal product key. In real data, that fails for several reasons:
some records have no barcode;
scanner noise and hand-entered placeholders exist;
the same source record may be updated while keeping its source identifier;
different sources can use different identifiers for the same food;
similar products are not necessarily the same product.
Dietly uses source provenance as the idempotency key:
CREATE UNIQUE INDEX idx_foods_source_id
    ON foods (source, source_id);
This answers a narrow but essential question: “Have I already imported this exact source record?” It does not pretend to solve global entity resolution.
Known placeholder barcode patterns are removed rather than used for lookups. Returning no barcode match is safer than returning a confidently wrong product.
Product deduplication then becomes a separate serving-layer concern. Search candidates can be grouped using a normalized name key — case-folding, punctuation removal, and collapsing repeated words — and the best row can be selected using signals such as:
presence of an image;
serving information;
complete core macros;
realistic ranges;
number of populated nutrient fields;
source confidence.
This approach does not claim that all duplicates disappear. Instead, it prevents weak duplicates from dominating common queries while preserving the original rows and their provenance.
Lesson 4: Partial Updates Are More Dangerous Than Full Imports
The most instructive failure appeared in the incremental pipeline. During one update, eight already-published food pages lost their calorie values and dropped out of the page build. The import had completed successfully; the data had still become worse.
A full export contains a broad set of fields. A daily delta may contain only the fields that are currently present upstream. If an upsert blindly assigns every incoming field, an omitted value becomes SQL NULL and can erase good data already stored.
The unsafe version looks reasonable:
ON CONFLICT (source, source_id) DO UPDATE SET
    calories_kcal = EXCLUDED.calories_kcal,
    protein_g     = EXCLUDED.protein_g,
    fat_g         = EXCLUDED.fat_g;
But it treats “not included in this update” as “delete the existing value.”
The safer policy for Dietly’s source is to preserve stored nutrition when a delta omits it:
ON CONFLICT (source, source_id) DO UPDATE SET
    name          = EXCLUDED.name,
    calories_kcal = COALESCE(EXCLUDED.calories_kcal, foods.calories_kcal),
    protein_g     = COALESCE(EXCLUDED.protein_g, foods.protein_g),
    fat_g         = COALESCE(EXCLUDED.fat_g, foods.fat_g),
    carbs_g       = COALESCE(EXCLUDED.carbs_g, foods.carbs_g),
    image_url     = COALESCE(EXCLUDED.image_url, foods.image_url),
    updated_at    = NOW()
WHERE foods.name IS DISTINCT FROM EXCLUDED.name
   OR foods.calories_kcal IS DISTINCT FROM
      COALESCE(EXCLUDED.calories_kcal, foods.calories_kcal)
   OR foods.protein_g IS DISTINCT FROM
      COALESCE(EXCLUDED.protein_g, foods.protein_g)
   OR foods.fat_g IS DISTINCT FROM
      COALESCE(EXCLUDED.fat_g, foods.fat_g)
   OR foods.carbs_g IS DISTINCT FROM
      COALESCE(EXCLUDED.carbs_g, foods.carbs_g);
There are two protections here.
First, COALESCE encodes the meaning of a missing delta field. This policy is source-specific: if an upstream system supports explicit deletion, it should send a deletion marker rather than relying on null.
Second, IS DISTINCT FROM avoids rewriting unchanged rows. At millions of records, unnecessary updates create write-ahead-log traffic, dead tuples, index churn, and disk pressure. Idempotency is an operational feature, not only a correctness property.
The delta cursor is committed after each successfully processed file. If a job stops halfway through a series, it resumes from the last committed file instead of replaying the entire history or skipping uncommitted work.
Lesson 5: Preserve Provenance All the Way to the API
Once several sources share one table, it becomes easy to flatten away where a value came from. That makes later debugging and trust decisions much harder.
Each Dietly row retains fields such as:
source
source_id
confidence
created_at
updated_at
Provenance supports practical questions:
Which source produced this suspicious value?
Can the record be re-imported deterministically?
Should one source rank above another for this query?
Which rows were affected by yesterday’s delta?
What attribution or license applies downstream?
Confidence is best treated as a ranking input, not proof that a value is correct. A high-confidence source can still contain an error, while an incomplete crowdsourced record can still be useful.
Open Food Facts data is available under the Open Database License, so attribution and downstream license obligations also need to survive the journey from source to product.
Lesson 6: Test the Failure Policy, Not Just the Happy Path
Row counts and successful job exits are weak evidence of pipeline health. A pipeline can finish successfully after replacing thousands of values with null.
The highest-value tests in this system target invariants:
importing the same record twice does not create a duplicate;
an omitted delta nutrient preserves the stored value;
a changed nutrient updates the stored value;
an unchanged record is not rewritten;
placeholder barcodes cannot produce a false lookup;
values outside realistic ranges cannot enter high-trust responses;
public response fields remain backward-compatible.
For SQL generation, even a focused regression test can prevent a repeat:
def test_partial_updates_preserve_nutrition():
    sql = UPSERT_SQL.upper()
    for column in ("CALORIES_KCAL", "PROTEIN_G", "FAT_G", "CARBS_G"):
        assert f"COALESCE(EXCLUDED.{column}" in sql
In addition, record rejection or suppression reasons as categories rather than a single invalid count:
Their trends reveal upstream schema changes faster than inspecting random rows. A sudden jump in invalid_number, for example, may indicate a delimiter or unit change rather than a genuine decline in data quality.
A Practical Checklist
Before calling a large ingestion pipeline reliable, I now ask:
Does every numeric field have a documented unit and reference basis?
Are null, zero, deletion, and omission distinct states?
Is the idempotency key tied to source identity?
Are structural validation, quality gating, and ranking separate?
Do checks cover relationships between fields?
Can partial updates erase existing values?
Do unchanged upserts avoid physical rewrites?
Is source provenance retained in storage and responses?
Can interrupted incremental jobs resume safely?
Do tests reproduce the pipeline’s previous failures?
At 4.2 million records, rare edge cases stop being rare. A one-in-a-million parsing issue is no longer hypothetical, and a harmless-looking upsert can become millions of unnecessary writes.
The central lesson was simple: reliable data quality does not mean making every source row perfect. It means making uncertainty explicit, containing bad values, preserving what is already known, and ensuring that retries produce the same result.
That is less glamorous than the word “pipeline” sometimes suggests. It is also what makes the pipeline dependable.
In 2018, a wave of Medium posts declared SQL obsolete. NoSQL was the future. Python would handle everything. Data lakes would make relational thinking irrelevant. The hot take had a good run.
Then AI happened — and SQL came back harder than ever.
Today, SQL is the connective tissue of every serious AI data stack. It feeds the training pipelines that power large language models. It validates the outputs of ML systems. It runs inside every dbt transformation, every Snowflake query, every Airflow DAG that touches structured data. And in 2026, the rise of text-to-SQL AI agents means that understanding SQL deeply is now more important than ever — not less.
TL;DR
For years, pundits called SQL a dying skill. They were wrong. In the AI era, SQL is experiencing a full renaissance — powering LLM pipelines, text-to-SQL agents, dbt models, and Snowflake-backed AI workflows. Senior data engineers with strong SQL command salaries up to $179K. Here’s why SQL is now the most career-defining skill in tech.
The Death of SQL Was Always a Myth
The “SQL is dying” narrative was never based on actual hiring data. It was based on hype cycles. Every new database technology generated thinkpieces about how SQL would be replaced — first by MapReduce, then document stores, then graph databases, then vector DBs.
None of it displaced SQL as the default language of data work. And there’s a structural reason for that: relational thinking maps directly to how business data is structured. Revenue by region. Users by cohort. Transactions by date. These aren’t graph problems or document problems — they’re table problems, and SQL solves them with surgical precision.
What the doomsayers missed is that SQL doesn’t compete with new technologies — it sits on top of them. Snowflake runs SQL. BigQuery runs SQL. Delta Lake and Apache Iceberg are queried with SQL. Even Snowflake’s AI features are invoked through SQL-adjacent interfaces.
“SQL is eternal — it’s the new English of data systems.”
Why AI Made SQL More Valuable, Not Less
Here’s the counterintuitive reality: the rise of AI has created more demand for SQL, not less. There are three reasons why.
1. LLMs Speak SQL
The text-to-SQL category — where natural language queries get translated into executable SQL — is one of the fastest-growing areas in AI tooling. Tools like Vanna.ai, DataGrip’s AI Assistant, and BlazeSQL are putting SQL generation in the hands of non-technical users.
But here’s the catch: AI-generated SQL still needs a human expert to validate it. A model hitting 80–85% accuracy on clean data sounds impressive until you realize that the 15% failure rate in production can silently corrupt dashboards, ML training sets, and financial reports. Someone with deep SQL knowledge has to own that validation layer.
2. AI Models Are Trained on SQL Pipelines
Every serious ML workflow has a data preparation layer. That layer runs on SQL. Whether it’s dbt transformations cleaning feature tables, Snowflake views materializing training datasets, or window functions creating temporal sequences for time-series models — SQL is the engine underneath.
A data engineer who can write optimized SQL is not just a “database person.” They’re the person keeping AI models from training on garbage data. That’s a mission-critical role in 2026.
3. The Semantic Layer Runs on SQL
As AI agents get wired into data stacks, the “semantic layer” — a metadata-rich translation between business concepts and database schemas — has become critical infrastructure. dbt’s Semantic Layer, Snowflake’s Cortex, and tools like Cube.js all expose this layer through SQL-compatible interfaces. Understanding SQL deeply is what lets engineers build and maintain this layer correctly.
The Modern SQL Skill Set Is Not What You Learned in 2015
Basic SELECT * FROM table fluency is table stakes. What the market pays a premium for in 2026 is a completely different tier of SQL mastery.
WITH user_activity AS (
  SELECT
    user_id,
    event_date,
    revenue,
    SUM(revenue) OVER (
      PARTITION BY user_id
      ORDER BY event_date
      ROWS BETWEEN 6 PRECEDING AND CURRENT ROW
    ) AS rolling_7d_revenue,
    DATEDIFF('day', MAX(event_date) OVER(PARTITION BY user_id), CURRENT_DATE())
      AS days_since_last_event
  FROM events
  WHERE event_date >= DATEADD('day', -90, CURRENT_DATE())
),

churn_signals AS (
  SELECT
    user_id,
    event_date,
    rolling_7d_revenue,
    days_since_last_event,
    -- Flag users with declining revenue trend
    CASE
      WHEN rolling_7d_revenue < LAG(rolling_7d_revenue, 7)
           OVER(PARTITION BY user_id ORDER BY event_date) * 0.7
      THEN 'HIGH_RISK'
      WHEN days_since_last_event > 14 THEN 'MEDIUM_RISK'
      ELSE 'LOW_RISK'
    END AS churn_risk
  FROM user_activity
)

SELECT * FROM churn_signals
WHERE event_date = CURRENT_DATE() - 1
ORDER BY rolling_7d_revenue DESC;
This is what premium SQL work looks like in 2026: window functions generating ML features, CTEs composing complex business logic, and analytical patterns that feed directly into AI systems. It’s not query writing — it’s data architecture expressed in SQL.
SQL vs. Python: The False Choice That Hurt Careers
One of the most damaging career myths of the past decade was that SQL and Python were competing skills — as if choosing one meant abandoning the other. That binary thinking led many engineers to underinvest in SQL in favor of chasing Python frameworks, only to find that the highest-value data work required both.
The truth is more nuanced. Python and SQL are complementary tools with clear division of labor in a modern data stack:
Task
Best Tool
Why
2026 Demand
Data transformation at scale
SQL (via dbt)
Declarative, version-controlled, warehouse-native
Very High
Feature engineering for ML
SQL + Python
SQL for aggregations, Python for model inputs
Very High
Pipeline orchestration
Python (Airflow/Prefect)
DAG logic, branching, retries
Very High
Ad-hoc data exploration
SQL
Faster iteration, no environment setup
High
Real-time stream processing
SQL (Flink/Kafka SQL)
Streaming SQL increasingly the standard
Very High
Custom ML model training
Python
scikit-learn, PyTorch, TensorFlow
High
Data quality & validation
SQL (dbt tests)
Schema-aware, automated, CI/CD-friendly
Very High
Semantic layer / metrics
SQL (dbt Semantic Layer)
Business logic lives in SQL models
Emerging
What the Job Market Is Actually Saying
Forget the hot takes. Look at the data. Across job postings, interview processes, and salary surveys, the signal is consistent: SQL is the single most requested skill in data roles, and that demand is accelerating.
365 Data Science’s 2026 job outlook report found that 69.3% of data analyst postings explicitly require domain expertise that includes SQL as a core component. Data analyst average salaries have risen to $111,000 — up $20,000 from 2025 — driven largely by this demand.
For data engineers — who live in SQL even more deeply — the numbers are stronger. Motion Recruitment’s 2026 salary guide puts senior data engineer salaries between $147,000 and $179,000. The data engineering sector now employs over 150,000 professionals with more than 20,000 new jobs created in the past year alone.
“A senior engineer who writes clean, efficient SQL will always be more valuable than a junior who can only configure tools.”
SQL in the AI-Native Stack: Where It Lives Now
The modern data stack has evolved, but SQL is woven through every layer of it. Here’s where SQL shows up in a production AI workflow today:
dbt: SQL as Software Engineering
dbt (data build tool) transformed SQL from ad-hoc query language into version-controlled, testable, documented software. With the dbt Semantic Layer now powering AI applications directly, SQL models are becoming the canonical source of business logic across the entire organization. Following the Fivetran-dbt Labs merger, the tool’s dominance in the enterprise is only growing.
Snowflake Cortex: AI Features in SQL
Snowflake’s Cortex AI suite — rebranded and expanded after Summit 2026 — exposes large language model capabilities through SQL functions. You can run sentiment analysis, text classification, and vector search directly in SQL queries. Engineers who know SQL well have immediate access to AI capabilities without switching tools.
Even the streaming world is going SQL-native. Flink SQL and Kafka’s KSQL bring declarative query patterns to real-time data. As Apache Flink becomes the standard for event-driven AI applications, SQL fluency extends seamlessly from batch to streaming workloads.
Vector Databases & Hybrid Search
The newest frontier: hybrid SQL + vector search. Platforms like Snowflake, PostgreSQL with pgvector, and Databricks now support semantic similarity search alongside traditional SQL filtering. The engineers who can combine WHERE clauses with cosine similarity thresholds are building the retrieval layers that power RAG-based AI applications.
Advanced SQL Concepts Every AI-Era Engineer Must Know
Being competitive in 2026 means going well beyond JOINs and GROUP BYs. These are the SQL concepts that separate senior engineers from the rest:
Concept
Use Case in AI Workflows
Difficulty
Window Functions
Time-series feature engineering, rolling metrics
Intermediate
CTEs & Recursive CTEs
Hierarchical data modeling, lineage graphs
Intermediate
Query Execution Plans
Optimizing training dataset queries at scale
Intermediate
Lateral Joins / UNNEST
Flattening JSON/semi-structured ML input data
Intermediate
Incremental Materialization
Efficient dbt models on large datasets
Advanced
Partitioning & Clustering
Cost-optimized queries on petabyte warehouses
Advanced
Vector / Similarity Search SQL
RAG retrieval layers, semantic search pipelines
Advanced
The Text-to-SQL Trap: Why AI Makes Human SQL Experts More Important
There’s a seductive argument that text-to-SQL tools will eventually replace SQL expertise. It’s wrong, and understanding why matters for your career strategy.
The best text-to-SQL tools in 2026 achieve 70–85% accuracy on clean, well-documented schemas. On messy enterprise databases with ambiguous column names and undocumented business logic, that number drops to 50–70%. Even with a proper semantic layer, you top out around 95%.
That 5–30% failure rate is not a rounding error. It’s the difference between a business decision based on correct revenue data and one based on a silently wrong join. And crucially — AI cannot validate its own SQL output against business intent. A human who understands both the domain and the query language has to do that.
The engineers who understand SQL deeply are not threatened by text-to-SQL. They’re empowered by it. They can build the semantic layers that make AI-generated queries more accurate, catch the failures that automated tools miss, and govern the data contracts that the entire stack depends on.
How to Build SQL Mastery That Pays in 2026
If you want to position yourself in the premium tier of data engineering talent, here’s a practical progression:
Foundation (Weeks 1–4)
Master complex multi-table JOINs, aggregations with GROUP BY and HAVING, and subqueries. Get comfortable with the full range of JOIN types and understand when to use each. Practice on real datasets — not toy examples.
Intermediate (Months 2–3)
Deep dive into window functions: ROW_NUMBER, RANK, LAG, LEAD, NTILE, and aggregate windows. Build comfort with CTEs for complex query decomposition. Start reading query execution plans in Snowflake or BigQuery.
Advanced (Months 4–6)
Learn how indexes and clustering keys affect performance at scale. Study how dbt compiles SQL and build production dbt models. Experiment with Snowflake Cortex SQL functions. Build a project that combines streaming SQL (Flink or Kafka SQL) with a batch warehouse layer.
Expert (Ongoing)
Build the semantic layer. Design data contracts. Validate AI-generated SQL. Architect the query patterns that power ML feature stores. At this level, SQL mastery translates directly into architecture decisions that affect every downstream system in the organization.
Last year, I interviewed for a Senior Data Engineer role at three different companies. All three used Snowflake heavily. All three asked completely different questions.
The first interview? They grilled me on virtual warehouse sizing and cost optimization for 15 minutes. The second? Entirely focused on data modeling and Time Travel. The third? They threw a live coding challenge at me involving complex window functions and variant data types.
I passed two out of three. The one I failed? I bombed a question about how clustering keys actually work under the hood. I knew the basics but couldn’t explain the micro-partitioning details they were looking for.
That failure taught me something: knowing how to USE Snowflake isn’t enough. You need to understand HOW it works and WHY it works that way.
After that, I spent two weeks deep-diving into Snowflake internals, cost optimization, and performance tuning. I documented every question I encountered—not just from my interviews, but from colleagues who interviewed elsewhere, from Reddit posts, from Slack channels.
This guide is the result. These aren’t generic questions you’ll find on every blog. These are real questions from actual 2025-2026 interviews, organized by difficulty and topic, with detailed answers that actually help you understand the concepts.
How to Use This Guide
Here’s how I’d actually use this list, depending on how much time you have. If you’ve got a week, work top to bottom — the order goes from foundational
architecture to the operational stuff (cost, governance) that senior interviewers love to dig into. If you’ve got two days, jump straight to the category
that matches the team you’re interviewing with: data platform teams obsess over performance and cost, security-heavy orgs grill on RBAC and Time Travel, and
analytics teams care most about Streams, Tasks, and Dynamic Tables.
If you’ve got one evening, do this: read the Common Mistakes section first, then skim the answers to questions 1, 2, 4, 9, and
13. That’s the minimum to not embarrass yourself. And whatever timeline you’re on — finish with the Preparation Checklist the night
before. It’s saved me at least twice from walking in cold.
Two days before any Snowflake interview I run through a checklist. It’s not glamorous and it’s not clever — it’s just the things I’ve watched myself
forget when the calendar invite gets too close. I’ve split it into three buckets by how much time you have left, because the prep that works two weeks out
is wasted noise the morning of.
Two Weeks Out — Build the foundation
Re-read your SYSTEM$CLUSTERING_INFORMATION notes. The depth and overlap interpretation is the single most-asked
follow-up after any clustering question. If you can’t explain why depth = 1 is good and depth = 100 is a problem, you’ll lose the senior signal.
Run a real query in Snowflake and read the Query Profile. Not from a screenshot — actually run it. Find one query that spills, one
that has 100% pruning, and one that exploded. Internalise what the profile looks like.
Cost-model one warehouse out loud. Pick a workload, pick a size (Medium is a good default), multiply credits per hour by your
estimated daily runtime, multiply by your contract rate. Do this in your head. Interviewers love when you put numbers on architecture.
Build a tiny CDC pipeline using Streams + Tasks. Five tables, one Stream, one Task. The hands-on memory makes question 11
trivial.
Read one current Snowflake release-notes page. Mention something released in the last 90 days during the interview — it shows you
actually use the platform.
48 Hours Out — Tighten the answers
Practise the architecture answer until you can deliver it in 90 seconds. Three layers, in order, with one example each. Time
yourself.
Memorise the edition matrix for Time Travel and multi-cluster warehouses. Standard = 1 day Time Travel, Enterprise = up to 90,
multi-cluster = Enterprise+. Getting this wrong is a credibility killer.
Pre-write three “tell me about a time…” stories that involve cost optimization, an incident, and a stakeholder disagreement. Map
each to a Snowflake feature you used (resource monitor, Time Travel restore, RBAC redesign).
Re-read the Common Mistakes section below. One scan. That’s where I lose the most points.
The Morning Of — Sharpen, don’t cram
Open Snowsight, run one query, read one profile. Five minutes. It primes your vocabulary.
Re-read your own résumé Snowflake bullets. Interviewers will quote them back at you and ask follow-ups. If you can’t defend a
bullet, take it off.
Have one cost number and one performance number ready to drop. “We cut warehouse credits 38% by right-sizing and AUTO_SUSPEND” is a
complete answer to half the cost questions.
Eat. Drink water. Stop reading interview articles 30 minutes before. You can’t learn anything new in the last half-hour — what you
can do is arrive sharp instead of foggy.
Snowflake Interview Questions by Company
I asked five engineers in my network what their last Snowflake interview actually felt like, then cross-referenced with public interview reports and
Glassdoor threads through 2026. The pattern is clear: the questions track the company’s actual workload. Stripe asks about high-cardinality joins because
their fact tables are colossal. Capital One asks about RBAC because they’re a bank. None of these are leaked questions — they’re the recurring themes from
publicly-shared experiences. Use them to weight your prep, not to memorise.
Snowflake (yes, the company itself)
Snowflake interviews push hard on internals because their engineers will be working on or around them. Expect at least one question that goes one level
deeper than the docs.
“Walk me through what happens between query submit and result return — including everything Cloud Services does.” (See Q1 + Q4 for the
foundation.)
“Why are micro-partitions immutable? What would change if they weren’t?” (Pruning, time travel, and zero-copy clones all collapse without
immutability — see Q2 and Q3.)
“Design a feature: instant rollback for a multi-statement transaction. What metadata would you need?”
Capital One
Heavy AWS shop, regulated. Their Snowflake interviews skew toward security, governance, and operational discipline.
“Design RBAC for a 200-person analytics org with PII data and three regional teams.” (Q9 is your starter — extend with masking policies and row
access policies.)
“How would you prove to an auditor that no analyst has queried a specific PII column in the last 90 days?” (ACCOUNT_USAGE.ACCESS_HISTORY is the
lever.)
“A warehouse is racking up cost and you can’t suspend it because it’s running a critical job. What do you do, in order?” (Resource monitor + query
queue + warehouse split — see Q13 and Q14.)
JPMorgan Chase
Similar profile to Capital One but with deeper data-modeling questions because their analytics platforms are older and more SQL-heavy.
“You have a slowly changing dimension that updates 5 million rows daily on a 2-billion-row table. Design the merge.” (MERGE INTO + clustering on the
join key + measure with Query Profile.)
“When would you use a TRANSIENT table vs a temporary table vs a regular table?” (Storage cost and Fail-safe — see Q10.)
“Walk me through Time Travel limits across editions and how that affects your DR strategy.”
Netflix
Iceberg shop with significant Snowflake usage on the analytics side. Expect questions about engine interop and lakehouse patterns.
“When would you use a Snowflake-managed Iceberg table vs a regular Snowflake table?” (Storage location, multi-engine reads, and the cost
trade-off.)
“How do you handle schema evolution when both Spark and Snowflake write to the same dataset?”
“Snowflake or BigQuery for a multi-tenant analytics product — defend your answer.”
Airbnb
Strong analytics-engineering culture — dbt, modeling, and metric layers come up a lot.
“How does Snowflake’s caching interact with dbt incremental models?” (Result cache vs warehouse cache vs metadata cache.)
“You have a dbt model that takes 40 minutes. Walk me through how you’d cut it.” (Q4’s Query Profile pipeline applies here.)
“Streams + Tasks vs Dynamic Tables for a CDC pipeline — when would you choose which?” (See Q11 and Q12, plus Mistake 6.)
Walmart Labs
Massive scale, retail-data heavy. Their Snowflake questions emphasise concurrency and cost at volume.
“Black Friday traffic. 5x normal load on the analytics warehouse. How do you handle it?” (Multi-cluster scale-out, not scale-up — see Mistake
3.)
“How would you architect Snowflake for 10,000 concurrent BI users?”
“Talk me through your warehouse-sizing methodology for a brand-new workload you’ve never seen before.”
Stripe
Engineering bar is famously high. Expect deep questions on performance, joins, and SQL correctness — they care that you can read query plans.
“Show me a Query Profile screenshot. What’s wrong, what would you fix first, and why?” (Have a real one ready from your prep.)
“Explain exactly when partition pruning fails.” (Cast functions on the WHERE column, OR conditions across columns, type mismatches.)
“How does Snowflake decide join order? When does it get it wrong?”
Note: companies and interview formats change. The questions above reflect
publicly-shared interview reports through early 2026 and are themes, not leaked items. Use them to weight your prep — not as a guarantee of what you’ll be
asked.
15 Common Snowflake Interview Questions and Answers
Architecture Questions
1. Explain Snowflake’s multi-cluster shared data architecture.
Snowflake separates into three layers: Storage (compressed columnar micro-partitions on cloud object storage),
Compute (independent virtual warehouses — elastically scalable MPP clusters), and Cloud Services (metadata,
authentication, query optimization). This separation means you can scale compute without affecting storage costs, and multiple warehouses query the same
data concurrently without contention.
Key point: Micro-partitions are 50-500MB, immutable, and self-describing with min/max metadata.
Follow-up to expect: “What happens when two warehouses query the same table simultaneously?”
2. What are micro-partitions and how does partition pruning work?
Micro-partitions are Snowflake’s fundamental storage units — immutable, compressed columnar files. Each stores metadata (min/max values, distinct
count, null count) per column. When a query has a WHERE clause, Snowflake checks this metadata and skips partitions that can’t contain matching
rows — this is partition pruning. It’s Snowflake’s primary optimization mechanism, equivalent to index seeks in traditional databases.
Pro tip: Use SYSTEM$CLUSTERING_INFORMATION('table') to check clustering depth and overlap.
3. How does zero-copy cloning work in Snowflake?
CLONE creates a metadata-only copy instantly — no physical data duplication. The clone shares underlying micro-partitions with the source. Only when
either object is modified does Snowflake write new micro-partitions (copy-on-write). Use cases: creating dev/test environments from production without
doubling storage costs, safe experimentation, and point-in-time snapshots for debugging.
Performance & Optimization Questions
4. How do you troubleshoot a slow query in Snowflake?
Use the Query Profile in Snowflake’s UI and check these indicators in order:
Partitions scanned vs total — high ratio means poor pruning → add CLUSTER BY or fix WHERE clauses
Bytes spilled to local/remote storage — warehouse too small → scale up
Queued time — concurrency bottleneck → scale out with multi-cluster warehouses
Exploding joins — cartesian product from bad join keys → fix join conditions
Also query SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY for historical slow-query patterns.
5. When should you use a clustering key?
Add a clustering key when: (1) your table exceeds 1TB, (2) queries consistently filter on specific columns (e.g., date, region), and (3)
SYSTEM$CLUSTERING_INFORMATION shows high overlap or depth. Don’t cluster small tables or tables with random access patterns. Clustering incurs
background maintenance costs (serverless credits), so only use it where the query performance gain justifies the cost.
6. Explain scaling up vs scaling out in Snowflake.
Scale up = increase warehouse size (XS → M → XL) — adds compute nodes to a single cluster for complex queries. Scale
out = add clusters via multi-cluster warehouses (Enterprise edition) — handles more concurrent queries. Rule of thumb: scale up when individual
queries are slow, scale out when queries are queuing.
Data Loading Questions
7. What is the difference between Snowpipe and COPY INTO?
Snowpipe: serverless, continuous ingestion triggered by cloud event notifications (S3 SQS, Azure Event Grid). Loads files within
minutes. Pay per-file. Best for near-real-time streaming. COPY INTO: batch loading using a warehouse. You control when it runs. More
cost-effective for scheduled bulk loads. Use Snowpipe when latency matters; use COPY INTO when cost matters and you can tolerate batch windows.
8. What are the different types of stages in Snowflake?
Three types: (1) User stages (@~) — private, auto-created per user. (2) Table stages (@%table) — tied to a specific
table. (3) Named stages (CREATE STAGE) — internal (Snowflake-managed) or external (S3, GCS, Azure Blob with IAM integration). Production
pipelines should use named external stages with proper cloud IAM roles for security and auditability.
Security & Governance Questions
9. How does Snowflake handle access control?
Snowflake uses Role-Based Access Control (RBAC). Privileges are granted to roles, and roles are granted to users. Key system roles:
ACCOUNTADMIN (top-level), SYSADMIN (object management), SECURITYADMIN (user/role management). Best practice: never use ACCOUNTADMIN for daily work — create
custom roles with least-privilege access. Enterprise edition adds column-level security (masking policies) and row-level security (row access policies).
10. What is the difference between Time Travel and Fail-safe?
Time Travel (0-90 days, configurable): user-accessible — query historical data with AT/BEFORE, restore dropped tables with UNDROP,
clone from past states. Fail-safe (7 days, non-configurable): only accessible by Snowflake support for disaster recovery. You cannot query
Fail-safe data. Use TRANSIENT tables to skip Fail-safe and reduce storage costs for non-critical data.
Streams track row-level changes (inserts, updates, deletes) on a table — essentially change data capture (CDC). Tasks
schedule SQL execution on a cron or interval basis. Together, they enable event-driven pipelines: a Task checks if a Stream has data
(SYSTEM$STREAM_HAS_DATA), then processes the changes. This is Snowflake’s native alternative to external orchestrators for simple ETL flows.
12. What are Dynamic Tables and when would you use them?
Dynamic Tables are declarative data transformations with a target lag (e.g., “keep this table within 5 minutes of source”). You write a SELECT query
defining the output; Snowflake handles incremental refresh automatically. Use them when: (1) you want dbt-like transformations without external tools, (2)
you need guaranteed freshness SLAs, (3) you want Snowflake to manage incremental logic. They replace many Streams+Tasks patterns with simpler declarative
SQL.
Cost & Operations Questions
13. How do you optimize Snowflake costs?
Key strategies: (1) AUTO_SUSPEND warehouses after 1-5 minutes of inactivity. (2) Right-size warehouses — start small
and scale up only if queries spill. (3) Use TRANSIENT tables for staging/temp data (no Fail-safe storage cost). (4) Set resource
monitors with credit quotas and alerts. (5) Separate workloads by warehouse (ETL vs BI vs ad-hoc) to avoid over-provisioning. (6) Use
result caching — identical queries within 24 hours return instantly at zero cost.
14. What is a resource monitor in Snowflake?
Resource monitors track credit consumption at the account or warehouse level and trigger actions when thresholds are reached — notify (email alert),
suspend (stop new queries), or suspend immediately (kill running queries). Set up monitors for every production warehouse with warning at 75%, suspend at
90%, and immediate suspend at 100% of monthly budget.
15. Explain Snowflake’s caching layers.
Snowflake has three caches: (1) Result cache (24 hours) — identical queries return cached results instantly, zero compute cost. (2)
Metadata cache (cloud services layer) — answers MIN/MAX/COUNT queries without scanning data. (3) Warehouse cache (local
SSD) — recently accessed micro-partitions stay on the warehouse’s local disk. Understanding these is critical for cost optimization — result caching alone
can save 30%+ on repetitive dashboard queries.
Snowflake Interview Prep Resources & Tutorials
Supplement your interview preparation with these hands-on resources to deepen your understanding of Snowflake’s architecture and features.
Practice Exercises
🎯 Hands-On: Set Up a Free Snowflake Trial
Create a free 30-day Snowflake trial with $400 in credits. Practice queries
against the pre-loaded SNOWFLAKE_SAMPLE_DATA database. Focus on: Time Travel queries, zero-copy cloning, warehouse management, and
semi-structured data with FLATTEN.
📝 Exercise: Diagnose a Slow Query
Run this practice scenario: Create a 100M+ row table, write a query without proper filters, then use Query Profile to identify the bottleneck. Practice
articulating: “The query scanned X partitions out of Y because…” — this is exactly how interviewers expect you to answer.
-- Create test data
    CREATE TABLE interview_practice AS
    SELECT
      SEQ4() AS id,
      DATEADD('second', SEQ4(), '2020-01-01') AS event_ts,
      UNIFORM(1, 1000, RANDOM()) AS user_id,
      UNIFORM(1, 50, RANDOM()) AS category_id
    FROM TABLE(GENERATOR(ROWCOUNT => 100000000));

    -- Query without clustering (check profile)
    SELECT category_id, COUNT(*)
    FROM interview_practice
    WHERE event_ts BETWEEN '2023-06-01' AND '2023-06-02'
    GROUP BY 1;

    -- Add clustering key, re-run, compare profiles
    ALTER TABLE interview_practice CLUSTER BY (event_ts);
🔄 Exercise: Build a Streams + Tasks Pipeline
Interviewers frequently ask you to design a CDC pipeline. Practice building one:
-- Source table
    CREATE TABLE raw_orders (order_id INT, status STRING, updated_at TIMESTAMP);

    -- Stream to capture changes
    CREATE STREAM orders_stream ON TABLE raw_orders;

    -- Task to process changes every 5 minutes
    CREATE TASK process_orders
      WAREHOUSE = compute_wh
      SCHEDULE = '5 MINUTE'
      WHEN SYSTEM$STREAM_HAS_DATA('orders_stream')
    AS
      MERGE INTO dim_orders t USING orders_stream s
      ON t.order_id = s.order_id
      WHEN MATCHED THEN UPDATE SET status = s.status, updated_at = s.updated_at
      WHEN NOT MATCHED THEN INSERT VALUES (s.order_id, s.status, s.updated_at);
Recommended Video Tutorials
Watch these tutorials to reinforce concepts that frequently come up in interviews:
Snowflake Architecture Deep Dive — Understand the three-layer architecture, micro-partitions, and how compute isolation works. Search
“Snowflake architecture explained” on YouTube for official Snowflake channels.
Query Profile Walkthrough — Learn to read query profiles like an interviewer expects. Look for “Snowflake query profile tutorial” for
step-by-step analysis of partition pruning, spilling, and join explosions.
Snowflake Cost Optimization Masterclass — Credit system, warehouse sizing strategies, and resource monitors. Essential for
senior-level interview questions.
Dynamic Tables vs Streams+Tasks — Understand the trade-offs between these approaches, a common 2026 interview question for
staff-level roles.
I’ve made every one of these. Some I made twice. The pattern is always the same — I knew the right answer in theory, but under interview pressure I
reached for the easier-sounding version and got caught on the follow-up. If you can train yourself to spot these in your own answers before they leave your
mouth, you’ll convert a lot of “almost passed” into offers.
Mistake 1 — Confusing micro-partitions with traditional partitioning
Symptom: you say “Snowflake auto-partitions tables on the columns you specify.” Root cause: mixing up clustering keys with partitioning. Snowflake always partitions data into 50-500 MB micro-partitions automatically,
regardless of your DDL. A cluster key only changes the order within those micro-partitions to improve pruning. Fix: rehearse the line “All Snowflake tables are micro-partitioned by default. Clustering keys influence the data layout to improve
pruning, they don’t create new partitions.” Three sentences, end of story.
Mistake 2 — Using ACCOUNTADMIN in production-access answers
Symptom: you describe a real workflow and say “we grant ACCOUNTADMIN to the service account…” Root cause: habit. ACCOUNTADMIN is the role you use in your dev account because it removes friction. Senior interviewers hear it as a
security red flag. Fix: always answer with the principle of least privilege. Custom roles inherit from SYSADMIN for object work and SECURITYADMIN for
grants. ACCOUNTADMIN is for break-glass operations and billing — never for pipelines.
Mistake 3 — Defaulting to “scale up” when they’re really asking about concurrency
Symptom: they describe a queueing dashboard and you suggest moving from M to L. Root cause: you didn’t pause to distinguish “queries are slow” from “queries are queued.” They look similar in a Slack alert. They have
opposite fixes. Fix: when you hear about concurrent users or queue time, your first answer is multi-cluster warehouse. Scale up is for
individual slow queries with spilling. Confuse these two and the interviewer will know you’ve never operated a production warehouse.
Mistake 4 — Skipping the cost angle
Symptom: you give a beautiful technical answer and the interviewer says “and what does that cost?” Root cause: data engineers are often hired specifically because someone’s Snowflake bill exploded. Every architecture decision has a
credit cost. If you don’t bring it up, they assume you don’t know. Fix: bolt one cost sentence onto every architecture answer. “We’d use Dynamic Tables here with a 5-minute target lag — that’s serverless
credits, roughly X% more than a Task-based equivalent, but we save the orchestration overhead.” Even a rough number is better than silence.
Mistake 5 — Citing Time Travel limits without knowing edition differences
Symptom: “Time Travel goes up to 90 days, so we can…” Root cause: you read the docs page about the maximum, you didn’t read the page about who gets that maximum. Standard Edition caps at 1
day. Only Enterprise and above unlock the 0–90 range. Fix: default to “Up to 1 day on Standard, up to 90 days on Enterprise and above.” This single sentence is a subtle senior-level signal
that you actually deal with edition decisions, not just feature lists.
Mistake 6 — Mixing up Streams vs Dynamic Tables
Symptom: “we use Dynamic Tables to capture changes from the source…” Root cause: both involve “incremental” and “change” so the words bleed together. They solve different problems. Fix: Streams expose row-level CDC metadata you consume in your own SQL. Dynamic Tables are a fully declarative target — you write the
SELECT, Snowflake decides how to keep it fresh. If the question is “how do we know what changed?”, that’s Streams. If the question is “how do we keep this
table fresh with one SQL definition?”, that’s Dynamic Tables.
Mistake 7 — Forgetting Snowpipe is per-file billing
Symptom: you recommend Snowpipe for everything that needs sub-hour latency. Root cause: Snowpipe feels free because it’s “serverless.” It isn’t. You pay per file plus a small overhead, and ingesting thousands of
tiny files will absolutely bankrupt the budget faster than batched COPY INTO. Fix: the one-line rule: “Snowpipe wins on latency, COPY INTO wins on cost. Use Snowpipe when minutes matter, batch COPY INTO when you can
wait, and aggregate small files before either.”
Frequently Asked Questions (FAQ)
What are the most common Snowflake interview questions?
The most common Snowflake interview questions cover architecture (multi-cluster shared data, micro-partitions, three-layer separation),
performance tuning (clustering keys, partition pruning, query profile analysis), data loading (Snowpipe, COPY INTO, stages), security (RBAC, masking
policies, Time Travel vs Fail-safe), and cost optimization (warehouse sizing, auto-suspend, resource monitors). Senior roles also get questions on Streams,
Tasks, Dynamic Tables, and system design.
How do I prepare for a Snowflake data engineer interview?
To prepare for a Snowflake data engineer interview: (1) Master the architecture — know the three layers (storage, compute, cloud
services) and how micro-partitions work. (2) Practice SQL — focus on window functions, MERGE, FLATTEN, and QUALIFY. (3) Understand performance tuning —
learn to read query profiles and diagnose slow queries. (4) Get hands-on — use Snowflake’s free trial with $400 credits to practice. (5) Study cost
optimization — understand credits, warehouse sizing, and auto-suspend. (6) Review real-time features — Streams, Tasks, Dynamic Tables, and Snowpipe are
frequently asked about in 2026 interviews.
What SQL topics should I study for a Snowflake interview?
For Snowflake SQL interviews, focus on: window functions (ROW_NUMBER, RANK, LAG/LEAD), CTEs and recursive CTEs, MERGE statements for
upserts, FLATTEN for semi-structured JSON/Parquet data, QUALIFY clause (Snowflake-specific for filtering window function results), Time Travel queries using
AT and BEFORE, VARIANT/OBJECT/ARRAY data types, and CREATE TABLE AS SELECT (CTAS) patterns. Many interviews include a live SQL coding exercise where you
write queries against sample data.
What is the difference between Snowflake and traditional data warehouses?
Snowflake differs from traditional data warehouses in several key ways: (1) It separates storage and compute — you can scale each
independently. (2) It uses a cloud-native architecture — no hardware provisioning or capacity planning. (3) It supports semi-structured data natively (JSON,
Avro, Parquet) without ETL flattening. (4) It offers near-zero maintenance — no vacuuming, no index management, automatic micro-partition optimization. (5)
It provides instant elasticity — spin up warehouses in seconds and auto-suspend when idle. (6) It enables secure data sharing without data movement via
zero-copy cloning and shares.
How many Snowflake interview rounds are there typically?
A typical Snowflake data engineer interview process has 3-5 rounds: (1) Recruiter/HR screen (30 min) — background, salary expectations,
role fit. (2) Technical phone screen (45-60 min) — SQL coding and Snowflake architecture questions. (3) System design round (60 min) — design a data
pipeline or warehouse architecture. (4) Coding/hands-on round (60 min) — write SQL queries, diagnose query profiles, or solve data modeling problems. (5)
Hiring manager/behavioral round (45 min) — leadership, collaboration, and project experience. Some companies combine rounds 2 and 4 into a single panel
interview.
Is Snowflake certification helpful for interviews?
Yes, Snowflake certifications (SnowPro Core, SnowPro Advanced Data Engineer, SnowPro Specialty Gen AI) provide an edge in interviews.
They validate foundational knowledge and signal commitment to the platform. However, certifications alone won’t get you hired — interviewers prioritize
practical experience, SQL proficiency, and the ability to solve real-world data engineering problems. Use certification prep as a structured study
framework, then supplement with hands-on practice in Snowflake’s free trial environment.
What salary can I expect for a Snowflake data engineer role?
Snowflake data engineer salaries in the US (2025-2026) range from $120K-$180K for mid-level roles and $160K-$250K+ for senior/staff
roles (base + bonus + equity). Factors include location (remote vs Bay Area), company size, years of experience, and whether the role is at Snowflake itself
vs a Snowflake customer. Cloud data engineering skills command a premium, and Snowflake-specific expertise adds 10-20% over general data engineering roles
due to high demand and limited talent pool.
When you think of aggregation functions in SQL, SUM(), COUNT(), and AVG() likely come to mind first. These are the workhorses of data analysis, undoubtedly. However, Snowflake, a titan in the data cloud, offers a treasure trove of specialized, unique aggregation functions that often fly under the radar. These functions aren’t just novelties; they are powerful tools that can simplify complex analytical problems and provide insights you might otherwise struggle to extract.
Let’s dive into some of Snowflake’s most potent, yet often overlooked, aggregation capabilities.
1. APPROX_TOP_K (and APPROX_TOP_K_ARRAY): Finding the Most Frequent Items Efficiently
Imagine you have billions of customer transactions and you need to quickly identify the top 10 most purchased products, or the top 5 most active users. A GROUP BY and ORDER BY on such a massive dataset can be resource-intensive. This is where APPROX_TOP_K shines.
This function provides an approximate list of the most frequent values in an expression. While not 100% precise (hence “approximate”), it offers a significantly faster and more resource-efficient way to get high-confidence results, especially on very large datasets.
Example Use Case: Top Products by Sales
Let’s use some sample sales data.
-- Create some sample sales data
CREATE OR REPLACE TABLE sales_data (
    sale_id INT,
    product_name VARCHAR(50),
    customer_id INT
);

INSERT INTO sales_data VALUES
(1, 'Laptop', 101),
(2, 'Mouse', 102),
(3, 'Laptop', 103),
(4, 'Keyboard', 101),
(5, 'Mouse', 104),
(6, 'Laptop', 105),
(7, 'Monitor', 101),
(8, 'Laptop', 102),
(9, 'Mouse', 103),
(10, 'External SSD', 106);

-- Find the top 3 most frequently sold products using APPROX_TOP_K_ARRAY
SELECT APPROX_TOP_K_ARRAY(product_name, 3) AS top_3_products
FROM sales_data;

-- Expected Output:
-- [
--   { "VALUE": "Laptop", "COUNT": 4 },
--   { "VALUE": "Mouse", "COUNT": 3 },
--   { "VALUE": "Keyboard", "COUNT": 1 }
-- ]
APPROX_TOP_K returns a single JSON object, while APPROX_TOP_K_ARRAY returns an array of JSON objects, which is often more convenient for downstream processing.
2. MODE(): Identifying the Most Common Value Directly
Often, you need to find the value that appears most frequently within a group. While you could achieve this with GROUP BY, COUNT(), and QUALIFY ROW_NUMBER(), Snowflake simplifies it with a dedicated MODE() function.
Example Use Case: Most Common Payment Method by Region
Imagine you want to know which payment method is most popular in each sales region.
-- Sample transaction data
CREATE OR REPLACE TABLE transactions (
    transaction_id INT,
    region VARCHAR(50),
    payment_method VARCHAR(50)
);

INSERT INTO transactions VALUES
(1, 'North', 'Credit Card'),
(2, 'North', 'Credit Card'),
(3, 'North', 'PayPal'),
(4, 'South', 'Cash'),
(5, 'South', 'Cash'),
(6, 'South', 'Credit Card'),
(7, 'East', 'Credit Card'),
(8, 'East', 'PayPal'),
(9, 'East', 'PayPal');

-- Find the mode of payment_method for each region
SELECT
    region,
    MODE(payment_method) AS most_common_payment_method
FROM
    transactions
GROUP BY
    region;

-- Expected Output:
-- REGION | MOST_COMMON_PAYMENT_METHOD
-- -------|--------------------------
-- North  | Credit Card
-- South  | Cash
-- East   | PayPal
The MODE() function cleanly returns the most frequent non-NULL value. If there’s a tie, it can return any one of the tied values.
3. COLLECT_LIST() and COLLECT_SET(): Aggregating Values into Arrays
These functions are incredibly powerful for denormalization or when you need to gather all related items into a single, iterable structure within a column.
• COLLECT_LIST(): Returns an array of all input values, including duplicates, in an arbitrary order.
• COLLECT_SET(): Returns an array of all distinct input values, also in an arbitrary order.
Example Use Case: Customer Purchase History
You want to see all products a customer has ever purchased, aggregated into a single list.
-- Using the sales_data from above
-- Aggregate all products purchased by each customer
SELECT
    customer_id,
    COLLECT_LIST(product_name) AS all_products_purchased,
    COLLECT_SET(product_name) AS distinct_products_purchased
FROM
    sales_data
GROUP BY
    customer_id
ORDER BY customer_id;

-- Expected Output (order of items in array may vary):
-- CUSTOMER_ID | ALL_PRODUCTS_PURCHASED | DISTINCT_PRODUCTS_PURCHASED
-- ------------|------------------------|---------------------------
-- 101         | ["Laptop", "Keyboard", "Monitor"] | ["Laptop", "Keyboard", "Monitor"]
-- 102         | ["Mouse", "Laptop"]    | ["Mouse", "Laptop"]
-- 103         | ["Laptop", "Mouse"]    | ["Laptop", "Mouse"]
-- 104         | ["Mouse"]              | ["Mouse"]
-- 105         | ["Laptop"]             | ["Laptop"]
-- 106         | ["External SSD"]       | ["External SSD"]
These functions are game-changers for building semi-structured data points or preparing data for machine learning features.
4. SKEW() and KURTOSIS(): Advanced Statistical Insights
For data scientists and advanced analysts, understanding the shape of a data distribution is crucial. SKEW() and KURTOSIS() provide direct measures of this.
• SKEW(): Measures the asymmetry of the probability distribution of a real-valued random variable about its mean. A negative skew indicates the tail is on the left, a positive skew on the right.
• KURTOSIS(): Measures the “tailedness” of the probability distribution. High kurtosis means more extreme outliers (heavier tails), while low kurtosis means lighter tails.
Example Use Case: Analyzing Price Distribution
-- Sample product prices
CREATE OR REPLACE TABLE product_prices (
    product_id INT,
    price_usd DECIMAL(10, 2)
);

INSERT INTO product_prices VALUES
(1, 10.00), (2, 12.50), (3, 11.00), (4, 100.00), (5, 9.50),
(6, 11.20), (7, 10.80), (8, 9.90), (9, 13.00), (10, 10.50);

-- Calculate skewness and kurtosis for product prices
SELECT
    SKEW(price_usd) AS price_skewness,
    KURTOSIS(price_usd) AS price_kurtosis
FROM
    product_prices;

-- Expected Output (values will vary based on data):
-- PRICE_SKEWNESS | PRICE_KURTOSIS
-- ---------------|----------------
-- 2.658...       | 6.946...
This clearly shows a positive skew (the price of 100.00 is pulling the average up) and high kurtosis due to that outlier.
Conclusion: Unlock Deeper Insights with Snowflake Unique Aggregations
While the common aggregation functions are essential, mastering these Snowflake unique aggregations can elevate your analytical capabilities significantly. They empower you to solve complex problems more efficiently, prepare data for advanced use cases, and derive insights that might otherwise remain hidden. Don’t let these powerful tools gather dust; integrate them into your data analysis toolkit today.
Revolutionary Declarative Data Pipelines That Transform ETL
In 2025,Snowflake Dynamic Tables have become the most powerful way to build automated data pipelines. This comprehensive guide covers everything from target lag configuration to incremental refresh strategies, with real-world examples showing how dynamic tables eliminate complex orchestration code and transform pipeline creation through simple SQL statements.
For years, building data pipelines meant wrestling with Streams, Tasks, complex scheduling logic, and dependency management. Dynamic tables changed everything. Now data engineers define the end state they want, and Snowflake handles all the orchestration automatically. The impact is remarkable: pipelines that previously required hundreds of lines of procedural code now need just a single CREATE DYNAMIC TABLE statement.
These tables automatically detect changes in base tables, incrementally update results, and maintain freshness targets—all without external orchestration tools. Leading enterprises use them to build production-ready pipelines processing billions of rows daily, achieving both faster development and lower operational costs.
What Are Snowflake Dynamic Tables and Why They Matter
Snowflake Dynamic Tables are specialized tables that automatically maintain query results through intelligent refresh processes. Unlike traditional tables that require manual updates, dynamic tables continuously monitor source data changes and update themselves based on defined freshness requirements.
Core Concept Explained
When you create a Snowflake Dynamic Table, you define a query that transforms data from base tables. Snowflake then takes full responsibility for refreshing the table, managing dependencies, and optimizing the refresh process. This declarative approach represents a fundamental shift from imperative pipeline coding.
The traditional approach:
sql
-- Old way: Manual orchestration with Streams and Tasks
CREATE STREAM sales_stream ON TABLE raw_sales;

CREATE TASK refresh_daily_sales
  WAREHOUSE = compute_wh
  SCHEDULE = '5 MINUTE'
WHEN SYSTEM$STREAM_HAS_DATA('sales_stream')
AS
  MERGE INTO daily_sales_summary dst
  USING (
    SELECT product_id,
           DATE_TRUNC('day', sale_date) as day,
           SUM(amount) as total_sales
    FROM sales_stream
    GROUP BY 1, 2
  ) src
  ON dst.product_id = src.product_id
     AND dst.day = src.day
  WHEN MATCHED THEN UPDATE SET total_sales = src.total_sales
  WHEN NOT MATCHED THEN INSERT VALUES (src.product_id, src.day, src.total_sales);
The Snowflake Dynamic Tables approach:
sql
-- New way: Simple declarative definition
CREATE DYNAMIC TABLE daily_sales_summary
  TARGET_LAG = '5 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT product_id,
           DATE_TRUNC('day', sale_date) as day,
           SUM(amount) as total_sales
    FROM raw_sales
    GROUP BY 1, 2;
The second approach achieves the same result with 80% less code and zero orchestration logic.
How Automated Refresh Works
Snowflake Dynamic Tables use a sophisticated two-step refresh process:
Step 1: Change Detection Snowflake analyzes the dynamic table’s query and creates a Directed Acyclic Graph (DAG) based on dependencies. Behind the scenes, Snowflake creates lightweight streams on base tables to capture change metadata (only ROW_ID, operation type, and timestamp—minimal storage cost).
Step 2: Incremental Merge Only detected changes are incorporated into the dynamic table. This incremental processing dramatically reduces compute consumption compared to full table refreshes. For queries that support it (most aggregations, joins, and filters), Snowflake automatically uses incremental mode.
Real-world example: A global retailer processes 50 million daily transactions. When 10,000 new orders arrive, their Snowflake Dynamic Table refreshes in seconds by processing only those 10,000 rows—not the entire 50 million row history.
Understanding Target Lag Configuration
Target lag defines how fresh your data needs to be. It’s the maximum acceptable delay between changes in base tables and their reflection in the dynamic table.
Target Lag Options and Trade-offs
sql
-- High freshness (low lag) for real-time dashboards
CREATE DYNAMIC TABLE real_time_metrics
  TARGET_LAG = '1 minute'
  WAREHOUSE = small_wh
  AS SELECT * FROM live_events WHERE event_time > CURRENT_TIMESTAMP - INTERVAL '1 hour';

-- Moderate freshness for hourly reports
CREATE DYNAMIC TABLE hourly_summary
  TARGET_LAG = '30 minutes'
  WAREHOUSE = medium_wh
  AS SELECT DATE_TRUNC('hour', ts) as hour, COUNT(*) FROM events GROUP BY 1;

-- Lower freshness (higher lag) for daily aggregates
CREATE DYNAMIC TABLE daily_rollup
  TARGET_LAG = '6 hours'
  WAREHOUSE = large_wh
  AS SELECT DATE(ts) as day, SUM(revenue) FROM sales GROUP BY 1;
Trade-off considerations:
Lower target lag = More frequent refreshes = Higher compute costs = Fresher data
Higher target lag = Less frequent refreshes = Lower compute costs = Older data
Using DOWNSTREAM Lag for Pipeline DAGs
For pipeline DAGs with multiple Snowflake Dynamic Tables, use TARGET_LAG = DOWNSTREAM:
sql
-- Layer 1: Base transformation
CREATE DYNAMIC TABLE customer_events_cleaned
  TARGET_LAG = DOWNSTREAM
  WAREHOUSE = compute_wh
  AS
    SELECT customer_id, event_type, event_time
    FROM raw_events
    WHERE event_time IS NOT NULL;

-- Layer 2: Aggregation (defines the lag requirement)
CREATE DYNAMIC TABLE customer_daily_summary
  TARGET_LAG = '15 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT customer_id,
           DATE(event_time) as day,
           COUNT(*) as event_count
    FROM customer_events_cleaned
    GROUP BY 1, 2;
The upstream table (customer_events_cleaned) automatically inherits the 15-minute lag from its downstream consumer. This ensures the entire pipeline maintains consistent freshness without redundant configuration.
Comparing Dynamic Tables vs Streams and Tasks
Understanding when to use Dynamic Tables versus traditional Streams and Tasks is critical for optimal pipeline architecture.
When to Use Dynamic Tables
Choose Dynamic Tables when:
You need declarative, SQL-only transformations without procedural code
Your pipeline has straightforward dependencies that form a clear DAG
You want automatic incremental processing without manual merge logic
Time-based freshness (target lag) meets your requirements
You prefer Snowflake to automatically manage refresh scheduling
Your transformations involve standard SQL operations (joins, aggregations, filters)
Choose Streams and Tasks when:
You need fine-grained control over exact refresh timing
Your pipeline requires complex conditional logic beyond SQL
You need event-driven triggers from external systems
Your workflow involves cross-database operations or external API calls
You require custom error handling and retry logic
Your processing needs transaction boundaries across multiple steps
-- Complex multi-table join with aggregation
CREATE DYNAMIC TABLE customer_lifetime_value
  TARGET_LAG = '1 hour'
  WAREHOUSE = compute_wh
  AS
    SELECT
      c.customer_id,
      c.customer_name,
      COUNT(DISTINCT o.order_id) as total_orders,
      SUM(o.order_amount) as lifetime_value,
      MAX(o.order_date) as last_order_date
    FROM customers c
    LEFT JOIN orders o ON c.customer_id = o.customer_id
    LEFT JOIN order_items oi ON o.order_id = oi.order_id
    WHERE c.customer_status = 'active'
    GROUP BY 1, 2;
This query would be impossible in a materialized view but works perfectly in Dynamic Tables.
Incremental vs Full Refresh
Dynamic Tables automatically choose between incremental and full refresh modes based on your query patterns.
Understanding Refresh Modes
Incremental refresh (default for most queries):
Processes only changed rows since last refresh
Dramatically reduces compute costs
Works for most aggregations, joins, and filters
Requires deterministic queries
Full refresh (fallback for complex scenarios):
Reprocesses entire dataset on each refresh
Required for non-deterministic functions
Used when change tracking isn’t feasible
Higher compute consumption
sql
-- This uses incremental refresh automatically
CREATE DYNAMIC TABLE sales_by_region
  TARGET_LAG = '10 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT region,
           SUM(sales_amount) as total_sales
    FROM transactions
    WHERE transaction_date >= '2025-01-01'
    GROUP BY region;

-- This forces full refresh (non-deterministic function)
CREATE DYNAMIC TABLE random_sample_data
  TARGET_LAG = '1 hour'
  WAREHOUSE = compute_wh
  REFRESH_MODE = FULL  -- Explicitly set to FULL
  AS
    SELECT *
    FROM large_dataset
    WHERE RANDOM() < 0.01;  -- Non-deterministic
Forcing Incremental Mode
You can explicitly force incremental mode for supported queries:
sql
CREATE DYNAMIC TABLE optimized_pipeline
  TARGET_LAG = '5 minutes'
  WAREHOUSE = compute_wh
  REFRESH_MODE = INCREMENTAL  -- Explicitly set
  AS
    SELECT customer_id,
           DATE(order_time) as order_date,
           COUNT(*) as order_count,
           SUM(order_total) as daily_revenue
    FROM orders
    WHERE order_time > CURRENT_TIMESTAMP - INTERVAL '90 days'
    GROUP BY 1, 2;
Production Best Practices
Building reliable production pipelines requires following proven patterns.
Performance Optimization tips
Break down complex transformations:
sql
-- Bad: Single complex dynamic table
CREATE DYNAMIC TABLE complex_report
  TARGET_LAG = '15 minutes'
  WAREHOUSE = compute_wh
  AS
    -- 500 lines of complex SQL with multiple CTEs, joins, window functions
    ...;

-- Good: Multiple simple dynamic tables
CREATE DYNAMIC TABLE cleaned_events
  TARGET_LAG = DOWNSTREAM
  WAREHOUSE = compute_wh
  AS
    SELECT customer_id, event_type, CAST(event_time AS TIMESTAMP) as event_time
    FROM raw_events
    WHERE event_time IS NOT NULL;

CREATE DYNAMIC TABLE enriched_events
  TARGET_LAG = DOWNSTREAM
  WAREHOUSE = compute_wh
  AS
    SELECT e.*, c.customer_segment
    FROM cleaned_events e
    JOIN customers c ON e.customer_id = c.customer_id;

CREATE DYNAMIC TABLE final_report
  TARGET_LAG = '15 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT customer_segment,
           DATE(event_time) as day,
           COUNT(*) as event_count
    FROM enriched_events
    GROUP BY 1, 2;
Monitoring and Debugging
Monitor your Tables through Snowsight or SQL:
sql
-- Show all dynamic tables
SHOW DYNAMIC TABLES;
-- Get detailed information about refresh history
SELECT *
FROM TABLE(INFORMATION_SCHEMA.DYNAMIC_TABLE_REFRESH_HISTORY('daily_sales_summary'))
ORDER BY data_timestamp DESC
LIMIT 10;
-- Check if dynamic table is using incremental refresh
SELECT *
FROM TABLE(INFORMATION_SCHEMA.DYNAMIC_TABLE_GRAPH_HISTORY(
'my_dynamic_table'
))
WHERE refresh_action = 'INCREMENTAL';
-- View the DAG for your pipeline-- In Snowsight: Go to Data → Databases → Your Database → Dynamic Tables-- Click on a dynamic table to see the dependency graph visualization
Cost Optimization Strategies
Right-size your warehouse:
sql
-- Small warehouse for simple transformations
CREATE DYNAMIC TABLE lightweight_transform
  TARGET_LAG = '10 minutes'
  WAREHOUSE = x_small_wh  -- Start small
  AS SELECT * FROM source WHERE active = TRUE;

-- Large warehouse only for heavy aggregations
CREATE DYNAMIC TABLE heavy_analytics
  TARGET_LAG = '1 hour'
  WAREHOUSE = large_wh  -- Size appropriately
  AS
    SELECT product_category,
           date,
           COUNT(DISTINCT customer_id) as unique_customers,
           SUM(revenue) as total_revenue
    FROM sales_fact
    JOIN product_dim USING (product_id)
    GROUP BY 1, 2;
Use clustering keys for large tables:
sql
CREATE DYNAMIC TABLE partitioned_sales
  TARGET_LAG = '30 minutes'
  WAREHOUSE = medium_wh
  CLUSTER BY (sale_date, region)  -- Improves refresh performance
  AS
    SELECT sale_date, region, product_id, SUM(amount) as sales
    FROM transactions
    GROUP BY 1, 2, 3;
Real-World Use Cases
Use Case 1: Real-Time Analytics Dashboard
Scenario: E-commerce company needs up-to-the-minute sales dashboards
sql
-- Real-time order metrics
CREATE DYNAMIC TABLE real_time_order_metrics
  TARGET_LAG = '2 minutes'
  WAREHOUSE = reporting_wh
  AS
    SELECT
      DATE_TRUNC('minute', order_time) as minute,
      COUNT(*) as order_count,
      SUM(order_total) as revenue,
      AVG(order_total) as avg_order_value
    FROM orders
    WHERE order_time >= CURRENT_TIMESTAMP - INTERVAL '24 hours'
    GROUP BY 1;

-- Product inventory status
CREATE DYNAMIC TABLE inventory_status
  TARGET_LAG = '5 minutes'
  WAREHOUSE = operations_wh
  AS
    SELECT
      p.product_id,
      p.product_name,
      p.stock_quantity,
      COALESCE(SUM(o.quantity), 0) as pending_orders,
      p.stock_quantity - COALESCE(SUM(o.quantity), 0) as available_stock
    FROM products p
    LEFT JOIN order_items o ON p.product_id = o.product_id
    WHERE o.order_status = 'pending'
    GROUP BY 1, 2, 3;
Use Case 2:Change Data Capture Pipelines
Scenario: Financial services company tracks account balance changes
sql
-- Capture all balance changes
CREATE DYNAMIC TABLE account_balance_history
  TARGET_LAG = '1 minute'
  WAREHOUSE = finance_wh
  AS
    SELECT
      account_id,
      transaction_id,
      transaction_time,
      transaction_amount,
      SUM(transaction_amount) OVER (
        PARTITION BY account_id
        ORDER BY transaction_time
        ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
      ) as running_balance
    FROM transactions
    ORDER BY account_id, transaction_time;

-- Daily account summaries
CREATE DYNAMIC TABLE daily_account_summary
  TARGET_LAG = '15 minutes'
  WAREHOUSE = finance_wh
  AS
    SELECT
      account_id,
      DATE(transaction_time) as summary_date,
      MIN(running_balance) as min_balance,
      MAX(running_balance) as max_balance,
      COUNT(*) as transaction_count
    FROM account_balance_history
    GROUP BY 1, 2;
Use Case 3: Slowly Changing Dimensions
Scenario: Type 2 SCD implementation for customer dimension
sql
-- Customer SCD Type 2 with dynamic table
CREATE DYNAMIC TABLE customer_dimension_scd2
  TARGET_LAG = '10 minutes'
  WAREHOUSE = etl_wh
  AS
    WITH numbered_changes AS (
      SELECT
        customer_id,
        customer_name,
        customer_address,
        customer_segment,
        update_timestamp,
        ROW_NUMBER() OVER (
          PARTITION BY customer_id
          ORDER BY update_timestamp
        ) as version_number
      FROM customer_changes_stream
    )
    SELECT
      customer_id,
      version_number,
      customer_name,
      customer_address,
      customer_segment,
      update_timestamp as valid_from,
      LEAD(update_timestamp) OVER (
        PARTITION BY customer_id
        ORDER BY update_timestamp
      ) as valid_to,
      CASE
        WHEN LEAD(update_timestamp) OVER (
          PARTITION BY customer_id
          ORDER BY update_timestamp
        ) IS NULL THEN TRUE
        ELSE FALSE
      END as is_current
    FROM numbered_changes;
Use Case 4:Multi-Layer Data Mart Architecture
Scenario: Building a star schema data mart with automated refresh
sql
-- Bronze layer: Data cleaning
CREATE DYNAMIC TABLE bronze_sales
  TARGET_LAG = DOWNSTREAM
  WAREHOUSE = etl_wh
  AS
    SELECT
      CAST(sale_id AS NUMBER) as sale_id,
      CAST(sale_date AS DATE) as sale_date,
      CAST(customer_id AS NUMBER) as customer_id,
      CAST(product_id AS NUMBER) as product_id,
      CAST(quantity AS NUMBER) as quantity,
      CAST(unit_price AS DECIMAL(10,2)) as unit_price
    FROM raw_sales
    WHERE sale_id IS NOT NULL;

-- Silver layer: Business logic
CREATE DYNAMIC TABLE silver_sales_enriched
  TARGET_LAG = DOWNSTREAM
  WAREHOUSE = transform_wh
  AS
    SELECT
      s.*,
      s.quantity * s.unit_price as total_amount,
      c.customer_segment,
      p.product_category,
      p.product_subcategory
    FROM bronze_sales s
    JOIN dim_customer c ON s.customer_id = c.customer_id
    JOIN dim_product p ON s.product_id = p.product_id;

-- Gold layer: Analytics-ready
CREATE DYNAMIC TABLE gold_sales_summary
  TARGET_LAG = '15 minutes'
  WAREHOUSE = analytics_wh
  AS
    SELECT
      sale_date,
      customer_segment,
      product_category,
      COUNT(DISTINCT sale_id) as transaction_count,
      SUM(total_amount) as revenue,
      AVG(total_amount) as avg_transaction_value
    FROM silver_sales_enriched
    GROUP BY 1, 2, 3;
New features in 2025
Immutability Constraints
New in 2025: Lock specific rows while allowing incremental updates to others
sql
CREATE DYNAMIC TABLE sales_with_closed_periods
  TARGET_LAG = '30 minutes'
  WAREHOUSE = compute_wh
  IMMUTABLE WHERE (sale_date < '2025-01-01')  -- Lock historical data
  AS
    SELECT
      sale_date,
      region,
      SUM(amount) as total_sales
    FROM transactions
    GROUP BY 1, 2;
This prevents accidental modifications to closed accounting periods while continuing to update current data.
CURRENT_TIMESTAMP Support for incremental mode
New in 2025: Use time-based filters in incremental mode
sql
CREATE DYNAMIC TABLE rolling_30_day_metrics
  TARGET_LAG = '10 minutes'
  WAREHOUSE = compute_wh
  REFRESH_MODE = INCREMENTAL  -- Now works with CURRENT_TIMESTAMP
  AS
    SELECT
      customer_id,
      COUNT(*) as recent_orders,
      SUM(order_total) as recent_revenue
    FROM orders
    WHERE order_date >= CURRENT_DATE - INTERVAL '30 days'
    GROUP BY customer_id;
Previously, using CURRENT_TIMESTAMP forced full refresh. Now it works with incremental mode.
Backfill from Clone feature
New in 2025: Initialize dynamic tables from historical snapshots
sql
-- Clone existing table with corrected data
CREATE TABLE sales_corrected CLONE sales_with_errors;

-- Apply corrections
UPDATE sales_corrected SET amount = amount * 1.1 WHERE region = 'APAC';

-- Create dynamic table using corrected data as baseline
CREATE DYNAMIC TABLE sales_summary
  BACKFILL FROM sales_corrected
  IMMUTABLE WHERE (sale_date < '2025-01-01')
  TARGET_LAG = '15 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT sale_date, region, SUM(amount) as total_sales
    FROM sales
    GROUP BY 1, 2;
Advanced Patterns and Techniques
Pattern 1: Handling Late-Arriving Data
Handle records that arrive out of order:
sql
CREATE DYNAMIC TABLE ordered_events
  TARGET_LAG = '30 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT
      event_id,
      event_time,
      customer_id,
      event_type,
      ROW_NUMBER() OVER (
        PARTITION BY customer_id
        ORDER BY event_time, event_id
      ) as sequence_number
    FROM raw_events
    WHERE event_time >= CURRENT_TIMESTAMP - INTERVAL '7 days'
    ORDER BY customer_id, event_time;
Pattern 2: Using window Functions for cumulative calculations
Build cumulative calculations automatically:
sql
CREATE DYNAMIC TABLE customer_cumulative_spend
  TARGET_LAG = '20 minutes'
  WAREHOUSE = analytics_wh
  AS
    SELECT
      customer_id,
      order_date,
      order_amount,
      SUM(order_amount) OVER (
        PARTITION BY customer_id
        ORDER BY order_date
        ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
      ) as lifetime_value,
      COUNT(*) OVER (
        PARTITION BY customer_id
        ORDER BY order_date
        ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
      ) as order_count
    FROM orders;
Pattern 3: Automated Data Quality Checks
Automate data validation:
sql
CREATE DYNAMIC TABLE data_quality_metrics
  TARGET_LAG = '10 minutes'
  WAREHOUSE = monitoring_wh
  AS
    SELECT
      'customers' as table_name,
      CURRENT_TIMESTAMP as check_time,
      COUNT(*) as total_rows,
      COUNT(DISTINCT customer_id) as unique_ids,
      SUM(CASE WHEN email IS NULL THEN 1 ELSE 0 END) as missing_emails,
      SUM(CASE WHEN LENGTH(phone) < 10 THEN 1 ELSE 0 END) as invalid_phones,
      MAX(updated_at) as last_update
    FROM customers

    UNION ALL

    SELECT
      'orders' as table_name,
      CURRENT_TIMESTAMP as check_time,
      COUNT(*) as total_rows,
      COUNT(DISTINCT order_id) as unique_ids,
      SUM(CASE WHEN order_amount <= 0 THEN 1 ELSE 0 END) as invalid_amounts,
      SUM(CASE WHEN customer_id IS NULL THEN 1 ELSE 0 END) as orphaned_orders,
      MAX(order_date) as last_update
    FROM orders;
Troubleshooting Common Issues
Issue 1: Tables Not Refreshing
Problem: Dynamic table shows “suspended” status
Solution:
sql
-- Check for errors in refresh history
SELECT *
FROM TABLE(INFORMATION_SCHEMA.DYNAMIC_TABLE_REFRESH_HISTORY('my_table'))
WHERE state = 'FAILED'
ORDER BY data_timestamp DESC;

-- Resume the dynamic table
ALTER DYNAMIC TABLE my_table RESUME;

-- Check dependencies
SHOW DYNAMIC TABLES LIKE 'my_table';
Issue 2: Using Full Refresh Instead of Incremental
Problem: Query should support incremental but uses full refresh
Complex nested queries: Simplify or break into multiple dynamic tables
Masking policies on base tables: Consider alternative security approaches
LATERAL FLATTEN: May force full refresh for complex nested structures
sql
-- Check current refresh mode
SELECT refresh_mode
FROM TABLE(INFORMATION_SCHEMA.DYNAMIC_TABLE_GRAPH_HISTORY('my_table'))
LIMIT 1;

-- If full refresh is required, optimize for performance
ALTER DYNAMIC TABLE my_table SET WAREHOUSE = larger_warehouse;
Issue 3: High compute Costs
Problem: Unexpected credit consumption
Solutions:
sql
-- 1. Analyze compute usage
SELECT
name,
warehouse_name,
SUM(credits_used) as total_credits
FROM SNOWFLAKE.ACCOUNT_USAGE.DYNAMIC_TABLE_REFRESH_HISTORY
WHERE start_time >= DATEADD(day, -7, CURRENT_TIMESTAMP)
GROUP BY 1, 2
ORDER BY total_credits DESC;
-- 2. Increase target lag to reduce refresh frequency
ALTER DYNAMIC TABLE expensive_table
SET TARGET_LAG = '30 minutes'; -- Was '5 minutes'-- 3. Use smaller warehouse
ALTER DYNAMIC TABLE expensive_table
SET WAREHOUSE = small_wh; -- Was large_wh-- 4. Check if incremental is being used-- If not, optimize query to support incremental processing
Migration from Streams and Tasks
Converting existing Stream/Task pipelines to Dynamic Tables:
Before (Streams and Tasks):
sql
-- Stream to capture changes
CREATE STREAM order_changes ON TABLE raw_orders;

-- Task to process stream
CREATE TASK process_orders
  WAREHOUSE = compute_wh
  SCHEDULE = '10 MINUTE'
WHEN SYSTEM$STREAM_HAS_DATA('order_changes')
AS
  INSERT INTO processed_orders
  SELECT
    order_id,
    customer_id,
    order_date,
    order_total,
    CASE
      WHEN order_total > 1000 THEN 'high_value'
      WHEN order_total > 100 THEN 'medium_value'
      ELSE 'low_value'
    END as value_tier
  FROM order_changes
  WHERE METADATA$ACTION = 'INSERT';

ALTER TASK process_orders RESUME;
After (Snowflake Dynamic Tables):
sql
CREATE DYNAMIC TABLE processed_orders
  TARGET_LAG = '10 minutes'
  WAREHOUSE = compute_wh
  AS
    SELECT
      order_id,
      customer_id,
      order_date,
      order_total,
      CASE
        WHEN order_total > 1000 THEN 'high_value'
        WHEN order_total > 100 THEN 'medium_value'
        ELSE 'low_value'
      END as value_tier
    FROM raw_orders;
Benefits of migration:
75% less code to maintain
Automatic dependency management
No manual stream/task orchestration
Automatic incremental processing
Built-in monitoring and observability
Snowflake Dynamic Tables: Comparison with Other Platforms
Feature
Snowflake Dynamic Tables
dbt Incremental Models
Databricks Delta Live Tables
Setup complexity
Low (native Snowflake)
Medium (external tool)
Medium (Databricks-specific)
Automatic orchestration
Yes
No (requires scheduler)
Yes
Incremental processing
Automatic
Manual configuration
Automatic
Query language
SQL
SQL + Jinja
SQL + Python
Dependency management
Automatic DAG
Manual ref() functions
Automatic DAG
Cost optimization
Automatic warehouse sizing
Manual
Automatic cluster sizing
Monitoring
Built-in Snowsight
dbt Cloud or custom
Databricks UI
Multi-cloud
AWS, Azure, GCP
Any Snowflake account
Databricks only
Conclusion: The Future of Data Pipeline develoment
Snowflake Dynamic Tables represent a paradigm shift in data pipeline development. By eliminating complex orchestration code and automating refresh management, they allow data teams to focus on business logic rather than infrastructure.
Key transformations enabled:
80% reduction in pipeline code complexity
Zero orchestration maintenance overhead
Automatic incremental processing without manual merge logic
Self-managing dependencies through intelligent DAG analysis
Built-in monitoring and observability
Cost optimization through intelligent refresh scheduling
As data freshness requirements increase and pipeline complexity grows, dynamic tables provide the declarative approach needed to build scalable, maintainable data infrastructure.
Start with simple use cases, measure performance, and progressively migrate complex pipelines. The investment in learning this technology pays dividends in reduced maintenance burden and faster feature delivery.