Category: Developer Productivity

Practical guides, workflows, and tool breakdowns for developers who want to ship faster and work smarter. No fluff — just what actually moves the needle.

  • What Happens When You Give Your Local Agent a Real Memory

    What Happens When You Give Your Local Agent a Real Memory

    Two weeks ago, an agent I run locally for pipeline maintenance rewrote a retry handler using a flat, fixed-delay retry. It looked reasonable. It was also the exact pattern that caused a duplicate-row incident in May, one I’d personally debugged for four hours and was very sure I’d never see again. I hadn’t told the agent to avoid it in that session. I’d told a different session, six weeks earlier, in a different conversation that no longer existed anywhere the model could see it. The model didn’t get dumber between May and July. It just never actually knew anything to begin with, past whatever fit in that one conversation’s context window.

    That’s the gap between “context” and “memory,” and it’s wider than most agent tooling admits. So I spent a weekend building the smallest version of real memory I could: a local Ollama agent, a SQLite database, and a habit of writing things down. It’s about 80 lines of Python. It’s also the difference between an agent that repeats your worst incidents and one that doesn’t.

    The agent embeds its own query, searches a local SQLite store, and only pulls in the notes that actually match — not the entire conversation history.

    TL;DR

    • → Most “agent memory” in demos is just re-sending the whole conversation transcript on every turn, which is a longer prompt, not memory.
    • → Real memory means distilling a short note after a session ends and retrieving only the relevant notes before the next one starts, using embeddings and cosine similarity, not a full transcript replay.
    • → Ollama’s /api/embed endpoint combined with the sqlite-vec SQLite extension gives you a working local memory layer in under 100 lines of Python, with no hosted vector database.
    • → In testing, an agent with this memory layer correctly recalled a team’s pandas-to-polars migration and avoided repeating a retry-logic mistake tied to a real past incident, both from notes written weeks earlier.
    • → Retrieval only helps if notes are written for retrieval: short, dated, and tied to one concrete decision, not a copy-paste of the conversation that produced them.
    • → The real failure mode isn’t forgetting, it’s confidently recalling something stale; a memory store needs a way to expire or overrule old notes, or it will resurface outdated decisions with total conviction.

    Why Most “Agent Memory” Isn’t Memory

    We covered the mechanics of this failure in detail in Why AI Agents Forget: a model has no persistent state between API calls, only whatever text you hand it as context. “Memory” in a lot of agent frameworks is really just a growing transcript, re-sent in full on every turn until it hits a context limit, at which point older turns get silently truncated. That’s not recall, it’s a longer prompt with an expiration date.

    Actual memory needs two things a plain transcript doesn’t have: a write step that decides what’s worth keeping after the fact, and a read step that retrieves only what’s relevant to the current task, not everything ever said. That’s a search problem, not a context-window problem, and it’s the same shape of problem as full-text search over any other document store.

    Building an Actual Memory Layer

    The setup has three pieces: Ollama running a chat model and an embedding model, a SQLite database with the sqlite-vec extension loaded for vector search, and two small functions, one to write a note, one to recall notes.

    ollama pull llama3.2
    ollama pull nomic-embed-text
    
    pip install sqlite-vec ollama

    The Write Path

    After each agent session, a short summarization pass turns the transcript into one or two standalone notes, each embedded and stored with a timestamp:

    import sqlite3, sqlite_vec, ollama, json, time
    
    def get_db():
        db = sqlite3.connect("memory.db")
        db.enable_load_extension(True)
        sqlite_vec.load(db)
        db.execute("""
            CREATE VIRTUAL TABLE IF NOT EXISTS notes USING vec0(
                embedding float[768],
                +text TEXT,
                +created_at TEXT
            )
        """)
        return db
    
    def write_memory(note_text: str):
        db = get_db()
        resp = ollama.embed(model="nomic-embed-text", input=note_text)
        embedding = resp["embeddings"][0]
        db.execute(
            "INSERT INTO notes(embedding, text, created_at) VALUES (?, ?, ?)",
            (json.dumps(embedding), note_text, time.strftime("%Y-%m-%d")),
        )
        db.commit()

    The note itself matters more than the plumbing. "Refactored ingest_events.py" is useless six weeks later. "Ingest job retries must use exponential backoff — a flat retry caused the May 3 duplicate-row incident" is something worth retrieving.

    The Read Path

    Before the agent starts a new task, it embeds the task description and pulls the closest notes by cosine distance:

    def recall_memory(query: str, top_k: int = 3):
        db = get_db()
        resp = ollama.embed(model="nomic-embed-text", input=query)
        query_embedding = json.dumps(resp["embeddings"][0])
        rows = db.execute(
            """
            SELECT text, created_at, distance
            FROM notes
            WHERE embedding MATCH ?
            ORDER BY distance
            LIMIT ?
            """,
            (query_embedding, top_k),
        ).fetchall()
        return rows

    Rendered output for a real query looks like this:

    >>> recall_memory("add a retry to the ingest job")
    [("Ingest job retries must use exponential backoff — a flat
       retry caused the May 3 duplicate-row incident", "2026-05-04", 0.13),
     ("Team migrated pandas -> polars in week 2", "2026-06-02", 0.46),
     ("Prod warehouse resizes to L on Mondays, cost review", "2026-06-10", 0.69)]

    Lower distance means a closer match, so the retry note — written five weeks earlier, in a session that no longer exists in any active context window — comes back first and gets injected into the system prompt for the new task.

    Wiring Memory Into the Agent Loop

    The integration is two calls bookending whatever loop already drives the agent, a pattern that lines up with how we’ve written about designing agent tools generally: keep the interface small, and let the model decide what to do with what it’s given, rather than hardcoding the logic yourself.

    def run_task(task: str):
        memories = recall_memory(task, top_k=3)
        memory_block = "\n".join(f"- {text}" for text, _, _ in memories)
    
        response = client.chat.completions.create(
            model="llama3.2",
            messages=[
                {"role": "system", "content": f"Relevant past notes:\n{memory_block}"},
                {"role": "user", "content": task},
            ],
        )
        result = response.choices[0].message.content
    
        # after the task completes, distill and store a new note
        summary = summarize_for_memory(task, result)
        write_memory(summary)
        return result

    The Token Math

    The other reason this beats “just send the whole history” is cost, not just accuracy. Assume an agent that’s been in use for three months, with roughly 400 prior sessions worth of context.

    ApproachContext sent per new taskRelative cost per task
    Full transcript replayGrows unbounded; truncated once it exceeds the model’s context windowIncreases every session, then degrades silently
    Retrieval, top 3 notes~150–300 tokens, regardless of history lengthFlat, independent of how long the agent has been running

    That flat cost curve is the same argument for retrieval over brute-force context stuffing that shows up in MCP-style tool design: give the model a narrow, queryable interface to what it needs, instead of handing it everything up front and hoping the important part doesn’t get truncated.

    The Gotchas Nobody Warns You About

    Stale notes get recalled with total confidence. A cosine-similarity match doesn’t know that a note is six months old and describes an architecture that’s since changed. Store a created_at timestamp and either expire notes past a threshold or have the agent flag anything older than some age as “may be outdated” before acting on it.

    Changing the embedding model invalidates the whole store. A vector from nomic-embed-text and a vector from any other embedding model live in different mathematical spaces and aren’t comparable. If you upgrade models, you re-embed every stored note, not just new ones going forward.

    Unfiltered note-writing turns into note bloat. If every session writes a note regardless of whether anything worth keeping happened, retrieval quality degrades as the noise-to-signal ratio grows. Gate the write step behind a simple check: did this session change a decision, fix a real bug, or establish a constraint? If not, don’t write anything.

    Concurrent agents writing to the same SQLite file will collide. sqlite-vec doesn’t solve multi-writer concurrency for you. If more than one agent instance can run at once, put a lock around the write path or move to a proper client-server database once you’re past a single-agent prototype.

    Memory silently retains whatever you fed it. A distilled note about a bug fix can carry along a credential, an internal hostname, or a customer identifier that happened to be in the task description. Treat the memory store like any other data store with retention and access rules, not a scratchpad that’s exempt from them.

    The One Principle

    A memory system is a curation problem before it’s a storage problem — deciding what’s worth writing down matters more than the vector database you bolt on to retrieve it.

    The 80 lines of SQLite and embedding calls above are the easy part, and they’d work identically whether the notes were good or garbage. The actual engineering is in the write path: forcing every note to be short, dated, standalone, and tied to a real decision. Get that part right and it doesn’t matter whether the retrieval layer is sqlite-vec, a hosted vector database, or something fancier — the agent stops repeating May’s incident in July, which was the entire point.

    Related reading: Why AI Agents Forget · AI Agent Tool Design · Model Context Protocol Explained · Running Ollama Inside a Data Pipeline · Ollama Embeddings Docs · sqlite-vec

  • How AI Is Reshaping Data Engineering: A Practical Guide (2026)

    How AI Is Reshaping Data Engineering: A Practical Guide (2026)

    A team I advised shipped their first AI-generated pipeline on a Thursday. An agent had scaffolded a dbt model from a plain-English request — “roll daily revenue up to weekly by region” — and the SQL was clean, the run was green, the dashboard populated. It looked like the future. Three weeks later finance flagged that Q3 regional revenue was overstated by about 11%. The model had summed a column that already contained a running total, so every week double-counted the ones before it. No error. No failed test. Just a confidently wrong number that a human skimming the SQL would probably have caught, and that the AI — and the person who accepted its output without reading it — did not.

    That is the actual shape of AI in data engineering in 2026. Not the autonomous, self-healing warehouse from the keynote. A genuinely useful assistant that raises the floor on boilerplate and lowers it, hard, on anything requiring judgment about what the data means. I’ve argued before that the thing quietly transforming this job is automation, not intelligence, and the distinction matters more now than ever. This is a practical guide — with real code and honest limits — to where AI is reshaping the work, where it isn’t, and how to use it without shipping the double-counted-revenue bug.

    TL;DR

    • → AI reshapes the edges of data engineering (drafting, testing, docs, triage) far more than the core judgment work of deciding what’s correct.
    • → On the public BIRD-SQL benchmark the best text-to-SQL system reaches about 82% execution accuracy versus 93% for humans — and only when handed human-written domain hints.
    • → On enterprise-realistic schemas with thousands of columns, that accuracy collapses into the 30–60% range, which is why “human-in-the-loop” is a permanent design, not a training-wheels phase.
    • → AI-inside-SQL (Snowflake AISQL, Cortex functions) is the most production-ready pattern: classify, extract, and summarize unstructured text without leaving the warehouse.
    • → Metadata-aware coding agents like Snowflake Cortex Code generate dbt models and Airflow DAGs from your real schemas; Snowflake reported over half its customers using it by April 2026.
    • → A green run and a passing test do not mean correct output; AI raises throughput, so it also raises the rate at which plausible-but-wrong logic reaches production.
    • → The durable skill is not prompting — it’s reviewing: reading generated SQL critically and knowing what the data is supposed to say.

    Where AI actually lands in the workflow

    Strip away the “agentic” branding and AI shows up in five concrete places along the pipeline, at very different levels of reliability. The diagram above maps them; the short version is that AI is dependable exactly where the task is mechanical and the answer is verifiable, and shaky exactly where it needs business context it doesn’t have.

    Code and model scaffolding

    This is the highest-value, most mature use today. A metadata-aware agent reads your actual table and column names and drafts a staging model, a join, or an Airflow DAG that fits your project. Snowflake’s Cortex Code, which I’ve used to cut dbt build times substantially, is the clearest example — it launched in early 2026 with native dbt and Apache Airflow support and reads your Snowflake metadata as context, which is what separates it from a generic autocomplete that only knows syntax.

    Test and assertion generation

    AI is good at proposing the tests you were too busy to write: not-null, uniqueness, accepted-values, referential checks. It’s a genuine productivity win — with one large caveat covered in the gotchas below.

    Documentation and the semantic layer

    Generating column descriptions, data-catalog entries, and semantic-model definitions is tedious, low-stakes, and easily verified — a near-perfect fit. Pairing this with retrieval over your catalog (the pattern behind RAG on your own metadata via Cortex Search) is how “ask a question about our data model” starts to actually work.

    Natural-language-to-SQL and self-serve analytics

    The dream of “business users ask questions in English” is real but oversold — see the accuracy section. It works well on clean, well-documented, narrow schemas and degrades fast on sprawling enterprise ones.

    Pipeline triage and self-healing

    The most experimental. Agents can read a failure log, hypothesize a cause, and even propose a fix. Useful as a first responder at 2 a.m.; not yet trustworthy to apply changes unsupervised. Letting an agent act on your pipeline safely is its own hard problem — I’ve written separately on giving agents metadata access without opening security holes.

    What the demos don’t tell you: the accuracy gap

    Here’s the number that should anchor every AI-for-data decision. On the public BIRD-SQL benchmark — 12,751 questions over 95 real, messy databases — the leading system as of late 2025/2026 reaches roughly 82% execution accuracy, against about 93% for human data engineers. Impressive, until you read the fine print: nearly every top score is achieved with oracle knowledge, meaning a human expert hand-wrote a domain hint for each question. Strip that away, or move to enterprise-realistic benchmarks with thousands of columns and abbreviated names, and reported accuracy drops into the 39–60% range.

    Translate that to your job: an AI that’s right 55% of the time on your real schema isn’t a replacement, it’s a fast intern whose every output needs checking. That’s not a knock — a fast, tireless intern is enormously valuable. But it reframes the whole architecture. The question stops being “can AI do this?” and becomes “how cheaply can a human verify what AI produced?” Some of the inaccuracy is also just non-determinism: the same prompt can yield different SQL on different runs, for reasons rooted in how these models sample tokens.

    Three practical examples with code

    Example 1 — AI inside SQL (the production-ready pattern)

    The most reliable way to use AI in a pipeline today is to invoke it as a function inside SQL, on the warehouse, where it’s governed and observable. Snowflake’s AISQL functions let you classify and score unstructured text with no Python and no separate model service:

    SELECT
        ticket_id,
        channel,
        AI_CLASSIFY(body,
            ['billing', 'bug', 'feature_request', 'churn_risk']) AS category,
        AI_SENTIMENT(body)                                       AS sentiment
    FROM support_tickets
    WHERE created_at >= DATEADD('day', -7, CURRENT_DATE());
    +-----------+---------+-----------------+-----------+
    | ticket_id | channel | category        | sentiment |
    +-----------+---------+-----------------+-----------+
    |     88213 | email   | churn_risk      | negative  |
    |     88214 | chat    | billing         | neutral   |
    |     88215 | email   | feature_request | positive  |
    |     88216 | phone   | bug             | negative  |
    +-----------+---------+-----------------+-----------+

    This is the sweet spot: the AI does something SQL genuinely can’t (understand free text), the output is structured and auditable, and it runs inside the governed perimeter. No pipeline of glue code shuttling data to an external API and back.

    Example 2 — Natural-language to a dbt model (draft, then review)

    You give a metadata-aware agent an instruction and it drafts a model. Say the prompt is: “Create a staging model that dedupes raw orders on order_id, keeping the latest by updated_at.” A reasonable generation looks like this:

    -- models/staging/stg_orders.sql   (AI-drafted — review before merge)
    with source as (
        select * from {{ source('shop', 'raw_orders') }}
    ),
    ranked as (
        select
            *,
            row_number() over (
                partition by order_id
                order by updated_at desc
            ) as rn
        from source
    )
    select * exclude (rn)
    from ranked
    where rn = 1

    This is genuinely good scaffolding — but read it critically before you trust it. Does updated_at ever tie? Are there soft-deleted rows this silently keeps? Is order_id actually unique per order, or per line item? The agent doesn’t know your business; you do. This is exactly where the double-counted-revenue bug from the intro slips in. Treat generated SQL like a pull request from a talented junior — and if you’re going to lean on coding agents daily, it’s worth learning to drive them well rather than as fancy autocomplete.

    Example 3 — AI-generated tests (and why they’re not enough)

    Ask an agent to add tests for the model above and you’ll get sensible YAML in seconds:

    models:
      - name: stg_orders
        columns:
          - name: order_id
            tests:
              - unique
              - not_null
          - name: status
            tests:
              - accepted_values:
                  values: ['placed', 'shipped', 'cancelled', 'returned']

    Useful, and far better than no tests. But these check shape, not truth. Every one of them can pass while the model still produces wrong numbers — the exact trap I unpack in the piece on how dbt tests go green while you ship bad data. AI makes tests cheaper to generate, which is good, but cheap tests can create false confidence, which is dangerous. The generated tests are a starting point for the assertions only a human who understands the domain can write.

    The architecture that actually works

    Put the pieces together and a pattern emerges. AI proposes; humans decide; governance enforces; monitoring closes the loop. The generative step is the cheap part now — the value has shifted to review, policy, and observability.

    The loop that works in production: generation is cheap, so the leverage moves to review, governance, and monitoring.

    Two things make this loop hold. First, context: agents are far more accurate when they can see your schemas, lineage, and semantic definitions, which is why the useful tools plug into the warehouse’s metadata rather than guessing from a prompt. Connecting agents to those systems safely is increasingly standardized on the Model Context Protocol — worth understanding at a few levels of depth. Second, governance: an AI that can write to production needs the same guardrails as a junior engineer with commit access, and then some — the subject of my piece on governing AI agents in Snowflake CoCo and MCP workflows. Snowflake’s own 2026 framing put the same point bluntly: the blocker to production isn’t model quality, it’s the governance and security around it. Databricks pushed a parallel bet with Agent Bricks; you can read the primary research on Databricks’ research page and Snowflake’s roadmap in its AI-for-data-engineering announcement.

    The cost math nobody puts on the slide

    AI-in-the-pipeline has a cost profile that surprises teams. Three real line items: per-token inference on every AI function call, always-on serving charges for managed retrieval services (Cortex Search, for instance, bills per GB indexed whether or not you query it), and the compute to re-run AI steps every time a pipeline executes.

    A quick illustrative calculation. Suppose you run AI_CLASSIFY over 2 million support tickets nightly. Even at a fraction of a cent per classification, two million calls a night is tens of dollars daily, or four-figures a month — for one column, on one table. That’s not a reason to avoid it; it’s a reason to be deliberate. Classify only new rows incrementally, not the full history every run. The same discipline that keeps warehouse bills sane applies here: don’t recompute what hasn’t changed. If you haven’t seen it, that’s the entire premise behind incremental patterns like dbt state selection, and it maps directly onto AI cost control — pay to classify a ticket once, not every night forever.

    The gotchas nobody warns you about

    A green run is the most dangerous output. AI-generated SQL fails loudly far less often than it fails silently. The bug that costs you is the one that runs clean and returns a plausible number, like the double-counted revenue that opened this article. Reconcile AI-drafted metrics against a known-good baseline before trusting them.

    Passing tests prove shape, not correctness. AI makes it trivial to generate uniqueness and not-null checks, which can lull you into thinking the model is validated. It isn’t. The assertions that catch real bugs encode business logic the AI doesn’t know.

    The same prompt gives different SQL. Non-determinism means a generation that worked in your test can differ in production or on a re-run. Pin and review generated code as artifacts; don’t regenerate it live in a pipeline and hope.

    Benchmark accuracy is a ceiling, not a floor. The 82% BIRD number is with expert hints on a research dataset. Your abbreviated, undocumented, 3,000-column enterprise schema is the hard case, not the easy one. Assume worse and verify.

    Cost scales with rows and runs, not just usage. An AI function in a nightly full-refresh quietly multiplies inference cost by your row count every single day. Make AI steps incremental or you’ll find the surprise on the invoice.

    The one principle

    AI has made generating data pipelines cheap, which means your value is no longer writing the SQL — it’s being the person who can tell whether the SQL is right. The teams winning with AI in 2026 aren’t the ones who automated the most; they’re the ones who kept a sharp human in the loop at exactly the points where being confidently wrong is expensive. Use AI to draft, and spend the time you save reviewing harder, because that’s now the job.


    Related reading: It’s not AI you should worry about — it’s automation · Cut dbt build time with Cortex Code · Why passing dbt tests still ship bad data · Governing AI agents in production · BIRD-SQL benchmark · Snowflake: AI smart pipelines

  • What 4.2 Million Food Records Taught Me About Reliable Data Quality Pipelines

    What 4.2 Million Food Records Taught Me About Reliable Data Quality Pipelines

    Processing millions of food records taught me that data quality is rarely one clever cleaning function. It is a chain of small contracts: what a number means, which identifier owns a record, what a missing value means, and what an incremental update is allowed to change.

    I learned this while building DietlyAPI, a nutrition API backed by more than 4.2 million indexed food records. Much of the catalog originates from Open Food Facts, a valuable worldwide crowdsourced database. That scale and openness are useful, but they also expose every awkward case a data pipeline eventually encounters: mixed units, incomplete labels, placeholder barcodes, duplicate products, implausible nutrition values, and partial updates.

    This article explains the patterns that made the pipeline safer. The examples are simplified, but the failure modes are real.

    Validation happens at more than one boundary in this pipeline — ingestion protects structure, serving enforces trust, converted here from the original mermaid flowchart.

    TL;DR

    • → Treating data import as one boolean is_valid check throws away useful information; structural validity, plausibility, and publish-readiness are separate questions that deserve separate gates.
    • → Store nutrient values in one consistent unit contract (per 100g) and keep serving size as separate metadata, so no consumer has to guess what a number means.
    • → Null, zero, and “omitted from this update” are three different states — collapsing them into one makes incomplete records look complete and produces false-confidence calculations downstream.
    • → Relational checks (does sugar exceed total carbs? does the stated calorie count match the macro math?) catch bad records that individually pass simple range checks.
    • → Partial updates are more dangerous than full imports: a naive upsert that blindly assigns every incoming field can silently null out good data the source simply didn’t include that day.
    • → At 4.2 million records, rare edge cases stop being rare — the highest-value tests target invariants like “an omitted delta nutrient preserves the stored value,” not just a successful job exit code.

    The Pipeline Is a Series of Trust Boundaries

    My first mistake was thinking about the import as one operation:

    Read a source file, clean each row, and insert it.

    In production, there are several separate decisions:

    1. Can the source record be parsed?
    2. Can its fields be mapped to a stable internal schema?
    3. Is the record identifiable across future imports?
    4. Are its values plausible enough to store?
    5. Is it complete and trustworthy enough to rank highly or publish?
    6. Can a later partial update safely modify it?

    Treating those questions as one boolean is_valid check loses useful information. A record with a name and barcode but no calories may still be worth retaining. A record with impossible calories should not appear in a “popular foods” response. A partial daily update should not delete fields simply because the source omitted them.

    The important detail is that validation happens at more than one boundary. Ingestion protects the database from malformed structure. Serving and publishing apply stricter quality rules appropriate to their users.

    Lesson 1: Define the Unit Contract Before Writing Transformations

    Nutrition sources frequently mix:

    • values per 100 grams;
    • values per serving;
    • grams, milligrams, and micrograms;
    • kilocalories and kilojoules;
    • numbers and human-readable strings such as 1 cup (240 g).

    If these representations leak into the application layer, every consumer must guess what each number means. That guarantees inconsistent calculations.

    Dietly’s internal contract stores nutrient values per 100 grams. Serving information is separate metadata:

    calories_kcal  = energy per 100 g
    protein_g      = protein per 100 g
    sodium_mg      = sodium per 100 g
    serving_size_g = optional weight of one stated serving
    serving_desc   = original display text, such as "1 cup (240 g)"

    That separation matters. A serving_size_g of 30 does not mean the stored calories are already scaled to 30 grams. Consumers can calculate a serving explicitly:

    def for_serving(per_100g: float, serving_size_g: float) -> float:
        return per_100g * serving_size_g / 100

    Unit conversion should occur once, close to ingestion:

    def to_milligrams(value, unit):
        if value is None:
            return None
    
        normalized = (unit or "g").lower()
        if normalized == "mg":
            return value
        if normalized in {"µg", "mcg", "ug"}:
            return value / 1000
        if normalized in {"g", ""}:
            return value * 1000
    
        # Unknown is not the same as zero.
        return None

    The final line is deliberately conservative. Silently guessing an unfamiliar unit creates a valid-looking wrong value, which is harder to detect than a null.

    The same rule applies to failed parsing:

    def parse_number(raw):
        if raw is None or not str(raw).strip():
            return None
        try:
            return float(raw)
        except ValueError:
            return None

    In nutrition data, zero is a claim. Null means “not known.” Converting missing values to zero makes incomplete products appear complete and can produce dangerously confident downstream calculations.

    Lesson 2: Validate Relationships, Not Only Individual Columns

    A schema can confirm that calories are numeric, but it cannot tell you whether 6,000 kcal per 100 grams is credible. Simple range checks catch many broken rows:

    FieldPlausible range
    calories_kcal0 – 900
    protein_g0 – 100
    fat_g0 – 100
    carbs_g0 – 100
    fiber_g0 – 100
    sugar_g0 – 100
    serving_size_g0 – 2000
    RANGES = {
        "calories_kcal": (0, 900),
        "protein_g": (0, 100),
        "fat_g": (0, 100),
        "carbs_g": (0, 100),
        "fiber_g": (0, 100),
        "sugar_g": (0, 100),
        "serving_size_g": (0, 2000),
    }
    
    def outside_range(record):
        failures = []
        for field, (low, high) in RANGES.items():
            value = record.get(field)
            if value is not None and not low <= value <= high:
                failures.append(f"{field}:outside_range")
        return failures

    However, many bad records contain values that are individually believable but mutually inconsistent. Relational checks are more powerful:

    def plausibility_failures(food):
        failures = []
    
        if (
            food.get("sugar_g") is not None
            and food.get("carbs_g") is not None
            and food["sugar_g"] > food["carbs_g"] + 0.5
        ):
            failures.append("sugar_exceeds_carbohydrate")
    
        if (
            food.get("saturated_fat_g") is not None
            and food.get("fat_g") is not None
            and food["saturated_fat_g"] > food["fat_g"] + 0.5
        ):
            failures.append("saturated_fat_exceeds_total_fat")
    
        macros = ("protein_g", "carbs_g", "fat_g")
        if food.get("calories_kcal") and all(food.get(x) is not None for x in macros):
            estimated = (
                food["protein_g"] * 4
                + food["carbs_g"] * 4
                + food["fat_g"] * 9
            )
            stated = food["calories_kcal"]
            if abs(estimated - stated) > max(120, stated * 0.5):
                failures.append("energy_macro_mismatch")
    
        return failures

    These tolerances are intentionally broad. Food labels round values, fiber and alcohol complicate energy calculations, and source conventions vary. The purpose is not to “correct” every label mathematically. It is to catch extreme contradictions before they are promoted, summarized, or used to generate authoritative-looking content.

    That led to another useful distinction:

    • Hard structural checks decide whether a record can enter storage.
    • Quality gates decide whether it can appear in high-trust surfaces.
    • Ranking signals decide which acceptable record should appear first.

    A sparse record may remain searchable without being selected for a featured-food endpoint. Keeping these policies separate avoids throwing away potentially useful data.

    Lesson 3: Identity Is Not the Same as a Barcode

    It is tempting to use a barcode as the universal product key. In real data, that fails for several reasons:

    • some records have no barcode;
    • scanner noise and hand-entered placeholders exist;
    • the same source record may be updated while keeping its source identifier;
    • different sources can use different identifiers for the same food;
    • similar products are not necessarily the same product.

    Dietly uses source provenance as the idempotency key:

    CREATE UNIQUE INDEX idx_foods_source_id
        ON foods (source, source_id);

    This answers a narrow but essential question: “Have I already imported this exact source record?” It does not pretend to solve global entity resolution.

    Known placeholder barcode patterns are removed rather than used for lookups. Returning no barcode match is safer than returning a confidently wrong product.

    Product deduplication then becomes a separate serving-layer concern. Search candidates can be grouped using a normalized name key — case-folding, punctuation removal, and collapsing repeated words — and the best row can be selected using signals such as:

    • presence of an image;
    • serving information;
    • complete core macros;
    • realistic ranges;
    • number of populated nutrient fields;
    • source confidence.

    This approach does not claim that all duplicates disappear. Instead, it prevents weak duplicates from dominating common queries while preserving the original rows and their provenance.

    Lesson 4: Partial Updates Are More Dangerous Than Full Imports

    The most instructive failure appeared in the incremental pipeline. During one update, eight already-published food pages lost their calorie values and dropped out of the page build. The import had completed successfully; the data had still become worse.

    A full export contains a broad set of fields. A daily delta may contain only the fields that are currently present upstream. If an upsert blindly assigns every incoming field, an omitted value becomes SQL NULL and can erase good data already stored.

    The unsafe version looks reasonable:

    ON CONFLICT (source, source_id) DO UPDATE SET
        calories_kcal = EXCLUDED.calories_kcal,
        protein_g     = EXCLUDED.protein_g,
        fat_g         = EXCLUDED.fat_g;

    But it treats “not included in this update” as “delete the existing value.”

    The safer policy for Dietly’s source is to preserve stored nutrition when a delta omits it:

    ON CONFLICT (source, source_id) DO UPDATE SET
        name          = EXCLUDED.name,
        calories_kcal = COALESCE(EXCLUDED.calories_kcal, foods.calories_kcal),
        protein_g     = COALESCE(EXCLUDED.protein_g, foods.protein_g),
        fat_g         = COALESCE(EXCLUDED.fat_g, foods.fat_g),
        carbs_g       = COALESCE(EXCLUDED.carbs_g, foods.carbs_g),
        image_url     = COALESCE(EXCLUDED.image_url, foods.image_url),
        updated_at    = NOW()
    WHERE foods.name IS DISTINCT FROM EXCLUDED.name
       OR foods.calories_kcal IS DISTINCT FROM
          COALESCE(EXCLUDED.calories_kcal, foods.calories_kcal)
       OR foods.protein_g IS DISTINCT FROM
          COALESCE(EXCLUDED.protein_g, foods.protein_g)
       OR foods.fat_g IS DISTINCT FROM
          COALESCE(EXCLUDED.fat_g, foods.fat_g)
       OR foods.carbs_g IS DISTINCT FROM
          COALESCE(EXCLUDED.carbs_g, foods.carbs_g);

    There are two protections here.

    First, COALESCE encodes the meaning of a missing delta field. This policy is source-specific: if an upstream system supports explicit deletion, it should send a deletion marker rather than relying on null.

    Second, IS DISTINCT FROM avoids rewriting unchanged rows. At millions of records, unnecessary updates create write-ahead-log traffic, dead tuples, index churn, and disk pressure. Idempotency is an operational feature, not only a correctness property.

    The delta cursor is committed after each successfully processed file. If a job stops halfway through a series, it resumes from the last committed file instead of replaying the entire history or skipping uncommitted work.

    Lesson 5: Preserve Provenance All the Way to the API

    Once several sources share one table, it becomes easy to flatten away where a value came from. That makes later debugging and trust decisions much harder.

    Each Dietly row retains fields such as:

    source
    source_id
    confidence
    created_at
    updated_at

    Provenance supports practical questions:

    • Which source produced this suspicious value?
    • Can the record be re-imported deterministically?
    • Should one source rank above another for this query?
    • Which rows were affected by yesterday’s delta?
    • What attribution or license applies downstream?

    Confidence is best treated as a ranking input, not proof that a value is correct. A high-confidence source can still contain an error, while an incomplete crowdsourced record can still be useful.

    Open Food Facts data is available under the Open Database License, so attribution and downstream license obligations also need to survive the journey from source to product.

    Lesson 6: Test the Failure Policy, Not Just the Happy Path

    Row counts and successful job exits are weak evidence of pipeline health. A pipeline can finish successfully after replacing thousands of values with null.

    The highest-value tests in this system target invariants:

    • importing the same record twice does not create a duplicate;
    • an omitted delta nutrient preserves the stored value;
    • a changed nutrient updates the stored value;
    • an unchanged record is not rewritten;
    • placeholder barcodes cannot produce a false lookup;
    • values outside realistic ranges cannot enter high-trust responses;
    • public response fields remain backward-compatible.

    For SQL generation, even a focused regression test can prevent a repeat:

    def test_partial_updates_preserve_nutrition():
        sql = UPSERT_SQL.upper()
        for column in ("CALORIES_KCAL", "PROTEIN_G", "FAT_G", "CARBS_G"):
            assert f"COALESCE(EXCLUDED.{column}" in sql

    In addition, record rejection or suppression reasons as categories rather than a single invalid count:

    missing_name
    invalid_number
    placeholder_barcode
    outside_range
    energy_macro_mismatch
    partial_update_preserved

    Their trends reveal upstream schema changes faster than inspecting random rows. A sudden jump in invalid_number, for example, may indicate a delimiter or unit change rather than a genuine decline in data quality.

    A Practical Checklist

    Before calling a large ingestion pipeline reliable, I now ask:

    1. Does every numeric field have a documented unit and reference basis?
    2. Are null, zero, deletion, and omission distinct states?
    3. Is the idempotency key tied to source identity?
    4. Are structural validation, quality gating, and ranking separate?
    5. Do checks cover relationships between fields?
    6. Can partial updates erase existing values?
    7. Do unchanged upserts avoid physical rewrites?
    8. Is source provenance retained in storage and responses?
    9. Can interrupted incremental jobs resume safely?
    10. Do tests reproduce the pipeline’s previous failures?

    At 4.2 million records, rare edge cases stop being rare. A one-in-a-million parsing issue is no longer hypothetical, and a harmless-looking upsert can become millions of unnecessary writes.

    The central lesson was simple: reliable data quality does not mean making every source row perfect. It means making uncertainty explicit, containing bad values, preserving what is already known, and ensuring that retries produce the same result.

    That is less glamorous than the word “pipeline” sometimes suggests. It is also what makes the pipeline dependable.

    Related reading: DietlyAPI · Open Food Facts · Open Database License

  • Top MCP Servers for High-Performance Agentic Development 2026

    Top MCP Servers for High-Performance Agentic Development 2026

    I watched an engineer lose the better part of a day to a “top MCP servers” listicle. He wired his agent to a standalone Postgres server and a Puppeteer server that a year-old post had ranked highly, spent an afternoon debugging why neither behaved, and eventually found the answer in both repositories’ READMEs: archived. Not broken — abandoned. The list he trusted was pointing at gravestones.

    That’s the state of the MCP ecosystem in 2026. The protocol won so completely that the server landscape exploded past ten thousand entries, and a large fraction of any “best of” list is now noise, stale, or dead. So this is not a star-count leaderboard. These are five servers chosen for one thing only: what they change about an agent’s actual capability — plus a sixth section for the data-engineering stack the general-purpose lists always skip. Every one of them is live and maintained as of writing, which, as that lost afternoon shows, is the specification that matters most.

    Add servers by leverage, not by star count — and start with the one that fixes errors before they’re written.

    TL;DR

    • → The five worth wiring in: GitHub (move code), Playwright (drive the browser), Context7 (inject current docs), Serena (edit code precisely), and the official reference servers (filesystem, git, fetch, memory, reasoning).
    • → Context7 is the highest-leverage addition to any code-generating agent because it kills hallucinated and deprecated APIs at write-time instead of catching them after.
    • → Star count is a vanity metric — the only durable selection criterion is whether a server is still actively maintained, since the ecosystem has archived several once-popular repos.
    • → The official reference servers are maintained as educational building blocks, not hardened production infrastructure — treat them accordingly.
    • → Every server you add re-sends its tool schemas into the model’s context on each turn, so more servers is not a better agent — fewer, sharper servers wins on both cost and accuracy.
    • → For data work, extend the general stack with the dbt MCP server and a database server so the agent reaches governed, structured assets rather than raw tables.
    • → MCP is now stewarded by the Linux Foundation’s Agentic AI Foundation, so the protocol itself is stable infrastructure — the churn is all at the server layer.

    How MCP stopped being an Anthropic project

    A little context explains why the server layer is such a mess. Anthropic open-sourced the Model Context Protocol in late 2024 as a universal way to connect models to tools and data — the fix for the N×M problem where every agent needed bespoke glue for every integration. Through 2025 the other major labs adopted it, and in December 2025 Anthropic donated MCP to the Linux Foundation’s new Agentic AI Foundation, co-founded with Block and OpenAI. By early 2026 the protocol had crossed roughly 97 million monthly downloads and more than ten thousand active servers. It became, in the phrase everyone reaches for, the USB-C of agent tooling.

    The good news is that the protocol is now neutral, stable infrastructure. The bad news is that “ten thousand servers” is mostly a graveyard with a few landmarks, and the landmarks move. An agent is only as capable as the hands you give it — the same lesson from building a Databricks AI agent whose tools are the functions it can actually call — so choosing servers well is now a real engineering decision, not a shopping trip. Here’s how I’d choose.

    The five servers worth wiring in

    1. Context7 — write correct code the first time

    The most common failure in AI coding isn’t bad logic; it’s a confidently hallucinated API — a method that was deprecated two versions ago, or never existed. Context7, from Upstash, attacks that directly by pulling up-to-date, version-specific library documentation straight into the agent’s context at the moment it’s writing code. For any agent working against fast-moving libraries, this is the single highest-leverage server on the list, because it prevents errors rather than catching them downstream. If you add one server to a code-generating agent, add this one.

    2. GitHub — turn a code reasoner into a code mover

    The official GitHub MCP server is the backbone of any agent that touches a real development workflow. It exposes repositories, issues, pull requests, Actions, and code-security surfaces through natural language, and because GitHub maintains it themselves, it tracks the platform instead of lagging behind it. This is the difference between an agent that can talk about your code and one that can open a pull request, triage an issue, or check a failing workflow. It’s the one most teams reach for first, and for good reason.

    3. Serena — give the agent an IDE’s understanding, not a text editor’s

    Search-and-replace is a crude, expensive way for an agent to edit code: it burns tokens dumping whole files into context and makes mistakes pattern-matching on strings. Serena, from Oraios, gives the agent symbol-level understanding of a codebase through the Language Server Protocol, across dozens of languages. The agent can jump to the actual function or symbol and change exactly that, which on a large codebase is the difference between a precise edit and a slow, token-hungry guess. Think IDE, not Notepad.

    4. Playwright — drive the browser without a vision model

    Browser automation is where a lot of agents fall apart, usually because they’re squinting at screenshots and guessing pixel coordinates. Microsoft’s Playwright MCP sidesteps that entirely by driving the browser through its accessibility tree — structured, deterministic data about the page instead of an image to interpret. No vision model in the loop means faster, cheaper, more reliable web interaction, whether the agent is testing a web app, completing a flow, or scraping a rendered page.

    5. The official reference servers — the local plumbing

    Rounding out a serious setup, the official reference collection ships the dependable primitives: Filesystem for local file access, Git, Fetch for pulling web content, Memory for persistence across turns, and Sequential Thinking, which gives the agent a structured space to reason step by step before acting. Two honest caveats, though. These are maintained as educational references, not hardened production infrastructure — solid building blocks you should wrap and harden yourself. And the project has archived several once-popular servers, including the standalone Postgres and Puppeteer ones, which is precisely why so many older lists now point at dead repositories. Confirm a server is live before you build on it.

    The data engineer’s addendum

    Those five are the general agentic-dev backbone, tuned for people shipping application code. If your agent works on data, the stack looks a little different, and the general lists never mention it. Two additions matter.

    First, the dbt MCP server, which dbt Labs open-sourced to give agents governed access to your dbt assets — models, metrics, lineage — instead of letting them hallucinate table names. If you already run dbt, that’s a ready-made server that plugs straight into the patterns from the native dbt integration guide, and it pairs naturally with the everyday operations in the dbt commands reference. Second, a database server scoped to read-only queries, so the agent can inspect real schemas and results rather than guess. The same instinct that makes you expose narrow, safe operations in a Streams-and-Tasks pipeline applies here: give the agent sharp, governed tools, not a firehose.

    Wiring a server in is usually just a few lines of client config. Adding the two highest-leverage ones looks roughly like this:

    {
      "mcpServers": {
        "context7": {
          "command": "npx",
          "args": ["-y", "@upstash/context7-mcp"]
        },
        "github": {
          "command": "npx",
          "args": ["-y", "@modelcontextprotocol/server-github"],
          "env": { "GITHUB_TOKEN": "your-scoped-token" }
        }
      }
    }

    Performance: fewer servers, sharper tools

    “High-performance” is doing quiet work in the phrase “high-performance agentic development,” and it’s not about which server is fastest. It’s about restraint. Every server you connect advertises its tools to the model, and those tool schemas are re-sent into the context window on essentially every turn. Bolt on five servers exposing forty tools each and you’ve handed the model two hundred tool definitions to read and choose among before it even sees the task. That costs tokens on every call, and — just as damaging — it degrades tool selection, because the model now has to discriminate among two hundred near-neighbors.

    The discipline is to connect only the servers a given agent actually needs, and to prefer servers with a few sharp tools over ones with sprawling surface area. This pressure is real enough that Anthropic shipped Tool Search and Programmatic Tool Calling in its API specifically to help agents handle large tool counts without drowning in schemas. But the cheapest optimization is still the one you make by not adding a server you don’t need. Governance and curation, not accumulation, are where the performance comes from — the same shift toward standardized, well-defined interfaces that motivates efforts like the Open Semantic Interchange.

    The gotchas nobody warns you about

    Star count is a trap; maintenance is the real metric. A repo with fifty thousand stars that hasn’t merged a commit in six months is a liability, not an asset. Before you wire in any server, check the last commit date and the open-issue response time. Archived-but-popular is the single most common way agent setups break.

    Every server taxes the context window. There’s no such thing as a free tool. Adding a server you use once a month means paying for its schemas on every single call in between. Connect deliberately, and disconnect servers an agent doesn’t use.

    Reference servers are not production infrastructure. The official filesystem, git, and fetch servers are excellent building blocks and explicitly educational. In production, wrap them with your own permission scoping, logging, and error handling rather than exposing them raw.

    Every server is an attack surface. Tool results flow back into the model’s context, which makes them a prompt-injection vector; a filesystem server with broad access is a data-exfiltration risk. The security community has already catalogued dozens of attack techniques aimed specifically at tool-using agents. Scope permissions tightly, prefer read-only where you can, and don’t run a server you haven’t vetted.

    Know whether you’re running local or remote. A local (stdio) server the client launches as a subprocess has a very different trust and auth model from a remote server reachable over a URL. Remote servers need real authentication; local ones need real filesystem discipline. Don’t blur the two.

    The one principle: add hands, not stars

    A server earns its place by changing what your agent can do — not by how many stars it has, and only if it’s still alive. The protocol already did the hard part: it made every compliant tool plug into every compliant agent, and put the standard under neutral governance so it won’t shift under you. What’s left is a curation problem wearing a shopping problem’s clothes. Give your agent the smallest set of sharp, maintained servers that cover what it actually needs to do — write correct code, move it, edit it precisely, reach the browser, touch the filesystem, query your governed data — and stop there. The best agent stack isn’t the longest one. It’s the one where every server is still being maintained and every tool earns its seat in the context window.

    Related reading: Build a Databricks AI Agent with GPT-5 · Snowflake Native dbt Integration · dbt Commands Cheat Sheet · Snowflake Interview Questions 2026 · Official MCP reference servers · MCP joins the Agentic AI Foundation

  • Introduction to Loop Engineering: Designing AI Agent Loops (2026)

    Introduction to Loop Engineering: Designing AI Agent Loops (2026)

    A team I know left a coding agent running on a Friday afternoon. The task was open-ended — “keep fixing failing tests until the suite is green” — and the agent dutifully looped. It just never stopped. Over the weekend it retried the same broken approach against the same failing test hundreds of times, each attempt a fresh round of expensive model calls. Monday’s lesson wasn’t in the code the agent wrote. It was in the bill, and in the realization that nobody had designed the one thing that mattered: when the loop was allowed to quit.

    That missing off-switch is the entire subject of a discipline that got its name in June 2026 and has been reorganizing how people talk about agents ever since: loop engineering. If you’re still pouring your effort into writing the perfect prompt, you’re optimizing a bottleneck that already moved. The prompt isn’t where agents break anymore. The loop is.

    One turn of an agent loop — trigger, plan, act, verify, persist — and then a stop rule decides whether to go around again.

    TL;DR

    • → Loop engineering is the practice of designing the system that prompts an AI agent for you — its trigger, its steps, its verifier, and its stop rules — instead of prompting the agent by hand each time.
    • → It’s the fourth layer in a stack: prompt engineering, then context engineering, then harness engineering, then loop engineering — each one wraps the layer inside it rather than replacing it.
    • → An agent, stripped down, is “an LLM in a while loop with tools” — the loop, not the model, is what separates an agent from a chatbot.
    • → The single most important design decision is the stop rule: a loop with no termination logic is a resource sink that burns money without converging.
    • → Never let an agent grade its own work — models asked to evaluate their own output reliably inflate the grade, so generation and verification must be separate.
    • → Because generation is now cheap and abundant, the scarce resource is judgment: the quality of your verifier sets the quality of the whole loop.
    • → Agent loops make roughly 10x–100x more model calls than a single prompt, so cost control (model routing, prompt caching, iteration caps) is a first-class part of the design, not an afterthought.

    What loop engineering actually is

    The clearest definition comes from Addy Osmani, a director on Google’s Cloud AI team, who named the practice in an essay in June 2026: loop engineering is replacing yourself as the person who prompts the agent, and designing the system that does it instead. The idea was in the air already — Peter Steinberger’s one-line version (stop prompting your coding agents; design the loops that prompt them) crossed millions of views in a day, and Boris Cherny, who built Claude Code, described his own job the same way: writing the loops that drive the model. Osmani gave the scattered practice a name and a parts list.

    Underneath the buzz, the mechanism is unglamorous. Simon Willison’s stripped-down definition is the one to hold onto: an agent is “an LLM in a while loop with tools.” It takes an input, reasons about what to do, calls a tool, looks at the result, and goes around again until it’s done or hits a limit. That cycle is the whole ballgame. A chatbot answers in one pass; an agent persists across many steps. If you’ve walked through my guide to building a Databricks AI agent that reasons, acts, observes, and repeats, you’ve already built the innermost loop — loop engineering is the discipline of everything wrapped around it.

    It helps to see loop engineering as the top of a stack that grew one layer at a time. Prompt engineering is about the words you send. Context engineering is about all the information the model can see. Harness engineering is about the environment the agent runs in — its files, tools, and memory. Loop engineering is about the iterative cycle that drives the agent toward a goal. Each layer wraps the previous one; none of them replaces it. The model is the brain, the harness is the body, and the loop is the routine that gets the body out of bed every morning.

    A single turn of the loop

    Decompose one pass through a loop and you get roughly five moves: discovery (find the work to do), handoff (give it to the agent with the right context), verification (check the result against something external), persistence (write down what happened so the next run remembers), and scheduling (decide when to run again). The diagram above is that turn drawn out. Miss any one of them and the loop degrades in a predictable way — skip persistence and every run starts from amnesia; skip verification and errors compound silently.

    Osmani’s parts list maps neatly onto this. A real loop needs automations (a schedule or event trigger — without one it’s just a chat session), isolated workspaces so parallel runs don’t collide, codified knowledge the agent can load on demand, connectors to real tools and systems, and independent verification from a second agent. There’s a sixth piece that ties them together: external state — a markdown file or a task board — so progress survives between runs.

    Two of those pieces are familiar territory for data engineers. The trigger is just scheduling, the same instinct behind orchestrating pipelines with Snowflake Streams and Tasks on a cadence. And the connectors are how the agent reaches your data at all — increasingly through MCP servers wrapping governed assets, which slots right next to a native dbt integration or the everyday operations in the dbt commands reference. Loop engineering doesn’t throw out your orchestration and governance instincts — it reuses them.

    The loops stack: loopcraft

    The real leverage shows up when you stop thinking about a single loop and start stacking them. LangChain’s framing describes four loops nested inside one another, and value compounds as you climb:

    1. The agent loop

    The model calls tools until the task is done. This is the one everyone starts with, and the one most tutorials stop at.

    2. The verification loop

    Wrap the agent loop in a grader that checks each output against a rubric. Fail the check, feed the failure back, and try again. The grader can be deterministic (run the tests, confirm the links resolve) or another model acting as judge.

    3. The application loop

    A human approves outputs before they reach the end user. This is where “human in the loop” stops being a slogan and becomes an actual control point on sensitive workflows.

    4. The hill-climbing loop

    The outermost loop improves the harness itself — better prompts, better tools, better rubrics — with changes flowing through review before they deploy. This is where an agent stops being a fixed tool and starts getting better at your specific work over time.

    Most teams live in loops 1 and 2. The compounding value is in 3 and 4, where the system embeds into your workflow and improves against your standards instead of a generic benchmark.

    The verifier is the whole game

    Here is the insight that separates people who ship reliable loops from people who ship expensive ones. When generation becomes cheap — and inside a loop, it does — the bottleneck moves entirely to verification. A loop only spins as fast as its ability to tell a good result from a bad one. Andrej Karpathy’s version of this is the generation-verification loop: generation got cheap, so the loop is rate-limited by its verification half, which makes review, taste, and knowing what “correct” looks like the most leveraged skills an engineer has. Your judgment, encoded into a verifier, is effectively the loop’s reward function.

    Which leads to the rule you cannot skip: do not let the agent grade its own homework. Empirically, a model asked to evaluate its own output tends to praise it — it gives itself an A. Tuning a separate, skeptical evaluator is far more tractable than trying to make a generator honestly critical of its own work. Keep the generator and the evaluator apart. This is the same principle behind agreeing on shared, governed definitions before you trust automated output, which is exactly the problem the Open Semantic Interchange is trying to solve at the industry level: automation is only as trustworthy as the standard it’s checked against.

    What does this look like as code? Every real loop has the same skeleton — generate, verify with something independent, stop on success or a hard cap:

    def run_loop(goal, max_iterations=8):
        state = load_state(goal)          # persistence: remember prior runs
        for attempt in range(max_iterations):
            result = agent_generate(goal, state)   # the inner agent loop
            verdict = independent_verify(result)   # a SEPARATE evaluator
            save_state(goal, result, verdict)      # write progress down
            if verdict.passed:
                return result                       # stop rule: success
        raise StoppedIncomplete(goal, state)        # stop rule: hard cap

    The interesting lines aren’t the generation — they’re the ones that decide when to quit and who does the judging.

    The cost math nobody does upfront

    A single prompt is one model call. A loop is not. Reported figures put agent loops at roughly 10x to 100x the number of model calls of a single-shot prompt, because every iteration — every plan, act, and verify — is its own round of inference. That multiplier is the whole cost story.

    Work a rough example. Say one loop turn costs about 15,000 tokens once you count the plan, the tool calls, and the verification pass. A task that converges in 4 turns costs ~60,000 tokens — fine. But a goal-based loop with a weak verifier and a generous iteration cap that grinds for 40 turns costs ~600,000 tokens for a single task, and if it never hits a stop condition it just keeps going. Run that unattended across a fleet of tasks and the numbers stop being rounding errors. The fixes are concrete: route cheap sub-steps (classification, triage) to small models and reserve the frontier model for final review; cache the stable prefix of your prompts so repeated context isn’t re-billed every turn; and cap iterations hard. Teams applying model routing and caching report total loop costs dropping on the order of 60–80%. None of that helps if the loop can’t decide to stop — which is the real lesson of that Friday-to-Monday weekend.

    The gotchas nobody warns you about

    A loop with no stop rule is a resource sink, not an agent. Termination logic is not a finishing touch — it’s a first-class design requirement. Decide up front what “done” means, what the maximum iteration count is, and what happens when neither is reached. The default failure mode of an autonomous loop is not crashing; it’s running forever.

    Retrying the same action after the same error is spinning, not iterating. A loop that hits an error and tries the identical approach again has learned nothing. Design it to distinguish recoverable errors (a syntax slip, a missing import) from hard blockers (missing credentials, undefined behavior) and to actually change its approach — or escalate — rather than repeat itself.

    No memory between runs means every run starts over. Without external state — a file, a board, a database row — each run is a stranger to the last. Persistence is what turns a sequence of one-shot attempts into a system that makes progress.

    The evaluator is where your effort should go, not the generator. It’s tempting to spend your time making the agent smarter. The higher-leverage work is making the verifier sharper, because the verifier is the ceiling on everything the loop can produce.

    Most tasks don’t need a loop yet. This is the contrarian one. For a one-off job, an interactive session with a capable agent is usually faster than building and babysitting a loop. Loops earn their complexity on recurring, well-scoped, verifiable work — PR reviews, dependency updates, test triage — not on everything. Reaching for a loop by default is its own failure mode.

    The one principle: automate the generating, own the judging

    The agent runs the inner loop; you own the outer one. That’s the whole discipline in a sentence. Hand the model the repetitive generation — the drafting, the fixing, the trying-again — and keep for yourself the two things that actually determine whether the loop is worth running: what counts as done, and whether the work is any good. Loop engineering isn’t about making agents more autonomous for its own sake. It’s about moving your attention up a level, from writing the prompt to designing the system that decides when to stop and who gets to say the result is correct. Get the stop rule and the verifier right, and the rest of the loop mostly takes care of itself.

    Related reading: Build a Databricks AI Agent with GPT-5 · Snowflake Streams and Tasks · Snowflake Native dbt Integration · Snowflake Interview Questions 2026 · Addy Osmani: Loop Engineering · LangChain: The Art of Loop Engineering

  • Running Ollama Inside a Data Pipeline: What Actually Breaks

    Running Ollama Inside a Data Pipeline: What Actually Breaks

    Three weeks ago I watched a teammate open the OpenAI billing dashboard and go quiet. We’d built a PII-tagging job that ran a small classification prompt against every new row landing in a raw events table, about 500,000 rows a day, to flag anything that looked like an email, a phone number, or a government ID before it hit a shared schema. It worked. It also cost $340 a day once we accounted for retries, and legal wanted to know exactly which vendor now had a standing copy of our customer data. Neither number was going to survive the next budget review.

    The fix wasn’t a smarter prompt or a cheaper API tier. It was moving the model onto the same box that already ran the pipeline. Ollama had been sitting in my “toys, not tools” mental bucket for a year, something for chatting with a local Llama build on a Saturday. Turns out it’s a perfectly serviceable inference server for exactly this kind of narrow, high-volume, structured-output task, and it doesn’t send a single row anywhere.

    Flowchart showing PII Tagging Job: Airflow sends batches to Ollama API and a quantized model, outputs structured JSON, stored in Snowflake Stage, and merged into a Snowflake Target Table.

    The whole job runs on infrastructure you already control. Only the base URL in your HTTP client changes if you ever move to a hosted model.

    TL;DR

    • → Ollama exposes an OpenAI-compatible API on localhost:11434, so swapping a cloud LLM call for a local one in an Airflow task is usually a one-line change to the client’s base URL.
    • → Small quantized models (3B–8B parameters at 4-bit) handle narrow, structured tasks like PII tagging, log classification, or doc-string generation well; they are not a drop-in replacement for a frontier model on open-ended reasoning.
    • → A 4-bit quantized 3B model needs roughly 2–3 GB of memory instead of the 6+ GB full precision would require, which is why it fits on a shared pipeline host without a dedicated GPU budget.
    • → For a 500K-row daily classification job, local inference on existing hardware runs at effectively $0 marginal cost per run, versus real per-token cloud spend that scales with volume.
    • → Ollama is a single background daemon, not a per-task process, so the first request in an Airflow DAG can be slow while the model loads into memory, and this needs its own timeout handling.
    • → Running the model locally also means the compliance conversation changes: no row of customer data leaves the host you already control access to.

    Why This Belongs in the Pipeline, Not Just the Terminal

    Most Ollama content is written for a single, interactive session: install it, pull a model, chat with it, done. That’s a fine on-ramp, but it undersells what the tool is actually good for once you strip away the chat interface. Underneath the terminal experience is a plain HTTP server. It handles model loading, memory management, and hardware acceleration, and it exposes a REST API that speaks the same shape as OpenAI’s chat completions endpoint. That last part matters more than the local-vs-cloud framing usually gives it credit for: if your pipeline code already calls an LLM through an OpenAI-compatible client, pointing it at Ollama is a base-URL change, not a rewrite.

    That’s the same reasoning that made Snowflake’s own Cortex tooling worth covering here: the interesting engineering question is never “can the model do the task,” it’s “what does it cost to wire this into infrastructure we already run.” Ollama’s answer is: not much, provided the task is narrow enough for a small model to handle reliably.

    Installing Ollama on a Pipeline Host, Not a Laptop

    The install itself is unremarkable, which is the point. On the Linux boxes running our Airflow workers, it’s a single script:

    curl -fsSL https://ollama.com/install.sh | sh
    
    # confirm the daemon is up and check the version
    ollama --version
    systemctl status ollama

    Ollama installs itself as a systemd service on Linux, listening on 127.0.0.1:11434 by default. If your Airflow workers and the model need to live on separate hosts, you’ll want to bind it to the internal network interface instead and lock that down with a security group, not expose it publicly:

    sudo systemctl edit ollama
    # add under [Service]:
    # Environment="OLLAMA_HOST=0.0.0.0:11434"
    sudo systemctl restart ollama

    Picking a Model That Fits the Task, Not the Demo

    For structured tagging work, you don’t want the biggest model that fits on the box. You want the smallest one that hits your accuracy bar, because latency and memory headroom compound across half a million rows. We landed on a 3B-class model after testing three sizes against a hand-labeled validation set:

    ollama pull llama3.2
    ollama pull qwen3:8b
    ollama pull gemma4:e4b

    By default Ollama pulls a 4-bit quantized build (q4_K_M), which is why a 3B model downloads at roughly 2 GB instead of the 6 GB a full-precision (fp16) version would need. That quantization step compresses the model’s weights into 4-bit integers, and for a classification task with a fixed, narrow label set, the accuracy hit is negligible. It would be a different conversation for open-ended generation.

    Wiring It Into an Airflow DAG

    The integration point is a plain HTTP call inside a PythonOperator, using the OpenAI-compatible endpoint Ollama exposes at /v1/chat/completions:

    from openai import OpenAI
    from airflow.decorators import task
    
    client = OpenAI(base_url="http://localhost:11434/v1", api_key="not-needed")
    
    @task
    def tag_pii_batch(rows: list[dict]) -> list[dict]:
        results = []
        for row in rows:
            response = client.chat.completions.create(
                model="llama3.2",
                messages=[
                    {"role": "system", "content": (
                        "Classify the input for PII. Respond with strict JSON: "
                        '{"has_pii": bool, "categories": [string]}'
                    )},
                    {"role": "user", "content": row["raw_text"]},
                ],
                temperature=0,
            )
            results.append({"row_id": row["id"], "tags": response.choices[0].message.content})
        return results

    Run output for a single row looks like this once it comes back through the DAG’s logging:

    {"row_id": "evt_88213", "tags": "{\"has_pii\": true, \"categories\": [\"email\", \"phone\"]}"}
    

    The output then lands in a staging table and gets merged into the target with a standard MERGE statement, the same pattern we used when writing about Time Travel for auditing exactly which run tagged which row.

    The Cost Math

    Here’s the comparison that actually mattered to our budget review. Assume 500,000 rows a day, roughly 120 input tokens and 40 output tokens per row for a classification prompt like the one above.

    ApproachDaily token volumeMarginal cost / dayData leaves the host?
    Cloud API, mid-tier model~80M tokens~$310–$360, scales with volumeYes
    Ollama, local 3B model, existing pipeline host~80M tokens~$0 marginal (existing hardware)No

    The local path isn’t free in an absolute sense, you’re spending CPU/GPU cycles you already own, and if the host is undersized you’ll eventually pay for a bigger instance. But that’s a fixed, predictable infrastructure cost instead of a bill that grows linearly with data volume, which is the same argument we made when comparing orchestrator licensing models: usage-based pricing is fine until usage is the thing you’re trying to grow.

    The Gotchas Nobody Warns You About

    The first request in a DAG run pays the cold-load tax. Ollama unloads a model from memory after a period of inactivity (five minutes by default). If your DAG runs hourly, every run’s first task can eat several extra seconds waiting for the model to load back in. Set keep_alive in the request payload to a longer duration, or ping the model with a lightweight warm-up call before the real batch starts.

    Concurrent Airflow tasks will silently queue, not fail. Ollama serializes requests to a given model by default unless you’ve explicitly configured parallel request handling. If you fan out ten parallel tasks expecting ten times the throughput, you’ll instead get one queue that’s ten times longer, with no error to tell you why it’s slow.

    Schema-constrained output still needs a parser, not blind trust. Even with an explicit “respond with strict JSON” instruction, small models occasionally wrap their answer in a stray sentence or a markdown code fence. Wrap every response in a real JSON parse with a fallback path, the same defensive habit you’d apply to any external API, local or not.

    A shared host means a shared blast radius. If the same box also runs other Airflow tasks, a model pinned in GPU memory can starve them of resources in ways that look like an unrelated flaky DAG. Give the inference workload its own resource ceiling, whether that’s a cgroup limit or a dedicated worker pool.

    Version drift is real and mostly undocumented per-task. Ollama ships frequent releases, and quantization defaults or model behavior can shift between versions. Pin the Ollama version and the exact model tag (not just latest) in whatever config or container image your pipeline deploys, the same way you’d pin a Python package version.

    The One Principle

    A local model is an infrastructure decision before it’s an AI decision — treat it like the database or the queue it’s sitting next to, with monitoring, resource limits, and version pins, and the “AI” part of the problem turns out to be the easy half.

    That framing is also why this pattern generalizes past PII tagging. The same DAG shape works for classifying malformed records before they hit a Delta Lake or Iceberg table, generating draft column descriptions during a schema change, or triaging alert text before it pages someone. None of those need a frontier model. They need a small one that’s fast, cheap, and doesn’t leave the building, which is precisely the gap Ollama fills once you stop thinking of it as a chat toy and start thinking of it as another service in the stack, not unlike how we’ve written about the tradeoffs inside Snowflake’s warehouse cache or the workflow shifts in Cortex Code Desktop.

    Related reading: Snowflake Cortex Code Desktop · Airflow vs. Prefect · Snowflake Time Travel · Ollama · Ollama OpenAI-Compatibility Docs

  • Build a Simple MCP Server in Python with FastMCP (2026)

    Build a Simple MCP Server in Python with FastMCP (2026)

    A colleague pinged me last spring, quietly furious. He’d spent three days building an MCP server to give an internal agent access to the team’s Snowflake warehouse. The protocol part worked on day one. What ate the other two and a half days was everything the tutorials skip: the agent kept picking the wrong tool, the responses ballooned the token bill, and a stray print() statement silently corrupted every message the server sent. The server was “done” in ten lines. It was useful about a week later.

    That gap — between a server that runs and a server that actually helps a model do its job — is the entire subject of this article. The Model Context Protocol has become the default way to plug LLMs into real systems, and building a basic server in Python is genuinely a ten-minute job. But the ten-minute version is a trap if you think you’re finished when it starts. The protocol is the easy part. Tool design is the hard part, and nobody warns you.

    A five-step flowchart labeled How a Tool Call Flows, showing steps: Discover, Request, Execute, Return, and Use, with arrows connecting each. Client and server sides are indicated by color.

    Every MCP interaction is this loop: discover, call, execute, return, use — the model never touches your Python directly.

    TL;DR

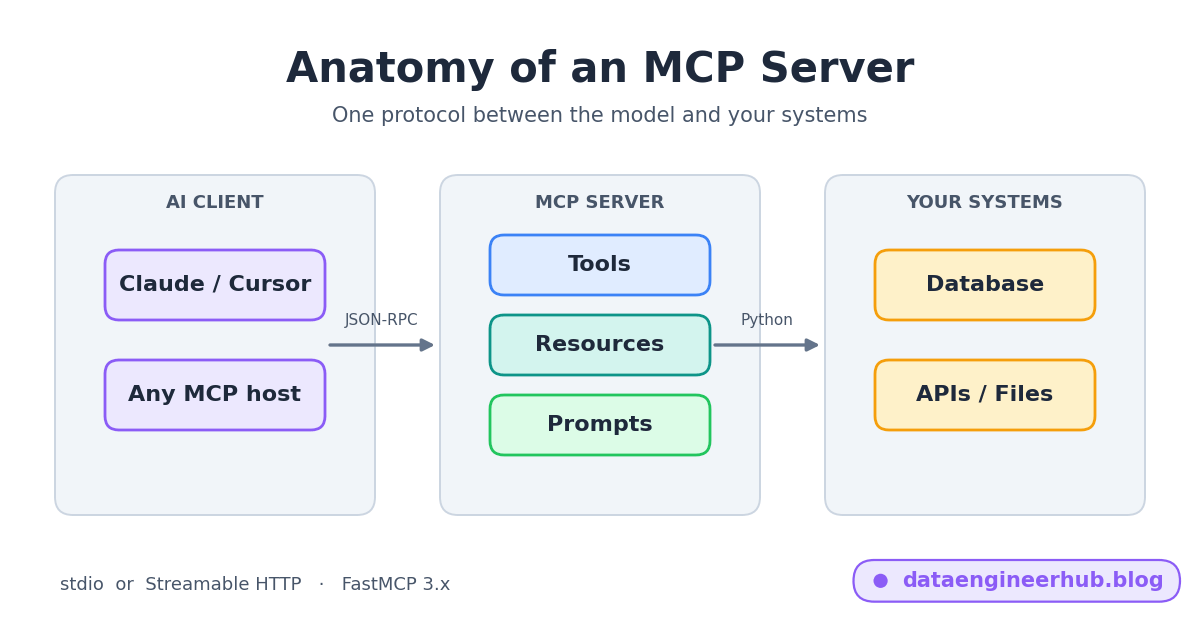
    • → An MCP server is a passive provider: it advertises tools, resources, and prompts, then waits for an AI client to call them over JSON-RPC. Your code never calls the model.
    • → With FastMCP (version 3.4.0 as of June 2026, Python 3.10+), a working server is a decorated Python function plus mcp.run() — roughly ten lines.
    • → There are exactly two standard transports: stdio for local servers the client launches as a subprocess, and Streamable HTTP for remote servers reachable over a URL.
    • → A tool’s docstring and type hints are its prompt — the model chooses tools from that text, so vague descriptions cause wrong-tool selection more often than bad logic does.
    • → Every tool schema is re-sent to the model on effectively every turn, so dumping forty tools into one server quietly inflates token cost and degrades tool selection.
    • → For stdio servers, writing anything that isn’t a valid MCP message to stdout corrupts the stream — the single most common “it worked yesterday” bug.
    • → Remote servers on Streamable HTTP need real auth; the 2025-06-18 spec standardized OAuth 2.1 for exactly this, and it is the part that turns a demo into a project.

    What an MCP server actually is

    Strip away the acronym and the mental model is simple: an MCP server is a small program that exposes capabilities in a shape an AI model understands, and then sits still. It does not orchestrate anything. It does not call the LLM. It answers a discovery request (“what can you do?”) and then runs whatever the client asks it to run. If you’ve read my walkthrough of building a Databricks AI agent where tools are just Python functions the LLM decides to call, MCP is that same idea lifted into an open standard so any client can use your tools without a custom integration.

    The protocol defines three primitives. Tools are actions the model can invoke — run a query, send a message, create a ticket. Resources are read-only data the model can pull in for context — a file, a schema, a config. Prompts are reusable templates a user can trigger. Messages travel as JSON-RPC 2.0. The current protocol revision is 2025-06-18, and it is worth pinning that number because the transport story changed underneath it — more on that below.

    Here’s the versioning landmine, since half the tutorials online get it wrong: FastMCP and “the MCP Python SDK” are related but not identical. FastMCP 1.0 was folded into the official SDK back in 2024, and then the standalone project kept going on its own track. Today the standalone FastMCP on PyPI is at 3.4.0, while blog posts still confidently reference “2.x” or a mythical “3.0 rewrite” as if that’s current. When you read example code, check which one it’s for — the decorator API differs in small, breaking ways between versions.

    The ten-line server

    Install it with FastMCP (uv is the fast path, plain pip works fine):

    uv pip install fastmcp
    # or: pip install fastmcp
    The canonical first server is an addition tool. This is genuinely the whole file:
    
    from fastmcp import FastMCP
    
    mcp = FastMCP("Demo")
    
    @mcp.tool
    def add(a: int, b: int) -> int:
        """Add two integers and return the sum."""
        return a + b
    
    if __name__ == "__main__":
        mcp.run()          # stdio transport by default

    Notice what you did not write: no JSON-RPC handlers, no schema definitions, no transport plumbing. FastMCP reads your type hints to build the tool’s input schema and your docstring to describe it to the model. That’s the whole pitch of the framework, and it’s why it powers the large majority of MCP servers in the wild.

    To try it before wiring it into a client, run the dev inspector, which launches a local UI that shows the raw JSON-RPC traffic:

    fastmcp dev server.py

    Call the tool from the inspector and you’ll see something like this — the request the client sends, and the structured result your function returned:

     tools/call  add  {"a": 2, "b": 3}
    
      result:
        content: [{ "type": "text", "text": "5" }]
        isError: false
    
      ✓ 1 tool available   ·   transport: stdio   ·   0.4 ms

    That’s it. You have a real, spec-compliant MCP server. Now let’s make one worth shipping.

    From toy to useful: a data tool

    An addition tool proves the wiring. A data engineer wants the model to answer questions against real tables — safely. The realistic pattern is a small, sharp toolset: one tool to inspect structure, one to run a constrained query, and a resource for the schema so the model has context before it writes any SQL. Here it is against a local SQLite database so it actually runs:

    import sqlite3
    from fastmcp import FastMCP
    
    mcp = FastMCP("Warehouse")
    DB = "analytics.db"
    
    @mcp.resource("schema://tables")
    def list_tables() -> str:
        """List every table name in the warehouse."""
        con = sqlite3.connect(DB)
        rows = con.execute(
            "SELECT name FROM sqlite_master WHERE type='table'"
        ).fetchall()
        con.close()
        return "\n".join(r[0] for r in rows)
    
    @mcp.tool
    def run_query(sql: str) -> list[dict]:
        """Run a read-only SELECT and return rows as a list of dicts.
        Only SELECT statements are permitted; anything else is rejected."""
        if not sql.strip().lower().startswith("select"):
            raise ValueError("Only SELECT queries are allowed.")
        con = sqlite3.connect(DB)
        con.row_factory = sqlite3.Row
        rows = [dict(r) for r in con.execute(sql).fetchall()]
        con.close()
        return rows
    
    if __name__ == "__main__":
        mcp.run()

    Two design choices are doing real work here. The run_query docstring explicitly states the guardrail (“Only SELECT statements are permitted”) because the model reads that line and will lean on it. And the schema lives in a resource, not a tool, because it’s context the model should be able to pull in cheaply rather than an action it has to spend a tool call on. That distinction is the difference between an agent that guesses column names and one that doesn’t.

    This is also exactly where the ecosystem is converging in the data world. dbt Labs shipped an open-source dbt MCP server so agents can query governed dbt assets instead of hallucinating them — if you already run dbt, that’s a ready-made server before you write a line, and it slots neatly next to the patterns in my Snowflake native dbt integration guide and the everyday commands in the dbt commands cheat sheet. The same logic applies to pipeline operations: the primitives you built in the Streams and Tasks pipeline guide or an OpenFlow ingestion flow are all candidates to expose as narrow, well-named tools.

    stdio or Streamable HTTP: pick deliberately

    MCP defines two standard transports, and choosing between them is mostly a question of where the server lives.

    stdio — local, subprocess

    The client launches your server as a child process and talks to it over standard input and output. This is what powers desktop integrations: the client owns the process, so there’s no network and no per-connection auth to speak of. It’s the default for mcp.run() and the right choice for anything that runs on the same machine as the client.

    Streamable HTTP — remote, multi-client

    Here the server is an independent process exposing a single HTTP endpoint (conventionally /mcp) that handles many clients at once, optionally streaming responses via Server-Sent Events. This replaced the older HTTP+SSE transport from the 2024-11-05 spec — if you find a tutorial wiring up a separate /sse endpoint, it’s aimed at the deprecated design. You switch transports through FastMCP’s run configuration (the exact argument is version-specific, so confirm it against the current docs rather than trusting a copied snippet):

    if __name__ == "__main__":
        mcp.run(transport="http", host="127.0.0.1", port=8000)

    The moment you go remote, authentication stops being optional. The 2025-06-18 revision standardized OAuth 2.1 for exactly this case, and it is — every practitioner I’ve compared notes with agrees — the least fun part of the whole exercise. A universal protocol only helps if access to it is governed, which is the same argument behind industry standards efforts like the Open Semantic Interchange: agreeing on the interface is step one; controlling who gets through it is the real work.

    The cost math nobody does upfront

    Here’s the number that surprises people. Every tool your server exposes carries a schema — name, description, parameter types — and that schema is sent to the model as part of its context on essentially every turn where the tool is available. Tools aren’t free at rest; they’re a standing tax on your context window.

    Say each tool’s schema and docstring run about 200 tokens once you account for parameter descriptions. A tight server with 5 tools costs roughly 1,000 tokens of overhead per call. A kitchen-sink server with 40 tools costs about 8,000 tokens per call before the model has read a single word of the user’s actual question. Across a 50-turn agent session, that’s the difference between ~50,000 and ~400,000 tokens spent purely on tool definitions — 350,000 wasted tokens per session, multiplied by every session, every day. There’s a documented case of a popular server pushing 43 tools into context and measurably degrading the agent’s performance before it did anything at all. The cost shows up twice: on your bill, and in worse tool selection, because the model now has to discriminate among forty near-identical options.

    The fix is boring and effective: fewer tools, sharper boundaries. One run_query beats ten single-purpose query wrappers.

    The gotchas nobody warns you about

    A single print() will corrupt a stdio server. On the stdio transport, stdout is the message channel and must contain only valid MCP messages. A debug print(), a stray library log, a warning banner — any of it injected into stdout garbles the JSON-RPC stream and the client fails in ways that look like anything but the real cause. Log to stderr or a file, never stdout.

    Your docstring is the model’s instruction manual, so treat it like one. The model selects tools by reading their descriptions. “Runs a query” and “Run a read-only SELECT against the analytics warehouse; rejects writes” produce measurably different behavior from the same underlying function. Vague docstrings are a correctness bug, not a style nit.

    Blocking I/O stalls everything. A synchronous tool that makes a slow network or database call blocks the server’s event loop and freezes concurrent requests. For anything that waits on I/O, write an async tool (async def) so the server stays responsive under more than one client.

    Return structured data, not stringified blobs. It’s tempting to json.dumps() everything into a text field. Let FastMCP serialize real Python objects — lists, dicts, dataclasses — so the model receives typed, parseable results instead of having to re-parse your string.

    “It works in the inspector” is not “it works in the client.” The dev inspector is forgiving. Real clients enforce protocol version negotiation and transport details more strictly. Test against the actual client you intend to ship into before calling it done.

    The one principle: design the tool, not the server

    An MCP server is a UX problem wearing a protocol costume — the user just happens to be a language model. FastMCP makes the protocol disappear in ten lines precisely so you can spend your effort on the thing that actually determines whether the server is good: which tools exist, what they’re named, how their descriptions read, and what they refuse to do. Get the protocol working in the first ten minutes, then spend the real time on the interface. The teams whose agents feel sharp aren’t the ones who implemented MCP most cleverly. They’re the ones who designed the smallest, clearest set of tools and wrote docstrings like they meant them.

    Related reading: Build a Databricks AI Agent with GPT-5 · Snowflake Native dbt Integration · dbt Commands Cheat Sheet · Snowflake Interview Questions 2026 · MCP specification (2025-06-18) · FastMCP docs · dbt Labs blog (dbt MCP server)

  • Model Context Protocol Explained in 3 Levels of Difficulty

    Model Context Protocol Explained in 3 Levels of Difficulty

    Every data platform team building agentic pipelines hits the same wall eventually. You want Claude or CoCo to query Snowflake, trigger a dbt run, check an Airflow DAG, and post the result to Slack — one agent, four systems. The naive path is to write four custom connectors. Then someone adds Cursor as a second AI client, and now you need eight connectors. Add a third client and a fifth tool, and you’re maintaining fifteen bespoke integrations, each with its own auth, its own schema, its own failure mode. This is the M×N problem, and it’s the entire reason the Model Context Protocol exists.

    MCP is an open standard — introduced by Anthropic in November 2024 and since handed to neutral, open governance — that turns M×N custom integrations into M+N standardized ones. Every AI client speaks one protocol; every tool exposes itself once through that protocol; any client can now reach any tool with zero custom glue. This article explains MCP the way you’d actually want to learn it: as a problem, then as an architecture, then as the production concerns that only show up once you’re running it for real.

    A flowchart shows 5 steps of an MCP request process, illustrating how data query and response occur between a host, client, server, and back for checking if last night’s load is complete.

    The same five-step shape whether the tool on the other end is Snowflake, dbt, Airflow, or Slack — that uniformity is the entire point of the protocol.

    TL;DR

    → The problem: M AI clients × N tools = M×N custom integrations. Every new client needs a connector to every tool; every new tool needs a connector to every client. This is the wall every multi-tool agent project hits.

    → The architecture: MCP standardizes on three roles — the Host (the AI model reasoning about what to do), the MCP Client (the protocol handler maintaining the connection), and MCP Servers (the tools, exposing capabilities through one shared interface). One protocol, many tools, loosely coupled.

    → The flow: a request comes in → the client sends a tool request over MCP → the server executes the action → the response comes back over MCP → the model gets its result. Five steps, always the same shape, regardless of which tool is on the other end.

    → In production: transport is stdio for local servers or Streamable HTTP for remote ones (what most people still call “SSE,” though the spec has since folded plain SSE into the newer Streamable HTTP transport). Security means authentication, explicit user consent for tool access, audit logging, and guarding against supply-chain risk from untrusted servers.

    → Deployment splits into local servers (full control, data never leaves the machine) and cloud servers (containers or serverless, elastic and shared) — and the choice affects both your security posture and your Snowflake credit bill.

    Level 1 — The problem: why M×N breaks down

    Picture three AI clients your team already uses: a chat assistant, an IDE copilot, and an agent framework running scheduled pipeline checks. Each one can only see what’s inside its own context window — the system prompt, conversation history, and whatever data you’ve explicitly fed it. None of them can natively reach Snowflake, dbt, Airflow, or your internal APIs. To fix that, each client needs its own custom adapter to each tool.

    That’s the M×N integration explosion. Three AI clients times five tools is fifteen custom connections, and every one of them is a maintenance burden: its own auth flow, its own error handling, its own schema mapping, its own breakage when the underlying API changes. Add a client and you add five more connections. Add a tool and you add three more. The graph of arrows gets tangled fast, and nobody owns the whole picture — which is exactly the kind of sprawl that turns into an unaudited security gap, the same failure mode we cover in governing agentic workflows.

    The formula is worth internalizing because it’s the whole justification for a standard protocol: M clients × N tools = M×N integrations. Three AI applications times five tools is fifteen integrations built and maintained by hand. MCP’s entire value proposition is collapsing that multiplication into addition.

    Level 2 — The architecture: Host, Client, Servers

    MCP introduces a standard protocol to connect AI models to tools, built on three roles.

    The Host is the AI model itself — Claude, CoCo, or whatever’s reasoning about the task. It understands the user’s request, decides when a tool is needed, and interprets the results that come back. The Host never talks to a tool directly.

    The MCP Client is the protocol handler sitting between the Host and the outside world. It maintains the connection to MCP servers, handles the messaging and routing, and translates between what the model wants and what the tool’s interface expects.

    The MCP Servers are the tools themselves, each exposing its capabilities through the same standardized interface — a Snowflake warehouse, a dbt project, an Airflow instance, a file system, a Slack channel. From the model’s perspective, querying Snowflake and posting to Slack look structurally identical: a tool request in, a tool response out.

    The request flow is always the same five steps: ① a user request or conversation reaches the Host, which decides a tool is needed; ② the Client sends a tool request over MCP; ③ the server executes the action or accesses the data; ④ the tool response comes back over MCP; ⑤ the results return to the model, which continues reasoning with them. This is the same pattern our MCP in Snowflake CoCo Desktop guide walks through concretely with a live warehouse connection.

    Three properties fall out of this design. One protocol, many tools — you write the integration once per tool, not once per client-tool pair. Loosely coupled and easy to extend — adding a sixth tool means standing up one more server, not touching any existing client. The model gets more context on demand — rather than stuffing every possible data source into the system prompt, the model requests exactly what it needs, when it needs it, which is the same context-discipline argument behind choosing tools over subagents for well-defined operations.

    Level 3 — Production: transport, security, deployment

    Understanding the architecture gets you a working demo. Running MCP in production surfaces three concerns the diagram doesn’t show.

    Transport — how it connects. Local servers use stdio: the client spawns the server as a subprocess and exchanges JSON-RPC messages over standard input and output. It’s simple, fast, and the default recommendation whenever the server and client run on the same machine. Remote servers use Streamable HTTP — what most documentation still calls “SSE” from the protocol’s earlier revision, since the original Server-Sent Events transport has since been superseded by Streamable HTTP, which adds session management and resumability on top of the same idea: the client posts JSON-RPC to an endpoint and receives responses as a stream. Streamable HTTP is what scales — it’s how you’d expose a Snowflake MCP server to multiple teams without spinning up a subprocess per user.

    Security — keeping it safe. MCP delegates enforcement to the host application, but the spec is explicit about the requirements. Authentication verifies both clients and servers before any tool call executes. User consent is required for tool access — a host must surface what’s about to happen and let a human approve it, not silently authorize an agent to act. Audit logs track every action and change, the same discipline behind our ETL audit logger approach applied to tool calls instead of pipeline tasks. And supply-chain risk is real: an MCP server is code you’re trusting to run with whatever privileges you grant it, so an untrusted or malicious server is a live attack surface — treat every third-party server the way you’d treat an unreviewed dependency, not a trusted extension of your own stack. Together these form what’s sometimes called the trusted tool boundary, and it’s the same boundary we cover in depth in giving agents safe access to pipeline metadata.

    Deployment — where it runs. Local servers run on your own machine: full control, data never leaves your environment, and the simplest security story because there’s no network boundary to defend. Cloud servers run in containers or serverless platforms: elastic, shareable across a team, and necessary once more than one person needs the same MCP-exposed tool — but now you’re managing network security, multi-tenant credential scoping, and the cost of always-on compute rather than a subprocess that starts on demand. The choice isn’t purely technical; it’s a data-governance decision as much as an infrastructure one.

    The gotchas nobody warns you about

    “SSE” in most tutorials is already legacy language. The original SSE transport has been folded into Streamable HTTP in current spec revisions, but because so much existing documentation and so many existing servers still use the older terminology, you’ll see “SSE” used loosely to mean “the remote transport” long after the underlying mechanism has moved on. Check which transport a server actually implements before assuming compatibility.

    Access to the server isn’t access to every tool on it. A host connecting to an MCP server doesn’t automatically get every tool that server exposes — tool-level permissions still need to be granted deliberately, the same principle behind the scoped-role pattern in our pipeline metadata security guide.

    Consent fatigue is a real failure mode. If every single tool call pops a confirmation, users start reflexively approving everything, which defeats the purpose of the consent gate. Scope confirmation to genuinely consequential actions — reads can often be pre-approved by policy; writes and destructive actions should always interrupt.

    A local-only mental model breaks the moment you scale. Teams that start with stdio and a single developer’s laptop often don’t plan for the jump to Streamable HTTP and shared cloud servers, and the security model changes meaningfully at that transition — credentials that were fine as environment variables on one machine need proper secrets management the moment the server is reachable over a network.

    The one principle

    MCP replaces M×N custom integrations with M+N standardized ones by giving every AI client and every tool a shared protocol to speak. The architecture — Host, Client, Servers — is simple by design; the real engineering is in Level 3: choosing the right transport, enforcing consent and audit at the trust boundary, and picking local versus cloud deployment deliberately rather than by default. Get the protocol right and adding your sixth tool costs you one server, not five more custom connectors.

    Related reading: Model Context Protocol — official specification · MCP specification blog and release notes · How to Use MCP in Snowflake CoCo Desktop · Governing the AI Agent: CoCo + MCP Security · Giving Agents Safe Access to Pipeline Metadata · Tools vs Subagents: When to Use Each

  • AI Agent Tool Design: What Works and What Doesn’t

    AI Agent Tool Design: What Works and What Doesn’t

    The incident report blamed the model. “The agent called the delete endpoint twice and wiped a partition it shouldn’t have touched.” Everyone nodded, someone filed a ticket to “upgrade to a smarter model,” and the actual cause sat there in plain sight: the delete tool had no idempotency key, no confirmation gate, and a description that said only “deletes records.” The model did exactly what the interface let it do. A better model would have done the same thing faster.

    This is the pattern almost nobody names correctly. Most agent failures look like model mistakes — wrong tool, bad arguments, mishandled errors — but the model is only ever reasoning from the interface you gave it: the tool name, its description, the parameter schema, and the parameter descriptions. When that interface is vague, loosely typed, or missing its guardrails, failures stop being accidents and become predictable. You can throw a stronger model at a bad tool surface and it will still fail, just with more confidence. This is the field guide to designing the tool surface itself — five patterns that work, five that break under real workloads, each paired with its opposite so you can see why it fails, not just what to replace it with.

    If you’re still deciding whether a given capability should even be a tool versus a full subagent, start with our companion piece on tools vs subagents — this article assumes you’ve decided it’s a tool and focuses on designing that tool well.

    TL;DR

    → Most agent failures are tool-design failures, not model failures. The model reasons only from the interface: name, description, schema, parameter docs. Fix the interface and the “model mistakes” largely disappear.

    → One tool, one responsibility. A tool that switches behavior on an action parameter forces the model to pick a mode before it can solve the task. Split it into single-purpose tools with unambiguous names.

    → Tight schemas make invalid states impossible. Enums, validators, and typed fields encode constraints so the model doesn’t guess. Validation fails at the tool boundary instead of as a cryptic downstream error.

    → Descriptions define scope, not just purpose — they say when to use the tool and when not to. Without the “do NOT use this for…” boundary, the model infers scope from the name and picks wrong at scale.

    → Structured error returns (error_coderecoverablesuggested_action) give the model something to branch on. A raw stack trace gives it noise to hallucinate against.

    → The failure modes that pass demos and break in production: thin wrappers over raw APIs, loading every tool into every context, silent partial success, overlapping tool names, and single-call destructive actions.

    Why tool design — not model capability — is the root cause

    A model can only reason from what the tool interface exposes. That’s the entire premise, and it’s worth sitting with because it inverts how most teams debug. When an agent picks the wrong tool, the instinct is to blame the model’s judgment. But the model’s judgment is a function of the tool name, the description, the parameter schema, and the parameter descriptions — nothing else. If two tools have near-identical descriptions, the model isn’t being dumb when it confuses them; it’s being given no basis to tell them apart.

    Anthropic’s engineering team makes this point directly in their guide on writing effective tools for agents: the tool interface is model-facing documentation, and its clarity determines the agent’s reliability more than raw model horsepower does. Stronger models reduce some mistakes, but they cannot reliably compensate for a flawed interface. That framing matters for data teams especially, because the tools we hand agents — warehouse queries, pipeline triggers, catalog lookups — often started life as internal APIs never designed for a reasoning model to consume.

    What works, pattern by pattern

    1. One tool, one responsibility

    Diagram comparing avoidable multi-action tools vs. preferred single-action tools for customer management, showing individual actions as clearer and more responsible than combining them into one tool.

    A tool that multiplexes behavior through an action parameter makes the model choose a mode before it can act. Single-purpose tools remove that whole layer of ambiguity.

    A tool should represent a single, clear operation. When one tool handles create, get, update, delete, and suspend through an action parameter, the model has to figure out which mode to invoke before it can reason about the actual task. That’s a second decision you’ve forced into every call.

    # Avoid: action-based multi-behavior tool
    @tool
    def manage_customer(action: str, customer_id: str | None = None,
                        data: dict | None = None):
        """action: create | get | update | delete | suspend"""
        ...
    
    # Prefer: single-responsibility tools
    @tool
    def create_customer(data: CustomerInput) -> Customer:
        """Create a new customer record."""
        ...
    
    @tool
    def suspend_customer(customer_id: str, reason: str) -> SuspensionResult:
        """Suspend a customer account."""
        ...

    Single-responsibility tools give the model an unambiguous function and give you cleaner error handling and easier observability — the same reasoning behind the audit-per-operation approach in our ETL audit logger guide, where one clear operation per unit makes debugging tractable. One caveat: this is a strong default, not a universal law. Some domains — shell, filesystem, browser, calendar — legitimately benefit from a constrained multi-action interface because the action space is part of the abstraction itself.

    2. Schemas that make invalid states impossible

    The model constructs tool-call arguments by reasoning from your schema. A loose schema means it guesses at constraints; a tight schema encodes them so no guessing is required. This is where Pydantic models with enums and field validators earn their keep:

    from pydantic import BaseModel, Field
    from enum import Enum
    
    class Priority(str, Enum):
        LOW = "low"
        MEDIUM = "medium"
        HIGH = "high"
    
    class CreateTaskInput(BaseModel):
        title: str = Field(
            description="Short, actionable title. Imperative: 'Review PR', not 'PR Review'.",
            min_length=5, max_length=100)
        priority: Priority = Field(
            description="Use HIGH only for blockers affecting other work.",
            default=Priority.MEDIUM)
        due_date: str = Field(
            description="ISO 8601 date: YYYY-MM-DD. Must be a future date.",
            pattern=r"^\d{4}-\d{2}-\d{2}$")

    Enums are especially valuable for small sets of valid values — they eliminate an entire class of plausible-but-invalid outputs. And validation failures surface right at the tool boundary rather than as a confusing error three steps downstream in your pipeline.

    3. Descriptions that define scope, not just purpose

    Tool descriptions are model-facing documentation, and they need to do two things: explain when to use the tool and when not to. Most descriptions only do the first, which leaves the model inferring scope from the tool name — a reliable source of selection errors at scale.

    # Weak: says what it does, not when NOT to use it
    """Search for documents in the knowledge base."""
    
    # Strong: purpose, scope, and boundaries
    """
    Search the internal knowledge base for policies and reference material.
    Use when the user asks about company procedures, product specs, or documented workflows.
    Do NOT use for real-time data (prices, availability, current status) — use get_live_data().
    Returns up to 5 results ranked by relevance. No results means it's not in the knowledge base.

    The “do NOT use this for…” line is the one most teams omit and the one that most improves selection accuracy. A good tool definition draws its boundaries relative to the outcome, not relative to other tools — which is also the cleanest way to avoid the overlap problem covered below.

    4. Structured, actionable error returns

    When a tool fails, the model reads the error and decides what to do next. An unhandled exception produces noise-driven behavior; a structured error gives the model something concrete to branch on:

    class ToolError(BaseModel):
        error_code: str        # machine-readable, for the model to branch on
        message: str           # human-readable description
        recoverable: bool      # can the agent retry?
        suggested_action: str  # what the agent should do next
    
    return ToolError(
        error_code="RECORD_NOT_FOUND",
        message="No user record found with ID 'usr_123'.",
        recoverable=True,
        suggested_action="Call list_users() to get valid IDs before retrying.")

    The recoverable flag and suggested_action field are what actually change agent behavior. Without them, models retry non-retryable errors — burning tokens and warehouse credits — or abandon recoverable ones. This matters doubly when the tool touches sensitive systems; see our guide on giving agents access to pipeline metadata safely for how structured returns keep a compromised agent’s blast radius small.

    5. Idempotent state-changing operations

    Every tool that mutates state — creates a record, sends a message, triggers a pipeline run — must be safe to call twice, because agents retry, networks fail, and the reasoning loop may fire a second call when confirmation of the first never arrived. The simplest defense is an idempotency key on every write:

    @tool
    def send_email(to: str, subject: str, body: str,
        idempotency_key: str = Field(
            description="Unique key for this send. Hash of recipient+subject+timestamp. "
                        "Same key on retry returns the original result without re-sending.")
    ) -> dict:
        """Send an email. Idempotent: same key will not trigger a second send."""
        existing = idempotency_store.get(idempotency_key)
        if existing:
            return existing
        result = email_service.send(to=to, subject=subject, body=body)
        idempotency_store.set(idempotency_key, result, ttl=86400)
        return result

    Without idempotency, a transient failure quietly becomes a duplicate action — a doubled Slack alert, a re-run backfill, a second funds transfer.

    What doesn’t work

    1. Thin wrappers around unfiltered APIs

    Pointing an agent at a REST API and exposing it raw is the most common shortcut and the most common source of production failures. As Anthropic’s tool-writing guide notes, APIs built for developers expose far more than an agent needs: responses packed with hundreds of fields, pagination, opaque internal IDs, and error codes that require domain knowledge to interpret. A purpose-built wrapper handles pagination internally, projects only the fields the agent needs, and maps API errors to the structured ToolError format above. The flip side: over-wrapping into dozens of hyper-narrow tools fragments the surface. The goal is a consistent, agent-friendly abstraction — not maximal abstraction.

    2. Loading all tools into every context

    Diagram comparing two tool-loading approaches: left panel shows “All tools, every call” with many tool names; right panel shows “Only the current step’s tools” with fewer, step-specific tools. Accuracy drops as more tools are loaded.

    Agent accuracy drops as the tool catalog grows. Loading only the tools relevant to the current step keeps the decision space small and the token budget lean.

    Accuracy degrades as the tool catalog grows. LongFuncEval, a 2025 study on tool-calling across long contexts, found performance drops substantially as the tool catalog grows — even in models with 128K context windows. Loading every tool into every system prompt compounds it by eating token budget before any task content is processed. The fix is dynamic loading: determine which tools are relevant to the current step and include only those.

    STEP_TOOL_MAP = {
        "research": ["search_documents", "search_web", "get_url_content"],
        "write":    ["create_document", "update_document", "format_text"],
        "send":     ["send_email", "post_to_slack", "create_calendar_event"],
    }
    
    def get_tools_for_step(step_type: str, available_tools: list) -> list:
        relevant = STEP_TOOL_MAP.get(step_type, [])
        return [t for t in available_tools if t.name in relevant]

    This is the tool-level analogue of scoping a subagent’s tools, one of the justifications for reaching for a subagent at all in our tools vs subagents guide.

    3. Silent partial success

    Partial success becomes a bug when a tool completes only part of the work but returns something that looks fully successful, so the agent proceeds with a misleading view of system state. It usually happens when a tool swallows internal failures:

    # Silently misleads the agent
    @tool
    def bulk_create_tasks(tasks: list) -> dict:
        created = []
        for task in tasks:
            try:
                created.append(task_api.create(task).id)
            except Exception:
                pass  # silent failure: this is the bug
        return {"created": created}
    
    # Makes partial success explicit
    @tool
    def bulk_create_tasks(tasks: list) -> BulkCreateResult:
        created, failed = [], []
        for task in tasks:
            try:
                created.append(task_api.create(task).id)
            except TaskCreationError as e:
                failed.append({"input": task.title, "reason": str(e)})
        return BulkCreateResult(
            created_ids=created, failed_items=failed,
            success=len(failed) == 0,
            partial_success=len(created) > 0 and len(failed) > 0)

    The partial_success flag gives the model a branch: retry the failed items, surface the partial result, or halt. Silent swallowing gives it a false green light.

    4. Overlapping tool names and descriptions

    When two tools do similar things, the model reasons about which to use on every single call — burning tokens and introducing errors. Classic offenders: search_documents and find_documents with identical purpose; get_user and fetch_user_profile with unclear difference; create_taskadd_task, and new_task for one operation. Renaming alone isn’t the fix. Every tool needs a purpose describable without reference to the others — if a description needs “unlike X, this one…” to make sense, that’s a design problem. This is the same governance discipline we apply in governing agentic workflows: a tool surface audited before deployment, not after an incident.

    5. Destructive actions without a confirmation gate

    A diagram compares single-step deletion, which is irreversible, with a two-step staged deletion using a token and user confirmation to prevent immediate destructive actions.

    An irreversible action should never be completable in one reasoning step. Staging plus a short-lived confirmation token forces a deliberate second call.

    Any tool that takes an irreversible action — deleting records, messaging real users, executing transactions — needs a structural two-step confirmation, not an in-prompt “are you sure?” Separate staging from execution and require a short-lived token between them:

    @tool
    def stage_deletion(record_ids: list[str], reason: str) -> StagedDeletion:
        """Stage records for deletion. Does NOT delete anything.
        Returns a confirmation token that expires in 60 seconds."""
        token = generate_deletion_token(record_ids)
        staged_deletions[token] = {"ids": record_ids, "expires": now() + 60}
        return StagedDeletion(token=token, records_to_delete=len(record_ids),
                              expires_in_seconds=60)
    
    @tool
    def confirm_deletion(token: str) -> DeletionResult:
        """Execute a staged deletion. IRREVERSIBLE. Confirm only after user approval."""
        staged = staged_deletions.get(token)
        if not staged or staged["expires"] < now():
            raise ValueError("Token invalid or expired. Stage the deletion again.")
        # proceed

    Two distinct calls mean the model can’t complete a destructive operation in a single reasoning step — that’s the point. One caution: two-step flows aren’t sufficient on their own. Production systems also need single-use tokens, strict session binding, and replay protection so a token can’t be reused or executed across sessions.

    The decisions at a glance

    Every one of these is a design decision you make explicitly or make by accident: tool scope (single responsibility, not an action parameter); schema (tight enums and validators, not free strings); descriptions (scope boundaries and when-not-to-use, not happy path only); write operations (idempotent with keys, not fire-and-forget); error returns (structured with error_code/recoverable/suggested_action, not raw exceptions); tool count (dynamic per-step loading, not all tools in every context); API wrapping (purpose-built agent-facing schema, not unfiltered exposure); partial success (an explicit flag, not silent swallowing); destructive actions (two-step staging, not single-call); and tool overlap (semantically distinct and audited, not similar names competing).

    The one principle

    The agent reasons only from the interface you expose, so most “model failures” are design failures you can fix at the tool boundary. Give each tool one responsibility, a schema tight enough to make invalid calls impossible, a description that says when not to use it, structured errors it can branch on, and a confirmation gate on anything irreversible. Do that and a mid-tier model behaves reliably. Skip it and the smartest model available will still delete the wrong partition — confidently, and on the first try.

    Related reading: Anthropic: Writing effective tools for agents · LongFuncEval: tool-calling in long contexts · Pydantic documentation · Tools vs Subagents: When to Use Each · Giving Agents Safe Access to Pipeline Metadata · Governing the AI Agent: CoCo + MCP Security

  • Tools vs Subagents: Building Effective AI Agents Without Over-Engineering

    Tools vs Subagents: Building Effective AI Agents Without Over-Engineering

    A data engineer I know spent three weeks building a “multi-agent data quality system.” It had an orchestrator agent, a profiling subagent, an anomaly-detection subagent, and a remediation subagent, all passing messages around. It was elegant. It was also slower, more expensive, and harder to debug than the thing it replaced — which was a single agent that called four Python functions. When a check failed at 2 a.m., nobody could tell which agent had made the wrong call, because the reasoning was scattered across four isolated context windows. He rebuilt it in an afternoon as one agent with four tools, and it has run clean ever since.

    That story is the whole debate in miniature. Every agent you build in a data pipeline hits the same fork: a task needs doing — query a warehouse, validate a schema, profile a table, summarize a run — and you have to decide whether it should be a tool the agent calls directly, or a subagent that handles the work in its own reasoning loop. Get it wrong toward tools and you get a bloated agent drowning in its own context. Get it wrong toward subagents and you’ve bought coordination overhead, extra LLM calls, and debugging pain for a problem a function would have solved. This is the guide to making that call correctly, every time, without over-engineering.

    TL;DR

    → A tool executes your code — an API call, a SQL query, a file operation, a calculation. It’s fast, deterministic, cheap, and its result lands directly in the agent’s context. Tools don’t reason; they execute.

    → A subagent is a separate LLM call with its own system prompt, its own context window, and often its own tools. It runs a full multi-step reasoning loop and returns only a summary. From the orchestrator’s view it looks like a tool call — send a task, get a result — but a whole reasoning process happens in between.

    → Default to tools. If you can write the behavior as a function with typed inputs and outputs and it doesn’t need multi-step reasoning, it’s a tool. This covers the large majority of pipeline agent work.

    → Reach for a subagent only when the task needs genuine multi-step reasoning, when its intermediate work would pollute the orchestrator’s context, when it needs its own scoped tool set, or when independent tasks can run in parallel.

    → The decision reduces to three questions: is it execution or reasoning, does the intermediate work matter to the orchestrator, and can it run independently?

    → Every subagent adds a context window, a reasoning loop, and a handoff — more latency, more cost, more moving parts. The contract that keeps multi-agent systems debuggable: pass tasks down, pass conclusions back up.

    What a tool actually is

    A tool is a capability the agent uses to act on the world beyond the model’s own knowledge. In a data-engineering context, tools are the functions you already write: a Snowflake query, a call to the Airflow REST API, a dbt run trigger, a file read from S3, a schema validation, a row-count check. You expose them to the model through a defined interface — typed inputs, typed outputs — and the model decides when to call them, not how they run.

    The interaction loop is simple. The model gets a task and decides it needs external data or an action. It emits a structured tool call with arguments. Your application runs the tool and returns the result. The result goes back into the same conversation, and the model keeps reasoning. The key property: the tool does no reasoning itself. It runs a predefined operation and returns data. All the planning and interpretation stays with the model.

    Because a tool executes code rather than spinning up another LLM, it’s fast, deterministic, and cheap. A SQL query that returns a row count costs you the query, not an inference cycle. That’s why tools are the primary way agents touch the outside world — and why they should be your default.

    What a subagent actually is

    A diagram compares Tool Call and Subagent Call methods, showing their workflows, reasoning styles, and differences in speed, cost, and latency. Tool is fast and cheap; Subagent has extra reasoning but higher latency.

    From the orchestrator’s view both look the same — send a task, get a result. The difference is what happens in between: a tool runs code; a subagent runs a whole reasoning loop in its own context.

    A subagent is a separate LLM call — a distinct agent instance with its own system prompt, its own context window, and often its own tools — that receives a task, works through it independently, and returns a result to the orchestrating agent. From the orchestrator’s perspective, calling a subagent looks identical to calling a tool: send a task, get a result back.

    What differs is the middle. A subagent runs its own multi-step reasoning loop, potentially makes its own tool calls, and manages its own state. The orchestrator has no visibility into that process; it only sees the summary at the end. That isolation is the whole point — and also the whole cost. The single most important consequence is the context window: when an agent calls a tool, the result lands in the same context it’s already reasoning in. When it spawns a subagent, that subagent starts fresh with only what it was handed, and everything it does stays sealed off.

    Tools vs subagents: the differences that matter

    The one-line version: tools execute code, subagents execute reasoning. Everything else follows from that. A tool runs your code in the orchestrator’s shared context with no reasoning, structured error returns, execution-only cost, and low latency — and when it breaks, it’s a bad schema, an API failure, or wrong arguments, all visible in the orchestrator’s context. A subagent runs another LLM in an isolated context with a full reasoning loop, additional inference cost, higher latency, and partial visibility — and when it breaks, it’s a hallucination, lost context, or a coordination failure that’s much harder to trace.

    For a data pipeline, that visibility difference is the one that bites. A tool’s result — a row count, a query output, a validation pass/fail — sits in the orchestrator’s context where you can inspect it. A subagent’s internal steps are opaque by design; you get the conclusion, not the path to it. When you’re debugging why a pipeline agent did something wrong, opaque reasoning is exactly what you don’t want unless the isolation is buying you something concrete.

    When a tool is the right choice

    Use a tool when the operation is well-defined, deterministic, and doesn’t need multi-step reasoning. In practice, that’s most of what a pipeline agent does:

    Call an external system. Fetch a table’s metadata, trigger a dbt model, post a run summary to Slack, query the warehouse. These are pure execution — the model decides to call them, your code runs them.

    Transform or validate data. Run a regex, cast a type, compute a hash, check a row count against a threshold, validate a schema against a contract. Deterministic operations belong in functions, not LLM calls.

    Read or write. Open a file in S3, write a manifest, check whether a partition exists, update a metadata row. Predictable and fast as direct tool calls.

    Run a search or query. A SQL query, a vector search over a table catalog, a lookup in your data dictionary. The query runs deterministically and returns results; the model interprets them, but the query itself is a tool.

    The practical test is one sentence: if you can write the behavior as a Python function with typed inputs and outputs, and it doesn’t need to reason through multiple steps, it should be a tool.

    When a subagent earns its complexity

    Diagram titled “When a Subagent Is Worth the Trouble” with four color-coded boxes listing scenarios: Multi-step reasoning, Parallel work, Own tool set, Isolate noisy work, each with brief descriptions and examples.

    The four situations where a subagent’s added complexity actually pays for itself. If none of these apply, a tool is the better choice.

    Use a subagent when the task genuinely needs one of these four things:

    Non-obvious intermediate steps. “Investigate why last night’s pipeline run took three times as long” involves deciding what to check, reading logs, forming a hypothesis, checking the next thing, and synthesizing a root cause. Each step depends on the last. That’s a reasoning process, and it belongs in its own context.

    Parallelizable work. Profiling twenty tables independently runs far faster across twenty concurrent subagents than sequentially in one context. When subtasks don’t depend on each other, parallel subagents are a real speedup.

    Its own tool set. A code-writing subagent needs a code executor and file tools; a data-profiling subagent needs warehouse-query tools. Giving the orchestrator every tool at once creates tool overload — and agent accuracy is known to degrade as the tool count grows. Scoping tools per subagent keeps each agent’s decision space small and its tool-calling accurate.

    Noisy intermediate output. A single query result is compact and useful in context. A multi-step investigation spanning dozens of query outputs is noise. Isolating that work in a subagent and surfacing only the conclusion keeps the orchestrator’s reasoning clean. Context isolation also improves reliability — a subagent in a fresh context can’t be distracted by the orchestrator’s accumulated history.

    The three-question decision framework

    Most of the time the choice comes down to three questions, in order.

    1. Is the task primarily execution or reasoning? A well-defined operation with predictable inputs and outputs — a query, an API call, a calculation, a file op — is a tool. A task that requires exploring, analyzing, synthesizing, or making a chain of dependent decisions is a subagent.

    2. Does the intermediate work matter to the orchestrator? If the result is small and immediately useful — a row count, a validation result — keep it in context as a tool. If the task generates a lot of intermediate work — multiple queries, document reviews, iterations — a subagent isolates that and returns only the conclusion.

    3. Can the task run independently? A tool runs inline as part of the workflow and returns before the workflow continues. A subagent fits when the work can be delegated, run independently, or executed in parallel — processing many tables, researching many topics, coordinating specialized workflows.

    The over-engineering trap

    The most common mistake — the one from the opening story — is reaching for subagents before you need them. A subagent can make an architecture cleaner, but it also adds another context window, another reasoning loop, and another handoff. That’s more latency, more cost, and more moving parts to debug. In a lot of cases a well-designed tool is simply enough, and a separate agent creates more overhead than value.

    The rule of thumb: start with a single agent and a small set of well-designed tools. Introduce subagents only when they solve a specific problem tools cannot solve cleanly — isolating large amounts of intermediate work, enabling parallel execution, or giving a complex task its own reasoning space. The question to ask before adding one: what does this subagent actually buy me? If the answer is “a little processing before returning a result,” a tool is enough. If it’s “independent reasoning, context isolation, specialized tools, or parallelism,” the subagent is justified. Tools are the default; subagents are the exception you can defend.

    What adding a subagent actually costs

    A diagram showing the Handoff Contract, where an Orchestrator Agent passes tasks down to a Subagent, which then passes results up. Clean tasks and summaries vs shared mutable state are compared.

    The contract that keeps multi-agent systems debuggable: a focused task goes down, a concise conclusion comes back up — never the full trail of intermediate work.

    Calling a tool is simple: inputs in, result out. Calling a subagent means delegating part of the thinking, and that has a cost beyond the extra LLM call. The orchestrator has to define the task clearly enough for the subagent to work alone, because the subagent doesn’t inherit the orchestrator’s goals, assumptions, or conversation history. It only knows what it was handed.

    So good subagent architectures live or die on clean handoffs. The orchestrator sends a focused, self-contained task. The subagent does its own reasoning and tool use. The subagent returns a concise result — “identified the three slowest tasks and the shared root cause,” not every log line and intermediate query that led there. Keeping that boundary clean does two things: it stops the orchestrator’s context from filling with intermediate noise, and it makes the system debuggable because each subagent has one clear responsibility and one well-defined output.

    The rule that captures it: pass tasks down, pass conclusions back up. Clean task in, clean summary out is the contract. The moment you let subagents share mutable state or pass partial results back mid-task, you’ve introduced coordination complexity that quickly outgrows the problem you started with.

    The one principle

    Tools execute code; subagents execute reasoning. Default to tools — if the work fits a typed function that doesn’t reason across steps, it’s a tool — and add a subagent only when it buys you something concrete: multi-step reasoning, context isolation, a scoped tool set, or parallelism. When you do delegate, pass tasks down and conclusions back up, and nothing else. The best agent architecture is the simplest one that solves the problem, and for most pipeline work that’s one agent with a handful of sharp tools — not a committee of agents talking to each other at 2 a.m.

    Related reading: Anthropic: Building Effective Agents · Google Cloud: Subagents vs agents-as-tools · Governing the AI Agent: Securing CoCo and MCP Workflows · Giving AI Agents Access to Pipeline Metadata Safely · How to Use MCP in Snowflake CoCo Desktop